16 Chi-Square Test of Independence
In the previous chapter, we used the chi-square statistic to test whether a single categorical variable follows a particular distribution. In this chapter, we extend the chi-square framework to two-way tables, where we have two categorical variables and want to assess whether they are associated. The key question becomes: is the distribution of one variable the same across all levels of the other variable, or does the distribution shift depending on the group? As with our other inference methods, we begin with a simulation-based approach (randomization) and then introduce the mathematical chi-square approximation.
Note that with two-way tables, there is not an obvious single parameter of interest. Instead, research questions focus on how the proportions of the response variable change (or not) across the different levels of the explanatory variable. Because there is no single population parameter to estimate, we focus on hypothesis testing (and not confidence intervals).
16.1 Randomization test of independence
16.1.1 Case study: The iPod experiment
We all buy used products – cars, computers, textbooks – and we sometimes assume the sellers will be forthright about any underlying problems. Researchers recruited 219 participants in a study where they would sell a used iPod that was known to have frozen twice in the past. The participants were incentivized to get as much money as they could. The researchers wanted to understand what types of questions would elicit the seller to disclose the freezing issue.
The buyers (who were collaborating with the researchers) asked one of three scripted questions:
- General: “What can you tell me about it?”
- Positive Assumption: “It does not have any problems, does it?”
- Negative Assumption: “What problems does it have?”
The results are shown below:
| Question | Disclose problem | Hide problem | Total |
|---|---|---|---|
| General | 2 | 71 | 73 |
| Positive assumption | 23 | 50 | 73 |
| Negative assumption | 36 | 37 | 73 |
| Total | 61 | 158 | 219 |
The data suggest that asking “What problems does it have?” was the most effective at getting the seller to disclose the past freezing issues. But could we see these results due to chance alone, or is this evidence that some questions are more effective at getting to the truth?
16.1.2 Expected counts in two-way tables
The hypothesis test is about assessing whether there is convincing evidence that the question asked was related to whether the seller disclosed the problem. In other words, we want to check whether the buyer’s question was independent of whether the seller disclosed a problem.
From the experiment, the overall proportion of sellers who disclosed the freezing problem was \(61/219 = 0.2785\). If there really is no difference among the questions and 27.85% of sellers were going to disclose regardless, how many of the 73 people in the General group would we have expected to disclose?
We would predict that \(0.2785 \times 73 = 20.33\) sellers would disclose the problem. We observed far fewer than this, though it is not yet clear if that is due to chance variation or because the questions truly differ in effectiveness.
If the questions were actually equally effective, meaning about 27.85% of respondents would disclose the freezing issue regardless of what question they were asked, about how many sellers in the Positive Assumption group would we expect to hide the freezing problem?
Show answer
We would expect \((1 - 0.2785) \times 73 = 52.67\).We can compute the expected number for all cells using the row totals, column totals, and table total. For instance, the proportion who disclosed overall was \(61/219\). Multiplying by each row total:
\[ \begin{aligned} \frac{61}{219} \times 73 &= 20.33 \quad \text{(for each question group)} \end{aligned} \]
More generally, this can be rewritten as:
\[ \text{Expected Count}_{\text{row } i, \text{ col } j} = \frac{(\text{row } i \text{ total}) \times (\text{column } j \text{ total})}{\text{table total}} \]
Computing expected counts in a two-way table.
To calculate the expected count for the \(i^{th}\) row and \(j^{th}\) column, compute:
\[\text{Expected Count}_{\text{row } i, \text{ col } j} = \frac{(\text{row } i \text{ total}) \times (\text{column } j \text{ total})}{\text{table total}}\]
Using this formula, the observed counts with expected counts in parentheses are:
| Question | Disclose problem | Hide problem | Total |
|---|---|---|---|
| General | 2 (20.33) | 71 (52.67) | 73 |
| Positive assumption | 23 (20.33) | 50 (52.67) | 73 |
| Negative assumption | 36 (20.33) | 37 (52.67) | 73 |
| Total | 61 | 158 | 219 |
16.1.3 The observed chi-square statistic
The chi-square test statistic for a two-way table is found by computing the squared standardized difference for every cell in the table and summing them:
\[ \begin{aligned} &\text{General formula} && \frac{(\text{observed count} - \text{expected count})^2} {\text{expected count}} \\ &\text{Row 1, Col 1} && \frac{(2 - 20.33)^2}{20.33} = 16.53 \\ &\text{Row 2, Col 1} && \frac{(23 - 20.33)^2}{20.33} = 0.35 \\ & \hspace{9mm}\vdots && \hspace{13mm}\vdots \\ &\text{Row 3, Col 2} && \frac{(37 - 52.67)^2}{52.67} = 4.66 \end{aligned} \]
Adding the computed value for each cell gives the chi-square test statistic:
\[X^2 = 16.53 + 0.35 + \dots + 4.66 = 40.13\]
16.1.4 Variability of the statistic
Is 40.13 a big number? Does it indicate that the observed and expected values are really different, or is it a value we might expect to see just due to natural variability?
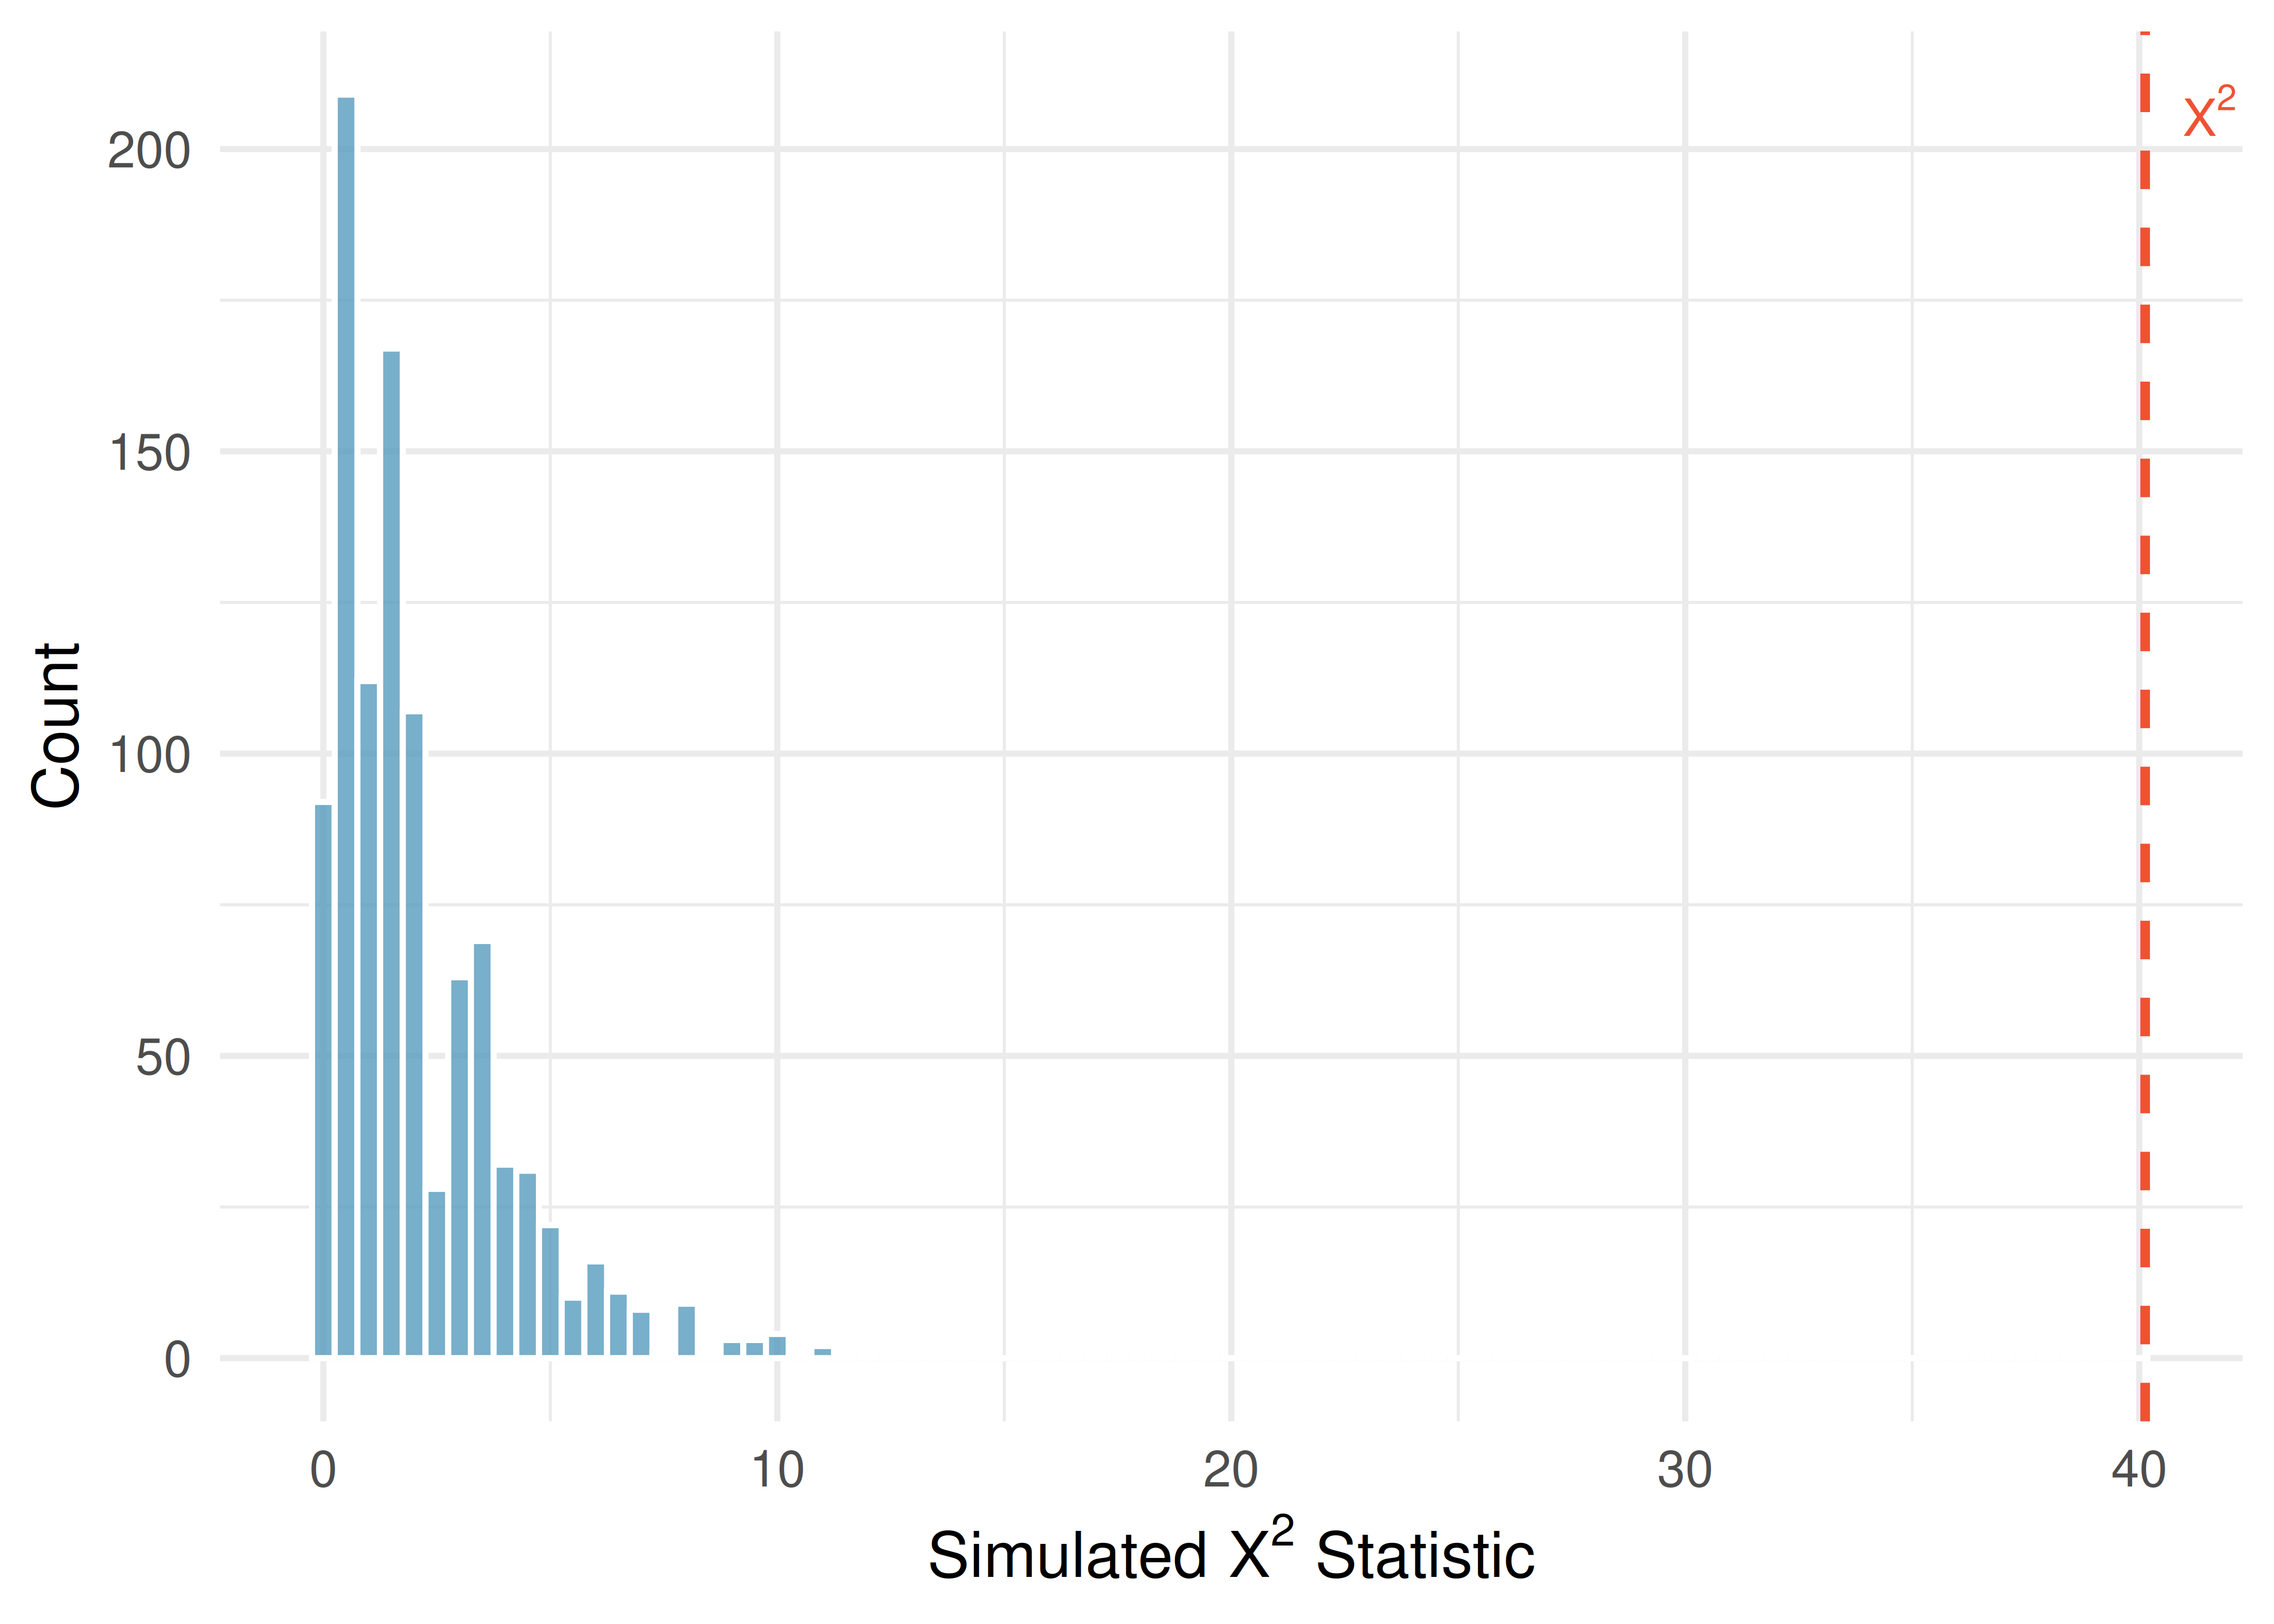
Assuming that the individuals would disclose or hide the problems regardless of the question they were given (i.e., that the null hypothesis is true), we can randomize the data by reassigning the 61 disclosed problems and 158 hidden problems to the three question groups at random. This is exactly the same type of randomization we used in previous chapters.
One such randomization might produce:
| Question | Disclose problem | Hide problem | Total |
|---|---|---|---|
| General | 29 | 44 | 73 |
| Positive assumption | 15 | 58 | 73 |
| Negative assumption | 17 | 56 | 73 |
| Total | 61 | 158 | 219 |
Computing the chi-square statistic for this randomized table:
\[ \begin{aligned} X^2 &= \frac{(29 - 20.33)^2}{20.33} + \frac{(15 - 20.33)^2}{20.33} + \cdots + \frac{(56 - 52.67)^2}{52.67} = 8 \end{aligned} \]
This is much smaller than 40.13.
16.1.5 Observed statistic vs. null chi-square statistics
One randomization is not sufficient. We generate many chi-square statistics under the null hypothesis to build a null distribution.
The observed value is so far from the null statistics that the simulated p-value is essentially zero. We conclude that the decision of whether to disclose the iPod’s problem is changed by the question asked. We use the causal language of “changed” because the study was a randomized experiment.
Note that with a chi-square test, we only know that the two variables (question type and response) are related (i.e., not independent). We are not able to claim which specific type of question causes which specific type of response.
16.2 Mathematical model for test of independence
16.2.1 The chi-square test of independence
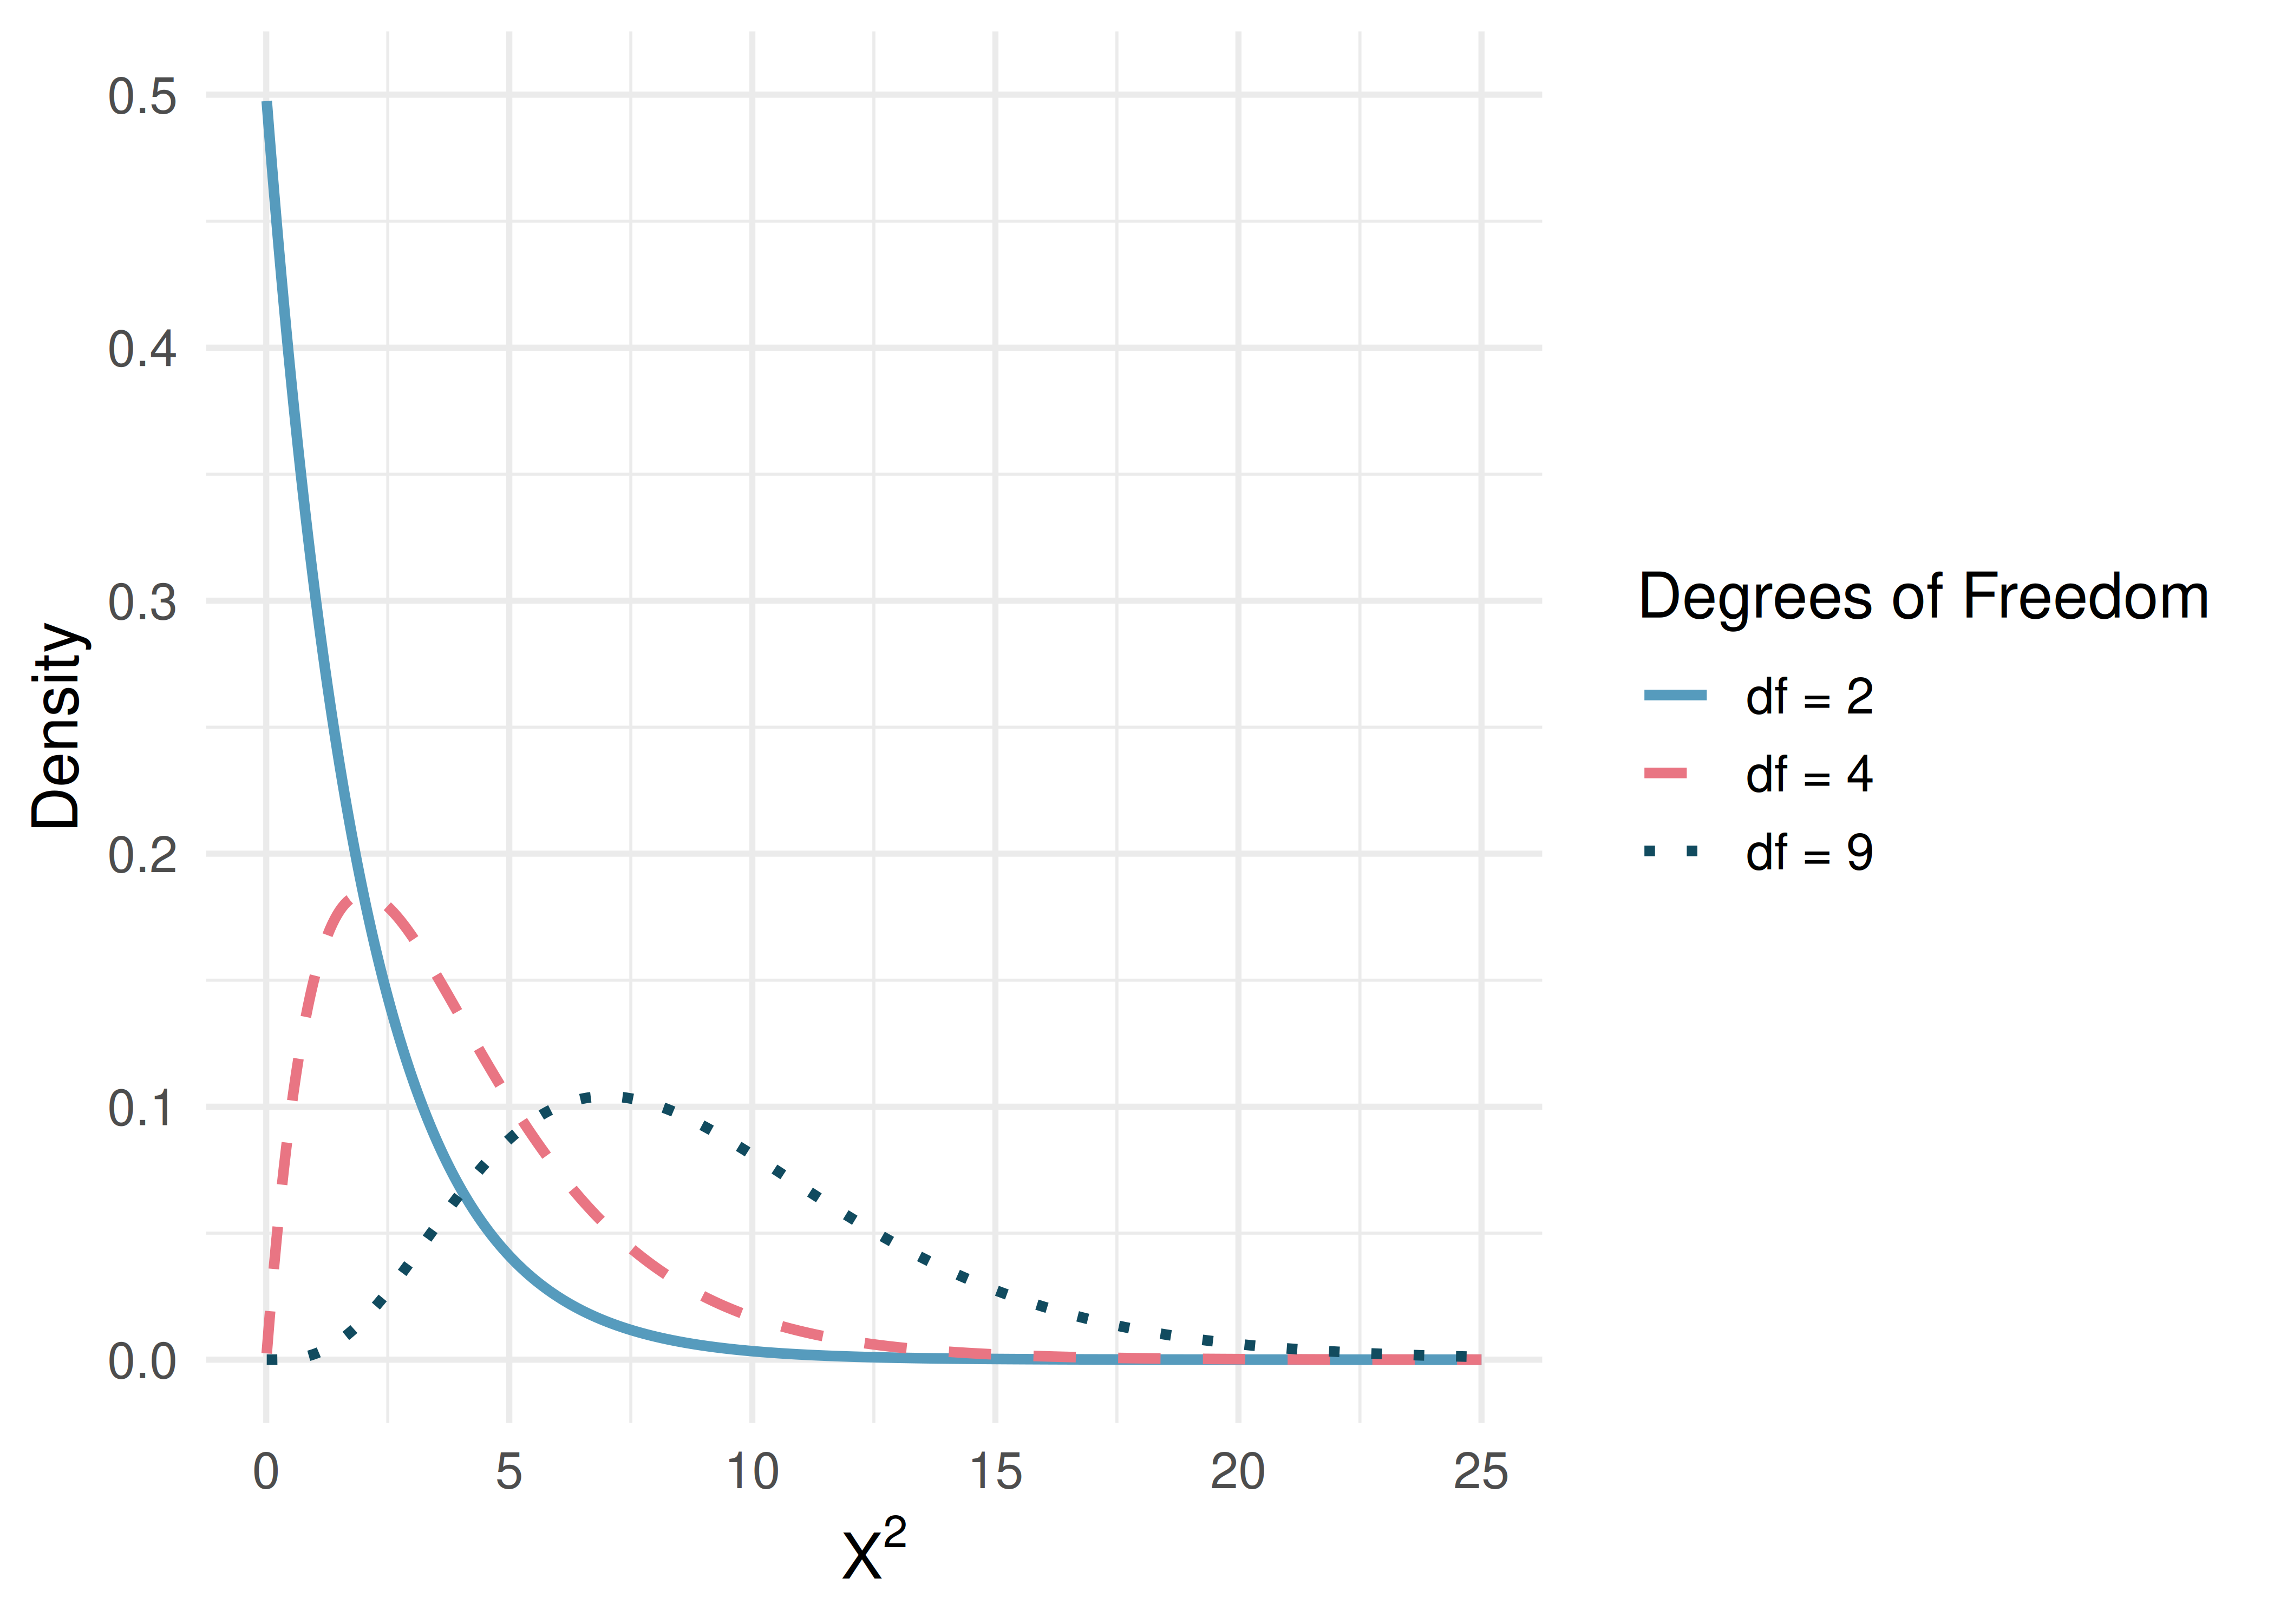
The chi-square test statistic follows a chi-square distribution when the null hypothesis is true and the conditions are met. For two-way tables, the degrees of freedom are:
\[df = (R - 1) \times (C - 1)\]
where \(R\) is the number of rows and \(C\) is the number of columns.
16.2.2 Variability of the chi-square statistic
As it turns out, the chi-square test statistic follows a chi-square distribution when the null hypothesis is true. For two-way tables, the degrees of freedom equal \((R-1) \times (C-1)\). In the iPod example, this is \((3-1) \times (2-1) = 2\).
The test statistic for assessing independence between two categorical variables is \(X^2\).
The \(X^2\) statistic is a ratio of how the observed counts differ from the expected counts, standardized by the expected counts:
\[X^2 = \sum_{i,j} \frac{(\text{observed count} - \text{expected count})^2}{\text{expected count}}\]
When the null hypothesis is true and the conditions are met, \(X^2\) has a chi-square distribution with \(df = (R-1) \times (C-1)\).
Conditions:
- Independent observations
- Large samples: at least 5 expected counts in each cell
Computing degrees of freedom for a two-way table.
When applying the chi-square test to a two-way table, use \(df = (R-1) \times (C-1)\) where \(R\) is the number of rows and \(C\) is the number of columns.
16.2.3 Finding the p-value
We can safely assume that the observations in the iPod experiment are independent (the question groups were randomly assigned). Each expected count exceeds 5, so the conditions for using the chi-square distribution are met. The test statistic \(X^2 = 40.13\) follows a chi-square distribution with 2 degrees of freedom.
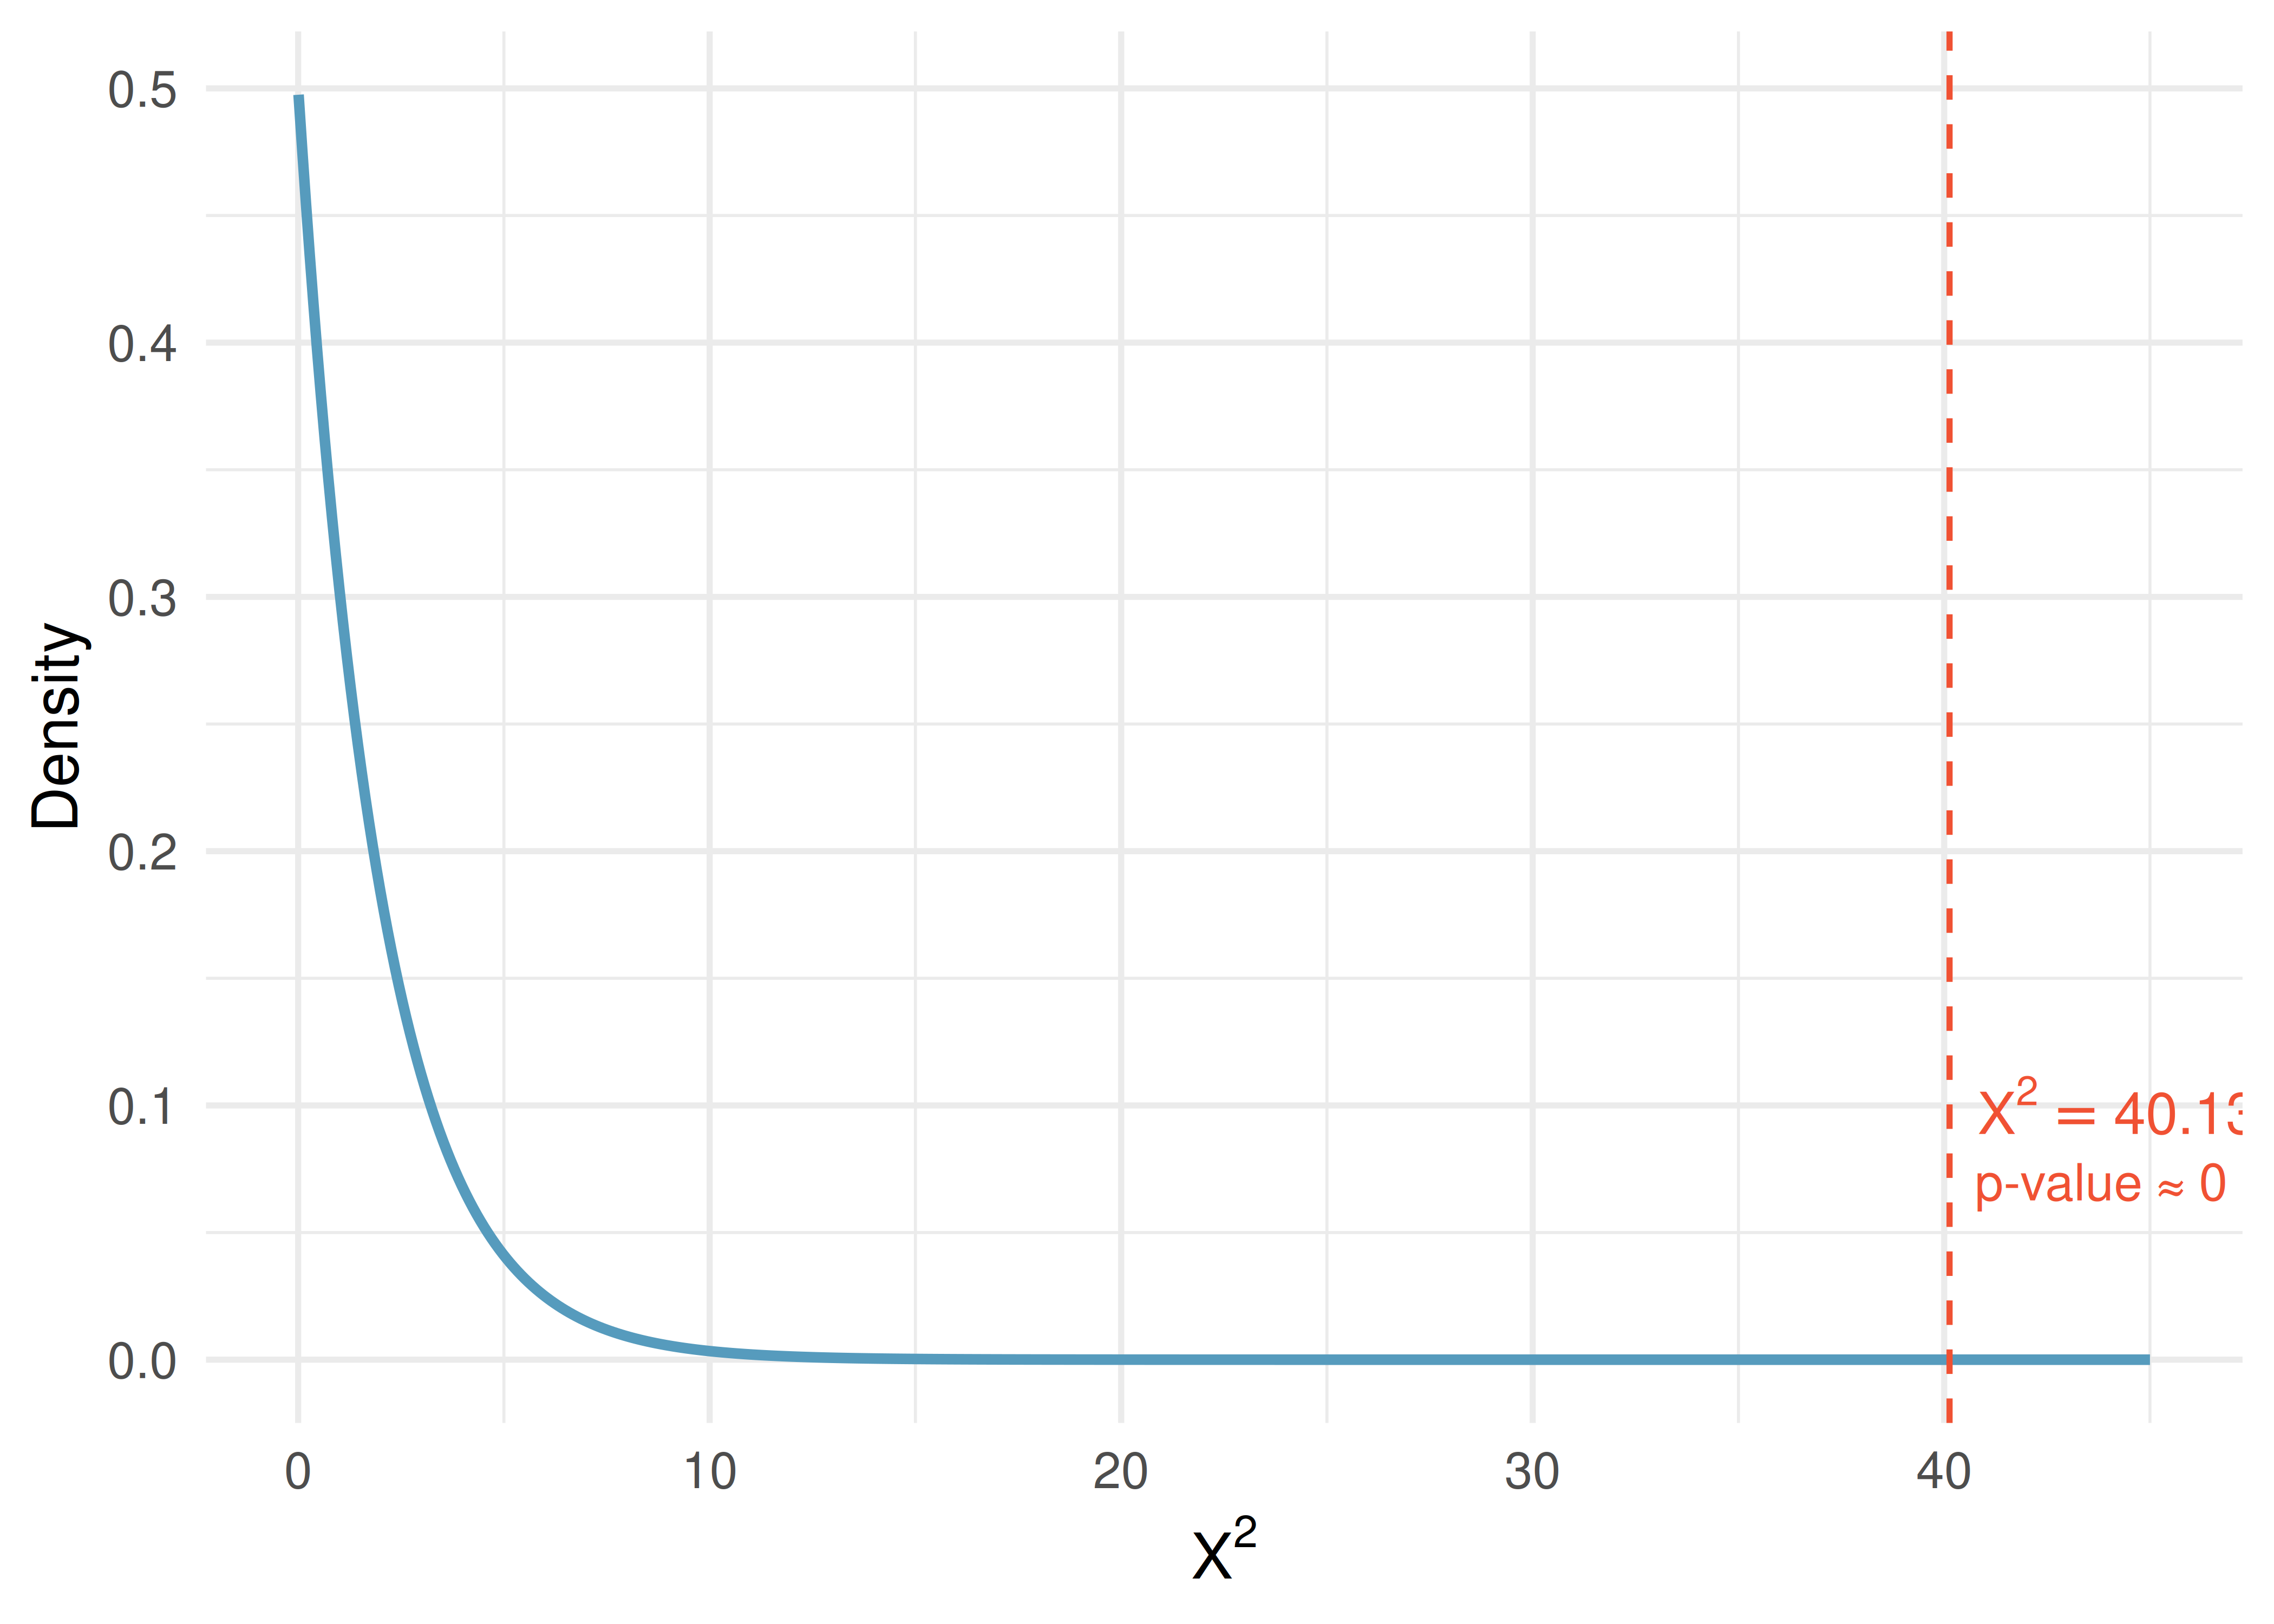
Find the p-value and draw a conclusion about whether the question affects the seller’s likelihood of reporting the freezing problem.
Using a chi-square distribution with 2 degrees of freedom, the tail area above \(X^2 = 40.13\) is approximately 0.000000002.
Using a discernibility level of \(\alpha = 0.05\), the null hypothesis is rejected since the p-value is much smaller. The data provide convincing evidence that the question asked did affect a seller’s likelihood to tell the truth about problems with the iPod.
16.2.4 Another example: Diabetes treatment
An experiment evaluated three treatments for Type 2 Diabetes in patients aged 10–17 who were being treated with metformin. The three treatments were: continued metformin alone (met), metformin combined with rosiglitazone (rosi), or a lifestyle intervention program. Each patient had a primary outcome of either failure (lacked glycemic control) or success (maintained glycemic control). The results are shown below.
| Treatment | Failure | Success | Total |
|---|---|---|---|
| met | 120 | 114 | 234 |
| rosi | 90 | 143 | 233 |
| lifestyle | 109 | 123 | 232 |
| Total | 319 | 380 | 699 |
What are appropriate hypotheses for this test?
- \(H_0\): There is no difference in the effectiveness of the three treatments.
- \(H_A\): There is some difference in effectiveness between the three treatments, e.g., perhaps the rosiglitazone treatment performed better than lifestyle intervention.
Compute the expected counts for each of the six cells in the diabetes treatment table.
Show answer
Row 1, Col 1: \(\frac{234 \times 319}{699} = 106.8\). Row 1, Col 2: \(\frac{234 \times 380}{699} = 127.2\). Row 2, Col 1: \(\frac{233 \times 319}{699} = 106.3\). Row 2, Col 2: \(\frac{233 \times 380}{699} = 126.7\). Row 3, Col 1: \(\frac{232 \times 319}{699} = 105.9\). Row 3, Col 2: \(\frac{232 \times 380}{699} = 126.1\).Note: when analyzing 2-by-2 contingency tables (where both variables have only two categories), it is generally preferable to use the two-proportion methods from earlier chapters.
See it in action. Open the Chi-Square Independence walkthrough for a guided pass through framing → conditions → running the test → reading standardized residuals. Or open the Chi-Square Test or Randomization Chi-Square directly on your own data.
16.3 Comparing the simulation and chi-square approaches
Both the randomization test and the mathematical chi-square test address the same question: are two categorical variables independent? The two approaches generally give very similar results, especially when the sample size is large and the expected counts are well above 5.
The randomization test is more flexible because:
- It does not require any minimum expected count.
- It works well even for small samples.
- It requires no distributional assumptions beyond independence.
The mathematical chi-square test is more convenient because:
- It does not require a computer to simulate thousands of randomizations.
- It provides a simple formula and distribution for computing p-values.
- It is widely implemented in statistical software.
In practice, the chi-square test is the standard approach when conditions are met, while the randomization test provides a useful check or alternative when conditions are questionable.
16.4 Chapter review
16.4.1 Summary
In this chapter, we extended the chi-square framework to two-way tables, testing whether two categorical variables are independent. The randomization approach shuffles the data under the null hypothesis to build a distribution of the chi-square statistic, while the mathematical approach uses the chi-square distribution with \((R-1) \times (C-1)\) degrees of freedom. Both approaches require that observations are independent and that expected counts are sufficiently large (at least 5 in each cell).
The chi-square test of independence tells us whether two variables are related, but does not tell us how they are related or which groups differ. To understand the nature of the relationship, we must examine the individual cells and their contributions to the chi-square statistic.
16.4.2 Key terms
- Independence
- Expected counts (two-way table)
- Chi-square statistic
- Chi-square distribution
- Degrees of freedom (two-way table)
16.5 Exercises
Answers to odd-numbered exercises are provided in the Exercise Solutions appendix at the back of the book.
- Quitters. Does being part of a support group affect the ability of people to quit smoking? A county health department enrolled 300 smokers in a randomized experiment. 150 participants were randomly assigned to a group that used a nicotine patch and met weekly with a support group; the other 150 received the patch and did not meet with a support group. At the end of the study, 40 of the participants in the patch plus support group had quit smoking while only 30 smokers had quit in the other group.
Create a two-way table presenting the results of this study.
Answer each of the following questions under the null hypothesis that being part of a support group does not affect the ability of people to quit smoking, and indicate whether the expected values are higher or lower than the observed values.
How many subjects in the “patch + support” group would you expect to quit?
How many subjects in the “patch only” group would you expect to not quit?
- Act on climate change. The table below summarizes results from a Pew Research poll which asked respondents whether they have personally taken action to help address climate change within the last year and their generation. The differences in each generational group may be due to chance. Complete the following computations under the null hypothesis of independence between an individual’s generation and whether they have personally taken action to help address climate change within the last year. (Pew Research Center 2021)
| Generation | Took action | Didn't take action | Total |
|---|---|---|---|
| Gen Z | 292 | 620 | 912 |
| Millenial | 885 | 2,275 | 3,160 |
| Gen X | 809 | 2,709 | 3,518 |
| Boomer & older | 1,276 | 4,798 | 6,074 |
| Total | 3,262 | 10,402 | 13,664 |
If there is no relationship between age and action,
how many Gen Z’ers would you expect to have personally taken action to help address climate change within the last year?
how many Millenials would you expect to have personally taken action to help address climate change within the last year?
how many Gen X’ers would you expect to have personally taken action to help address climate change within the last year?
how many Boomers and older would you expect to have personally taken action to help address climate change within the last year?
- Lizard habitats, data. In order to assess whether habitat conditions are related to the sunlight choices a lizard makes for resting, Western fence lizard (Sceloporus occidentalis) were observed across three different microhabitats. (Adolph 1990; Asbury and Adolph 2007)
| site | sun | partial | shade | Total |
|---|---|---|---|---|
| desert | 16 | 32 | 71 | 119 |
| mountain | 56 | 36 | 15 | 107 |
| valley | 42 | 40 | 24 | 106 |
| Total | 114 | 108 | 110 | 332 |
If the variables describing the habitat and the amount of sunlight are independent, what proporiton of lizards (total) would be expected in each of the three sunlight categories?
Given the proportions of each sunlight condition, how many lizards of each type would you expect to see in the sun? in the partial sun? in the shade?
Compare the observed (original data) and expected (part b.) tables. From a first glance, does it seem as though the habitat and choice of sunlight may be associated?
Regardless of your answer to part (c), is it possible to tell from looking only at the expected and observed counts whether the two variables are associated?
- Disaggregating Asian American tobacco use, data. Understanding cultural differences in tobacco use across different demographic groups can lead to improved health care education and treatment. A recent study disaggregated tobacco use across Asian American ethnic groups including Asian-Indian (n = 4,373), Chinese (n = 4,736), and Filipino (n = 4,912), in comparison to non-Hispanic Whites (n = 275,025). The number of current smokers in each group was reported as Asian-Indian (n = 223), Chinese (n = 279), Filipino (n = 609), and non-Hispanic Whites (n = 50,880). (Rao et al. 2021)
In order to assess whether there is a difference in current smoking rates across three Asian American ethnic groups, the observed data is compared to the data that would be expected if there were no association between the variables.
| ethnicity | don't smoke | smoke | Total |
|---|---|---|---|
| Asian-Indian | 4,150 | 223 | 4,373 |
| Chinese | 4,457 | 279 | 4,736 |
| Filipino | 4,303 | 609 | 4,912 |
| Total | 12,910 | 1,111 | 14,021 |
If the variables on ethnicity and smoking status are independent, estimate the proporiton of individuals (total) who smoke?
Given the overall proportion who smoke, how many of each Asian American ethnicity would you expect to smoke?
Compare the observed and expected counts. From a first glance, does it seem as though the Asian American ethnicity and choice of smoking may be associated?
Regardless of your answer to part (c), is it possible to tell from looking only at the expected and observed counts whether the two variables are associated?
- Lizard habitats, randomize once. In order to assess whether habitat conditions are related to the sunlight choices a lizard makes for resting, Western fence lizard (Sceloporus occidentalis) were observed across three different microhabitats. (Adolph 1990; Asbury and Adolph 2007) Then, the data were randomized once, where sunlight preference was randomly assigned to the lizards across different sites. The original data are shown on the left and the results of the randomization is shown on the right.
| site | sun | partial | shade | Total |
|---|---|---|---|---|
| desert | 16 | 32 | 71 | 119 |
| mountain | 56 | 36 | 15 | 107 |
| valley | 42 | 40 | 24 | 106 |
| Total | 114 | 108 | 110 | 332 |
| site | sun | partial | shade | Total |
|---|---|---|---|---|
| desert | 44 | 42 | 33 | 119 |
| mountain | 39 | 31 | 37 | 107 |
| valley | 31 | 35 | 40 | 106 |
| Total | 114 | 108 | 110 | 332 |
Recall that the Chi-squared statistic \((X^2)\) measures the difference between the expected and observed counts. Without calculating the actual statistic, report on whether the original data or the randomized data will have a larger Chi-squared statistic. Explain your choice.
- Disaggregating Asian American tobacco use, randomize once. In a study that aims to disaggregate tobacco use across Asian American ethnic groups (Asian-Indian, Chinese, and Filipino, in comparison to non-Hispanic Whites), respondents were asked whether they smoke tobacco or not. (Rao et al. 2021) Then, the data were randomized once, where smoking status was randomly assigned to the participants across different ethnicities. The original data are shown on the left and the results of the randomization is shown on the right.
| ethnicity | don't smoke | smoke | Total |
|---|---|---|---|
| Asian-Indian | 4,150 | 223 | 4,373 |
| Chinese | 4,457 | 279 | 4,736 |
| Filipino | 4,303 | 609 | 4,912 |
| Total | 12,910 | 1,111 | 14,021 |
| ethnicity | don't smoke | smoke | Total |
|---|---|---|---|
| Asian-Indian | 4,015 | 358 | 4,373 |
| Chinese | 4,385 | 351 | 4,736 |
| Filipino | 4,510 | 402 | 4,912 |
| Total | 12,910 | 1,111 | 14,021 |
Recall that the Chi-squared statistic \((X^2)\) measures the difference between the expected and observed counts. Without calculating the actual statistic, report on whether the original data or the randomized data will have a larger Chi-squared statistic. Explain your choice.
- Lizard habitats, randomization test. In order to assess whether habitat conditions are related to the sunlight choices a lizard makes for resting, Western fence lizard (Sceloporus occidentalis) were observed across three different microhabitats. (Adolph 1990; Asbury and Adolph 2007) The original data were randomized 1,000 times (sunlight variable randomly assigned to the observations across different habitats), and the histogram of the Chi-squared statistic on each randomization is displayed.
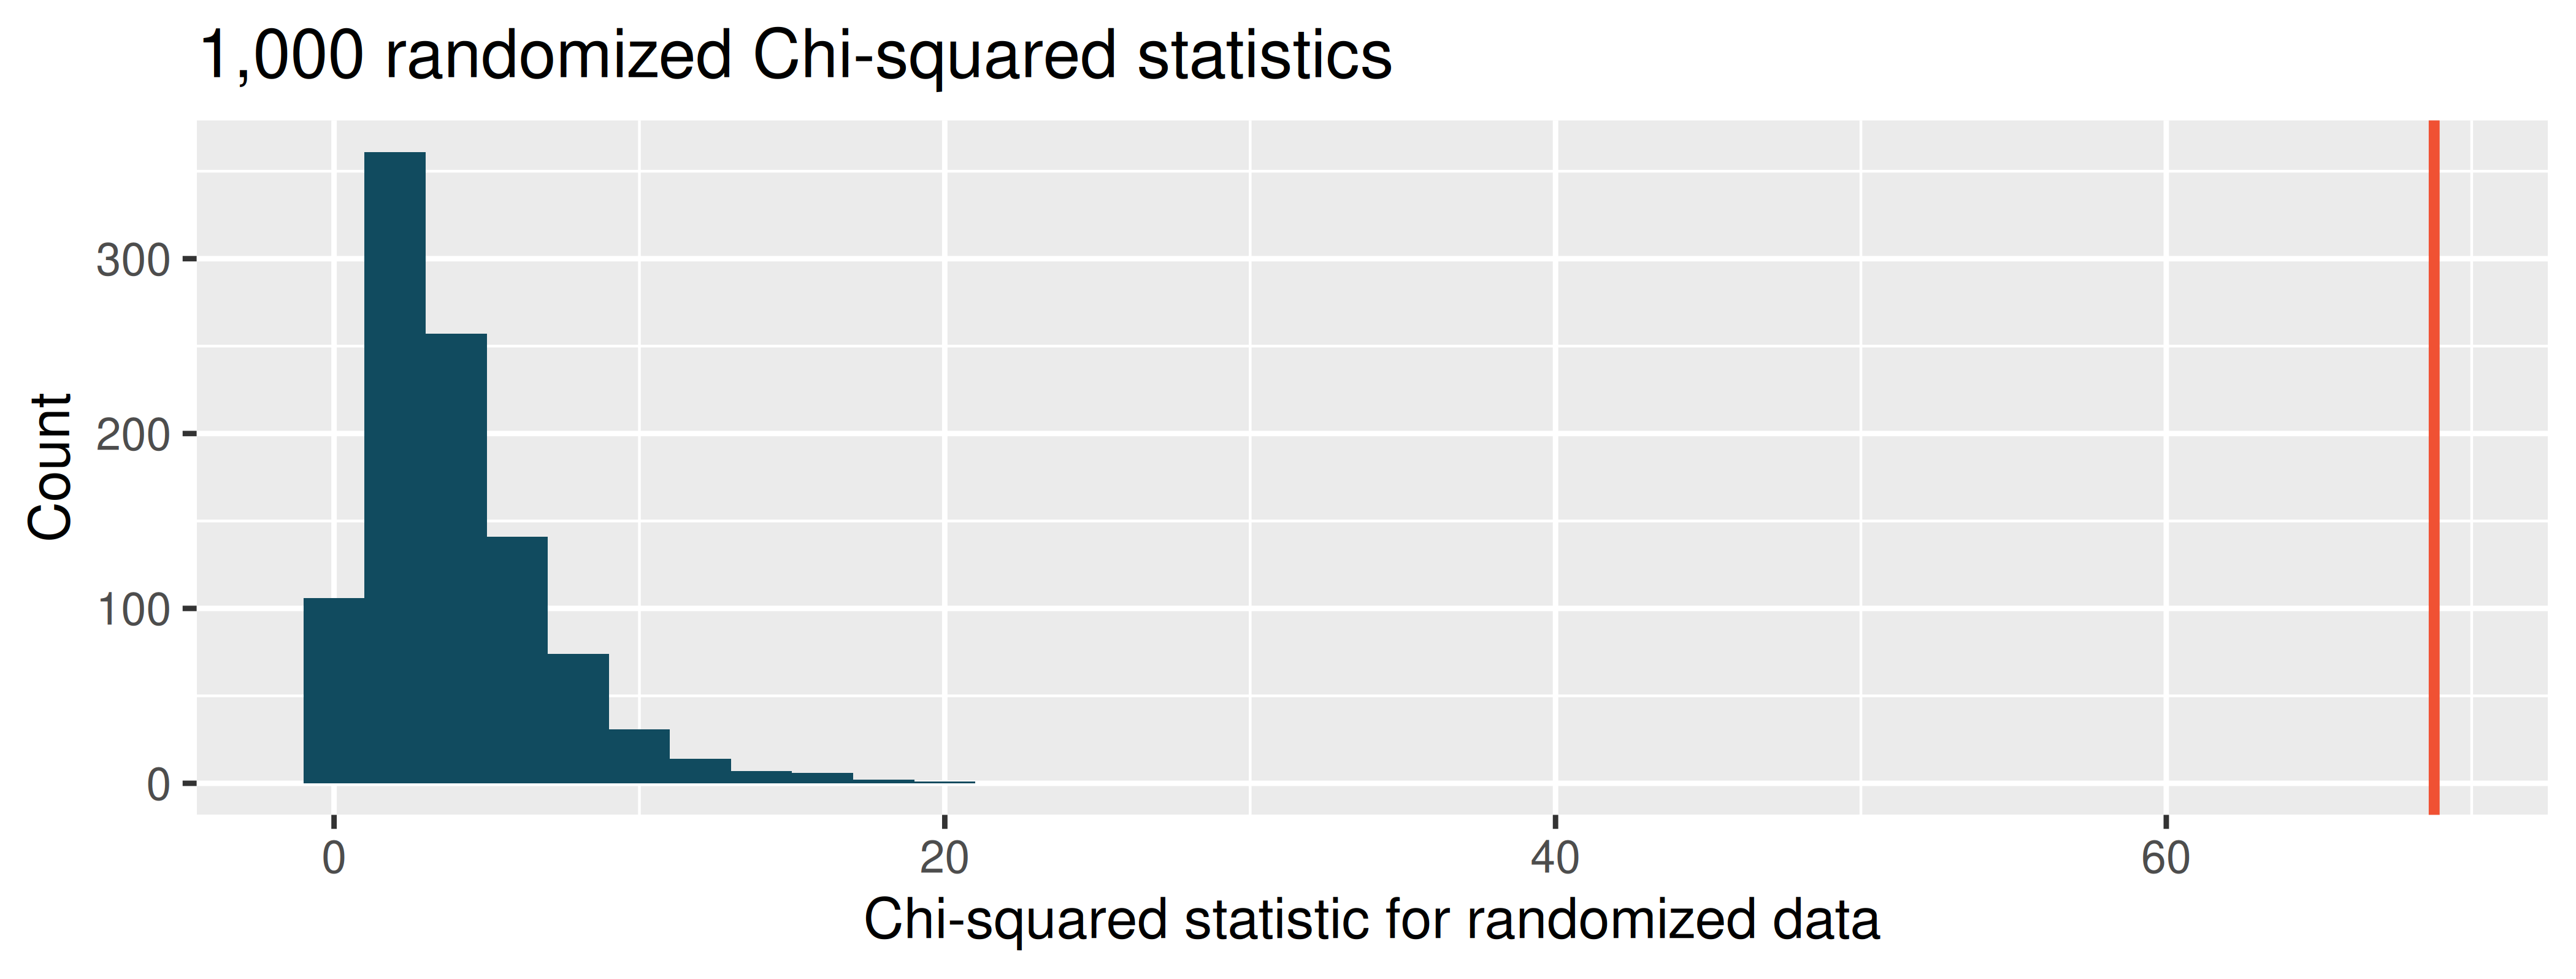
The histogram above describes the Chi-squared statistics for 1,000 different randomization datasets. When randomizing the data, is the imposed structure that the variables are independent or that the variables are associated? Explain.
What is the range of plausible values for the randomized Chi-squared statistic?
The observed Chi-squared statistic is 68.8 (marked in red on plot). Does the observed value provide evidence against the null hypothesis? To answer the question, state the null and alternative hypotheses, approximate the p-value, and conclude the test in the context of the problem.
- Disaggregating Asian American tobacco use, randomization test. Understanding cultural differences in tobacco use across different demographic groups can lead to improved health care education and treatment. A recent study disaggregated tobacco use across Asian American ethnic groups including Asian-Indian (n = 4373), Chinese (n = 4736), and Filipino (n = 4912), in comparison to non-Hispanic Whites (n = 275,025). The number of current smokers in each group was reported as Asian-Indian (n = 223), Chinese (n = 279), Filipino (n = 609), and non-Hispanic Whites (n = 50,880). (Rao et al. 2021) The original data were randomized 1000 times (smoking status randomly assigned to the observations across ethnicities), and the histogram of the Chi-squared statistic on each randomization is displayed.
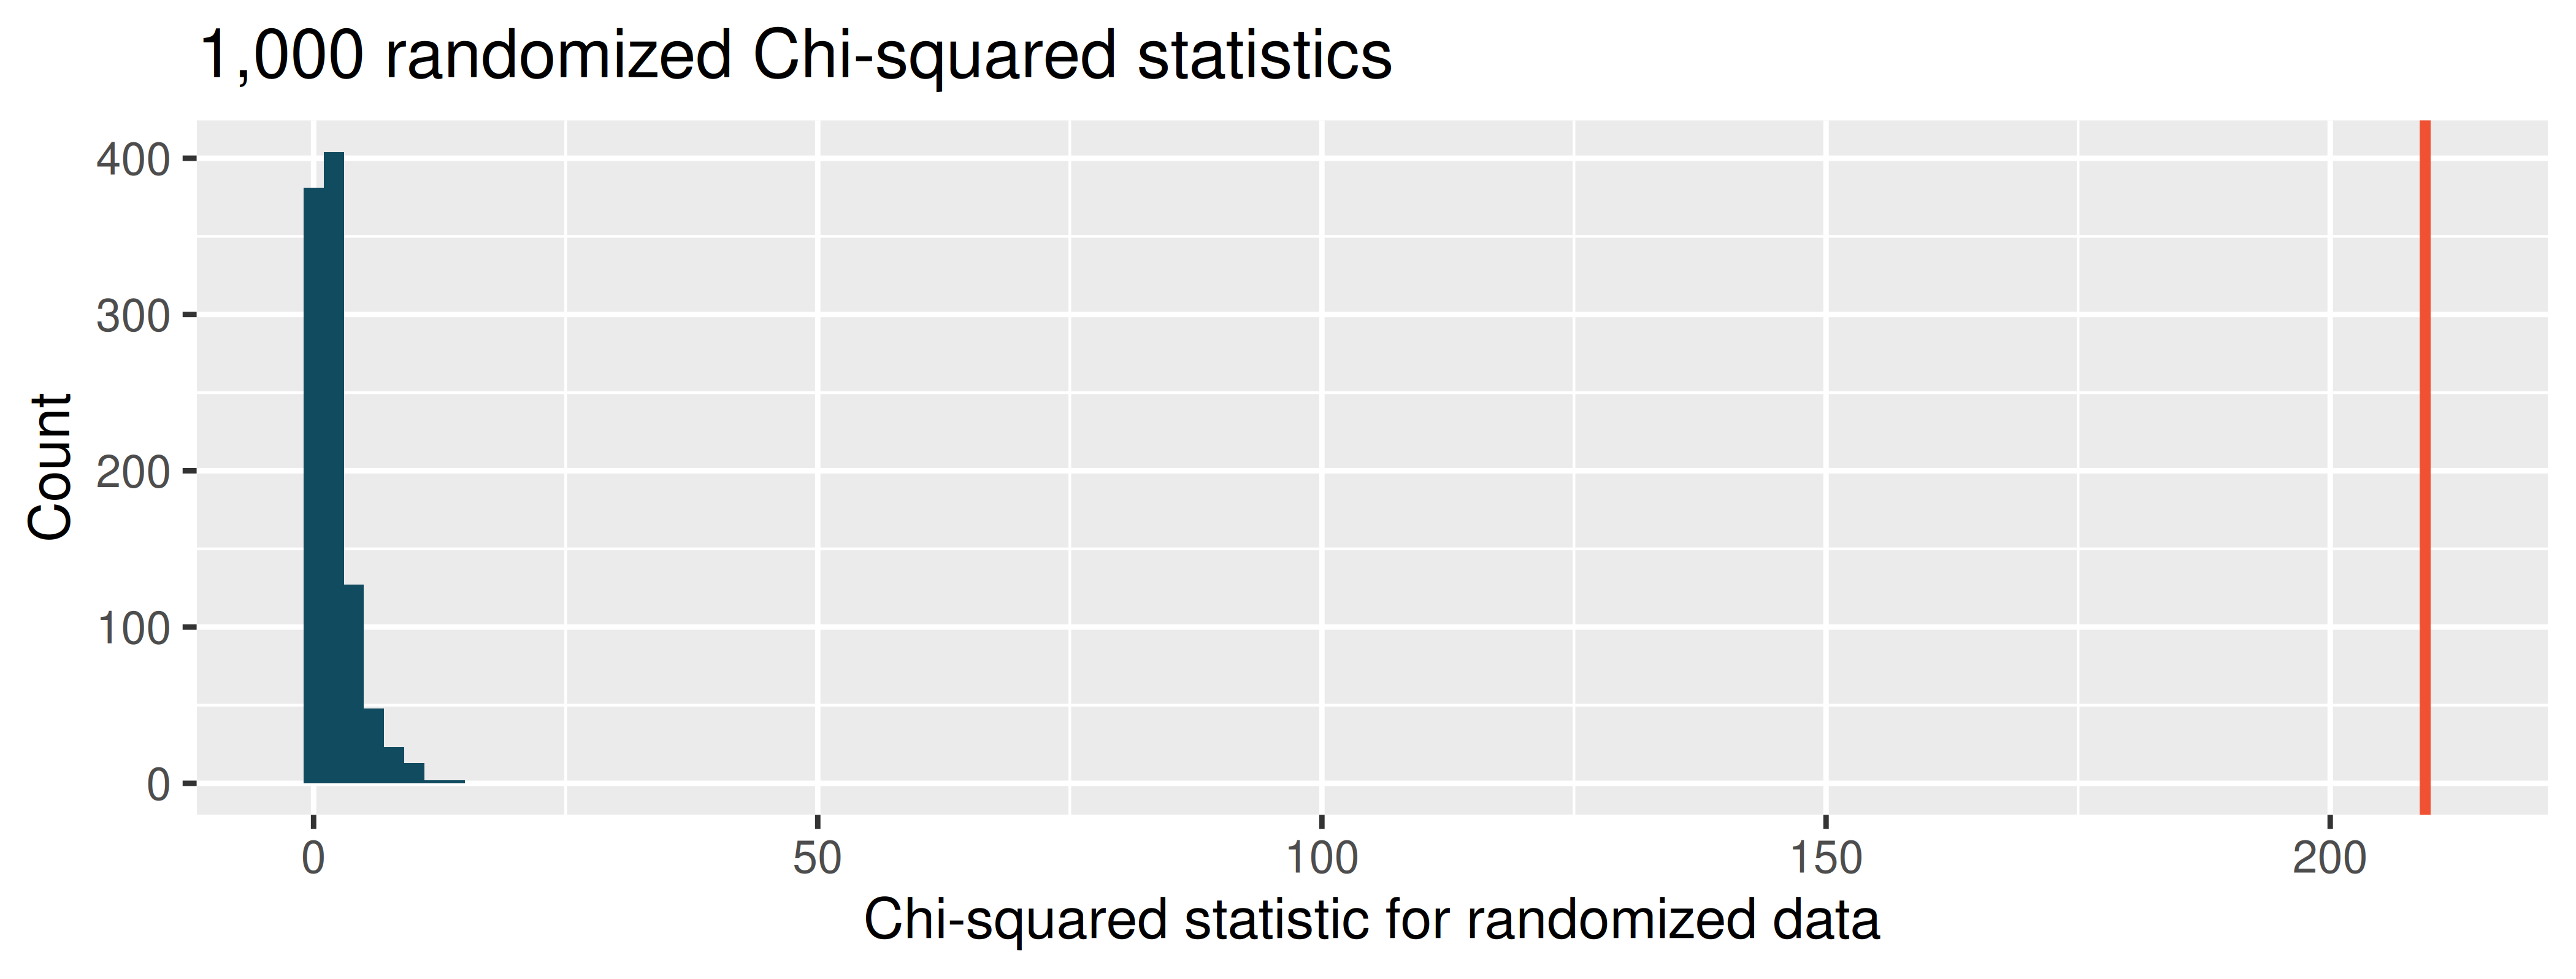
The histogram above describes the Chi-squared statistics for 1000 different randomization datasets. When randomizing the data, is the imposed structure that the variables are independent or that the variables are associated? Explain.
What is the range of plausible values for the randomized Chi-squared statistic?
The observed Chi-squared statistic is 209.42 (marked in red on plot). Does the observed value provide evidence against the null hypothesis? To answer the question, state the null and alternative hypotheses, approximate the p-value, and conclude the test in the context of the problem.
- Lizard habitats, larger data. In order to assess whether habitat conditions are related to the sunlight choices a lizard makes for resting, Western fence lizard (Sceloporus occidentalis) were observed across three different microhabitats. (Adolph 1990; Asbury and Adolph 2007)
Consider the situation where the dataset is 5 times larger than the original data (but have the same proportional representation in each category). The distribution of lizards in each of the sites resting in the sun, partial sun, and shade are as follows.
| site | sun | partial | shade | Total |
|---|---|---|---|---|
| desert | 80 | 160 | 355 | 595 |
| mountain | 280 | 180 | 75 | 535 |
| valley | 210 | 200 | 120 | 530 |
| Total | 570 | 540 | 550 | 1,660 |
The larger dataset was randomized 1,000 times (sunlight preference randomly assigned to the observations across sites), and the histogram of the Chi-squared statistic on each randomization is displayed.
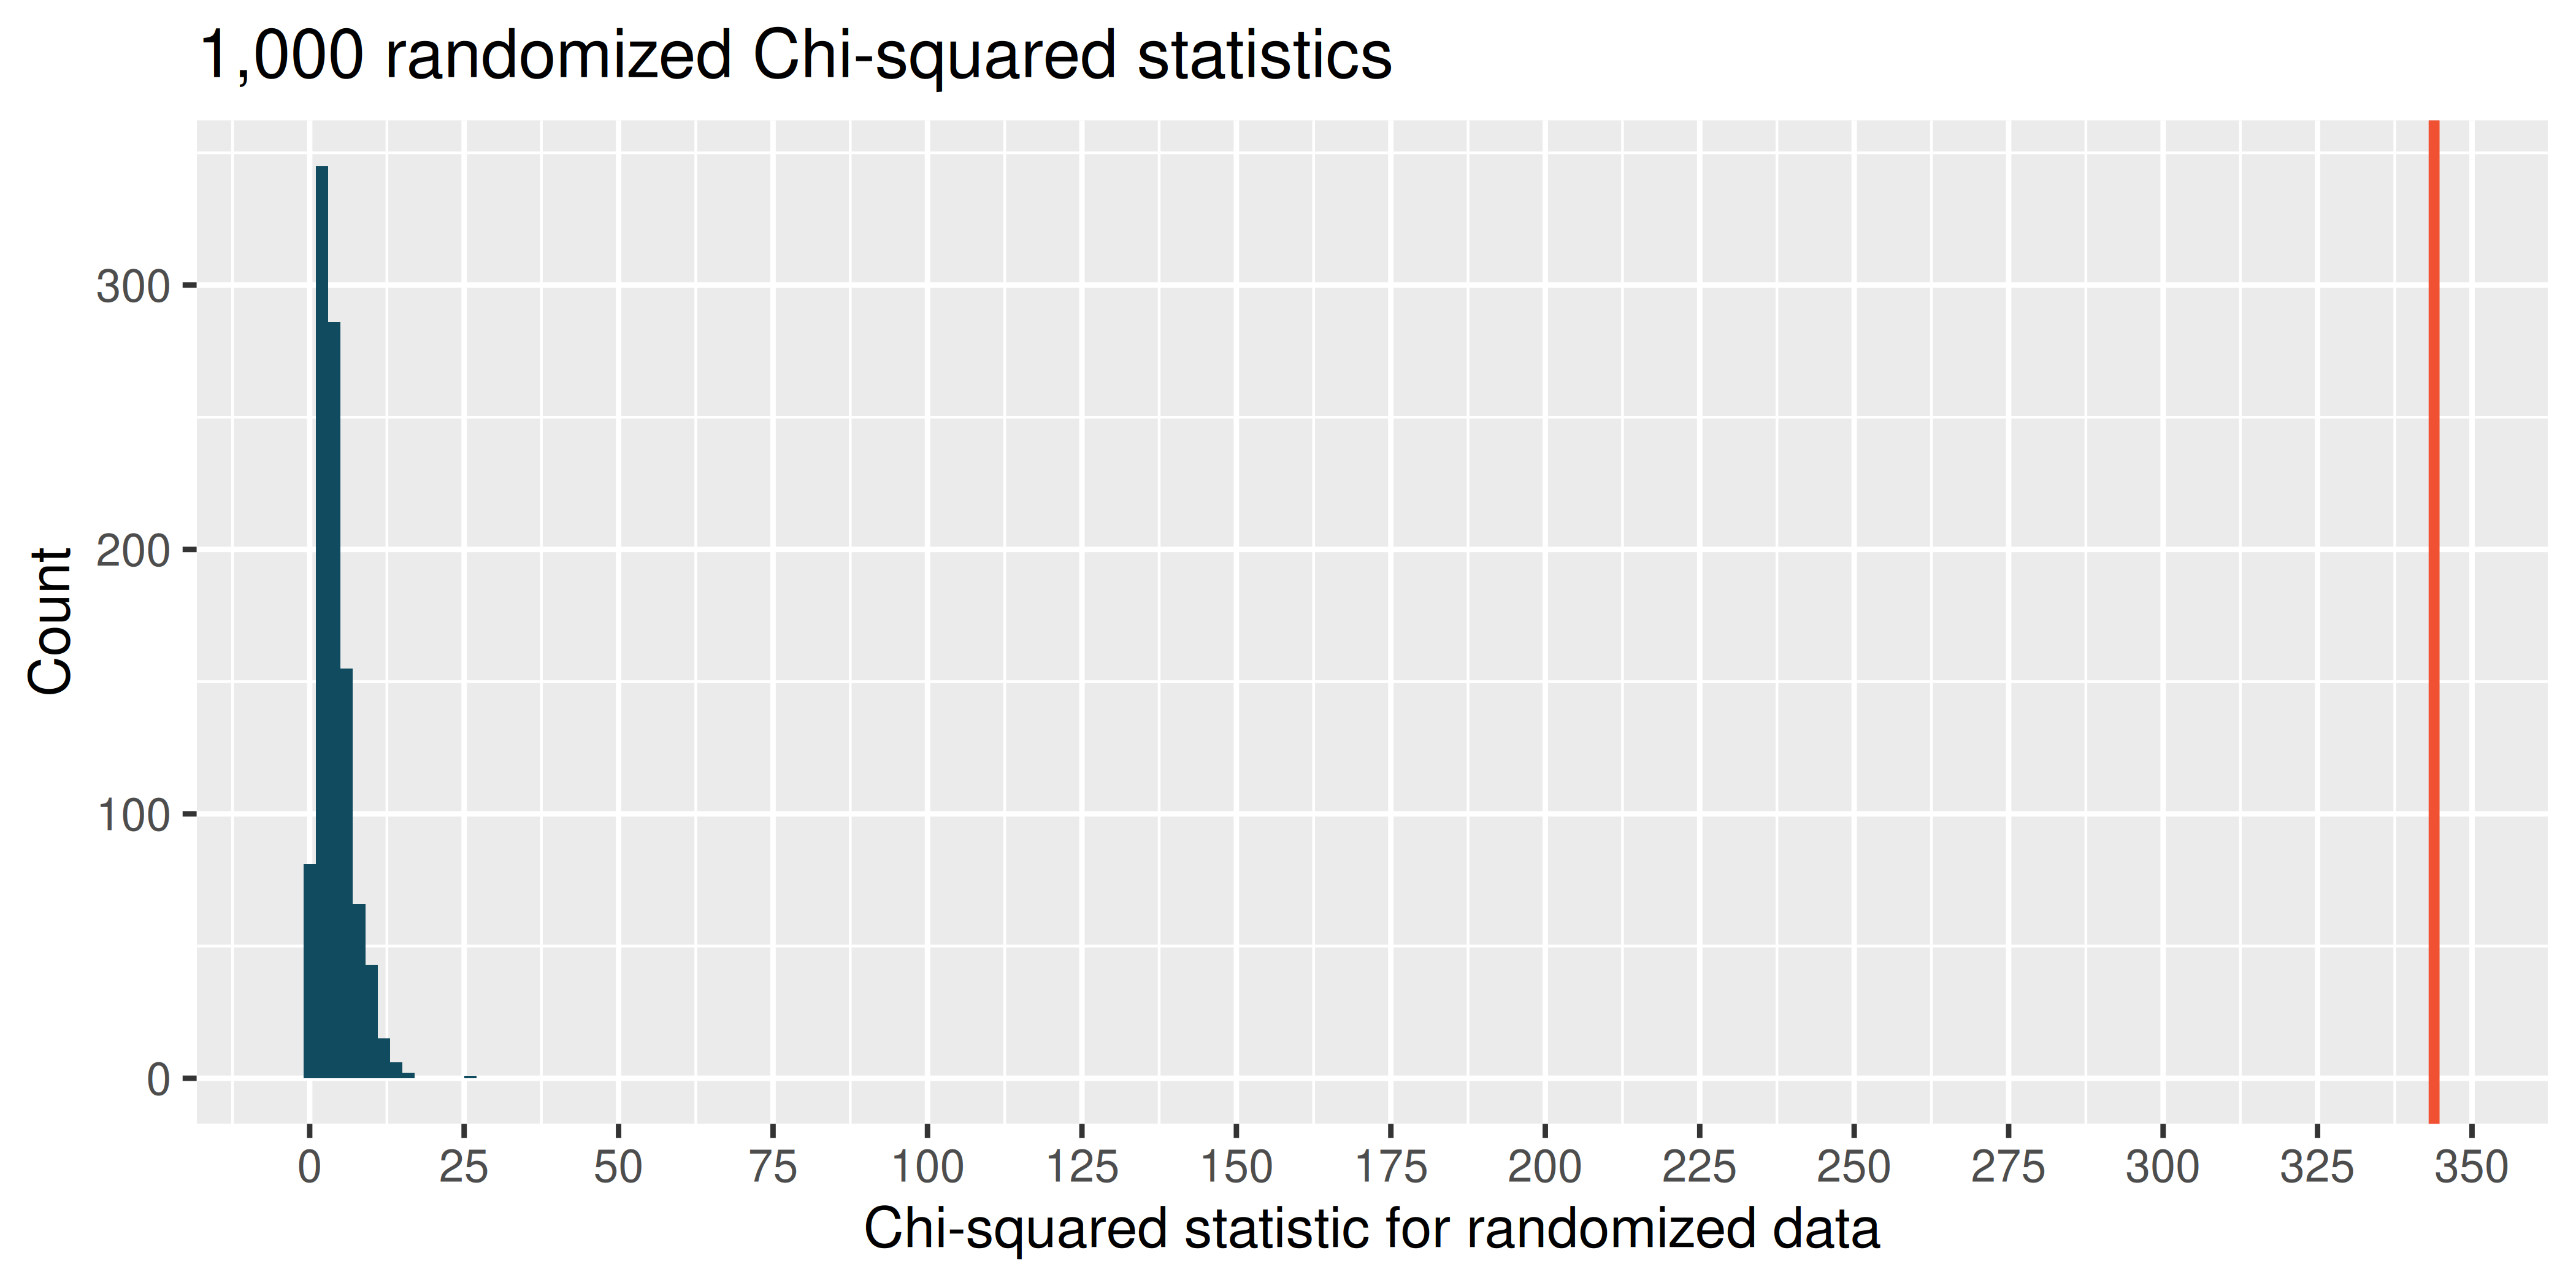
The histogram above describes the Chi-squared statistics for 1,000 different randomization of the larger dataset. When randomizing the data, is the imposed structure that the variables are independent or that the variables are associated? Explain.
What is the (approximate) range of plausible values for the randomized Chi-squared statistic?
The observed Chi-squared statistic is 343.8650556 (and seen in red on the graph). Does the observed value provide evidence against the null hypothesis? To answer the question, state the null and alternative hypotheses, approximate the p-value, and conclude the test in the context of the problem.
If the alternative hypothesis is true, how does the sample size effect the ability to reject the null hypothesis? (Hint: Consider the original data as compared with the larger dataset that have the same proportional values.)
- Disaggregating Asian American tobacco use, smaller data. Understanding cultural differences in tobacco use across different demographic groups can lead to improved health care education and treatment. A recent study disaggregated tobacco use across Asian American ethnic groups. (Rao et al. 2021)
Consider the situation where the dataset is 50 times smaller than the original data (but have the same proportional representation in each category). The distribution of smokers in each of the ethnicity groups in the smaller data are as follows.
| ethnicity | don't smoke | smoke | Total |
|---|---|---|---|
| Asian-Indian | 83 | 4 | 87 |
| Chinese | 89 | 6 | 95 |
| Filipino | 86 | 12 | 98 |
| Total | 258 | 22 | 280 |
The smaller dataset was randomized 1,000 times (smoking status randomly assigned to the observations across ethnicities), and the histogram of the Chi-squared statistic on each randomization is displayed.
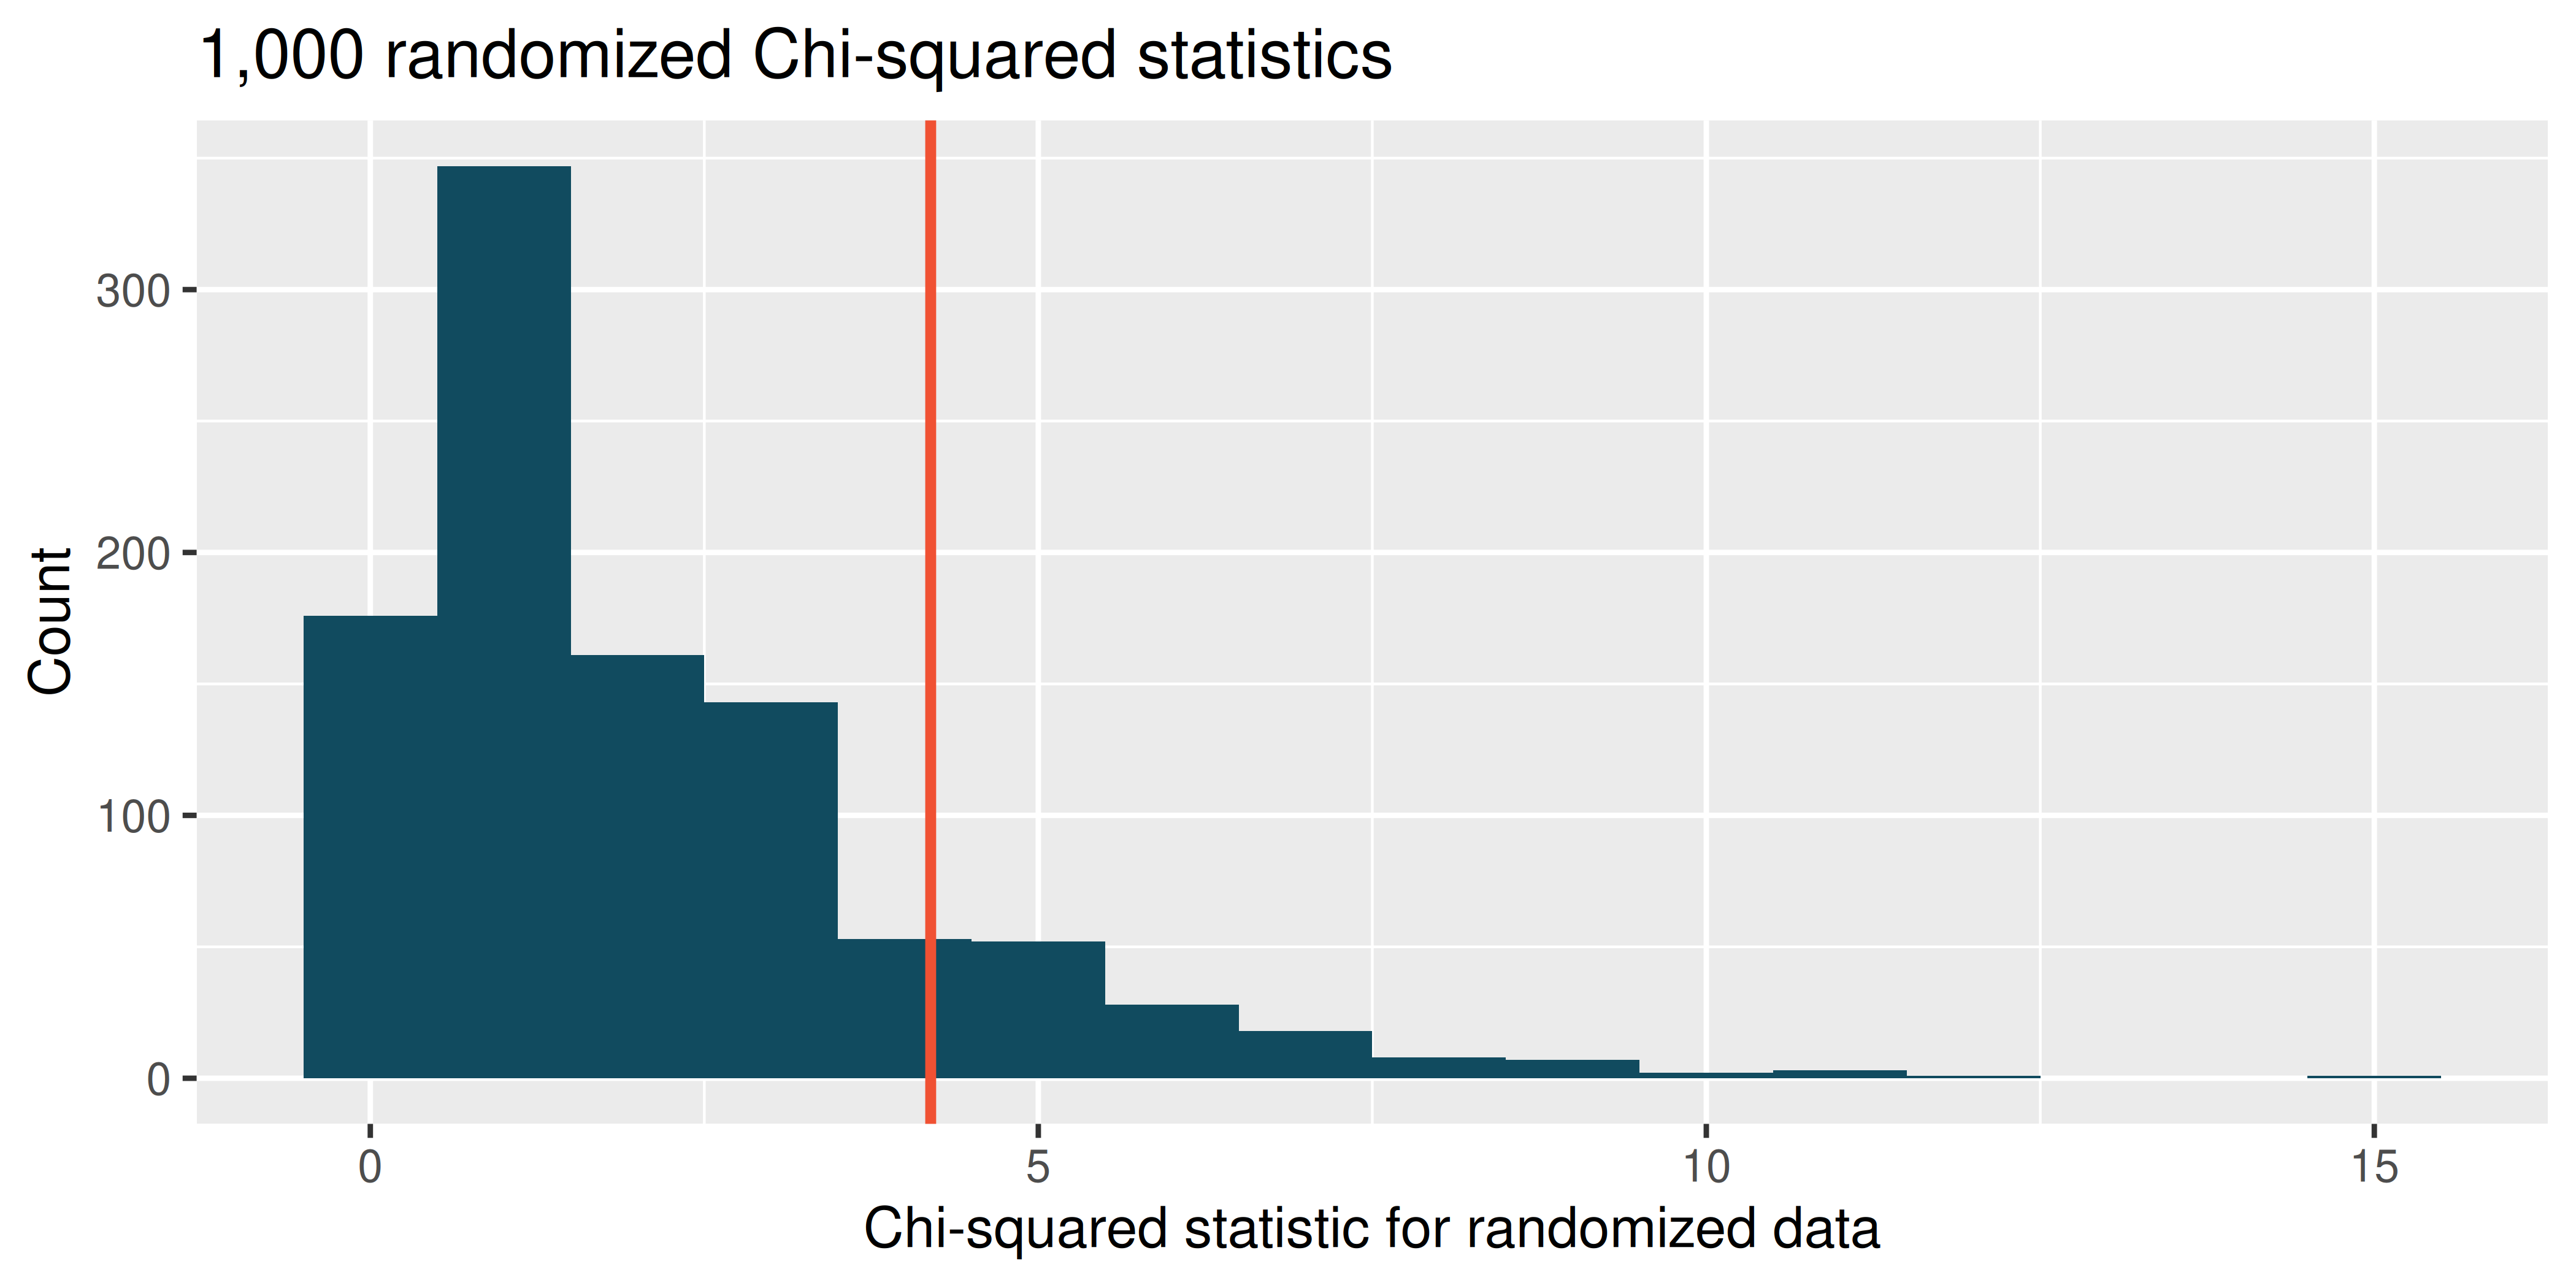
The histogram above describes the Chi-squared statistics for 1,000 different randomization of the smaller dataset. When randomizing the data, is the imposed structure that the variables are independent or that the variables are associated? Explain.
What is the (approximate) range of plausible values for the randomized Chi-squared statistic?
The observed Chi-squared statistic is 4.19 (and seen in red on the graph). Does the observed value provide evidence against the null hypothesis? To answer the question, state the null and alternative hypotheses, approximate the p-value, and conclude the test in the context of the problem.
If the alternative hypothesis is true, how does the sample size effect the ability to reject the null hypothesis? (Hint: Consider the original data as compared with the smaller dataset that have the same proportional values.)
- True / False, I. Determine if the statements below are true or false. For each false statement, suggest an alternative wording to make it a true statement.
The Chi-square distribution, just like the normal distribution, has two parameters, mean and standard deviation.
The Chi-square distribution is always right skewed, regardless of the value of the degrees of freedom parameter.
The Chi-square statistic is always greater than or equal to 0.
As the degrees of freedom increases, the shape of the Chi-square distribution becomes more skewed.
- True / False, II. Determine if the statements below are true or false. For each false statement, suggest an alternative wording to make it a true statement.
As the degrees of freedom increases, the mean of the Chi-square distribution increases.
If you found \(\chi^2 = 10\) with \(df = 5\) you would fail to reject \(H_0\) at the 5% discernibility level.
When finding the p-value of a Chi-square test, we always shade the tail areas in both tails.
As the degrees of freedom increases, the variability of the Chi-square distribution decreases.
- Sleep deprived transportation workers. The National Sleep Foundation conducted a survey on the sleep habits of randomly sampled transportation workers and randomly sampled non-transportation workers that serve as a “control” for comparison. (National Sleep Foundation 2012) The results of the survey are shown below. Conduct a hypothesis test to evaluate if these data provide evidence of an association between sleep levels and profession.
| Profession | Less than 6 hours | 6 to 8 hours | More than 8 hours | Total |
|---|---|---|---|---|
| Non-transportation workers | 35 | 193 | 64 | 292 |
| Transportation workers | 104 | 499 | 192 | 795 |
| Total | 139 | 692 | 256 | 1,087 |
- Parasitic worm. Lymphatic filariasis is a disease caused by a parasitic worm. Complications of the disease can lead to extreme swelling and other complications. Here we consider results from a randomized experiment that compared three different drug treatment options to clear people of the this parasite, which people are working to eliminate entirely. The results for the second year of the study are given below: (King et al. 2018)
| group | Clear at Year 2 | Not Clear at Year 2 | Total |
|---|---|---|---|
| Three drugs | 52 | 2 | 54 |
| Two drugs | 31 | 24 | 55 |
| Two drugs annually | 42 | 14 | 56 |
| Total | 125 | 40 | 165 |
Set up hypotheses for evaluating whether there is any difference in the performance of the treatments, and also check conditions.
Statistical software was used to run a Chi-square test, which output: \(X^2 = 23.7 \quad df = 2 \quad \text{p-value} < 0.0001\). Use these results to evaluate the hypotheses from part (a), and provide a conclusion in the context of the problem.
- Shipping holiday gifts. A local news survey asked 500 randomly sampled Los Angeles residents which shipping carrier they prefer to use for shipping holiday gifts. The table below shows the distribution of responses by age group as well as the expected counts for each cell (shown in italics).
| USPS | 72 | 81 | 97 | 102 | 76 | 62 | 245 |
| UPS | 52 | 53 | 76 | 68 | 34 | 41 | 162 |
| FedEx | 31 | 21 | 24 | 27 | 9 | 16 | 64 |
| Something else | 7 | 5 | 6 | 7 | 3 | 4 | 16 |
| Not sure | 3 | 5 | 6 | 5 | 4 | 3 | 13 |
| Total | 165 | 209 | 126 | 500 |
State the null and alternative hypotheses for testing for independence of age and preferred shipping method for holiday gifts among Los Angeles residents.
Are the conditions for inference using a Chi-square test satisfied?
- Coffee and depression. Researchers conducted a study investigating the relationship between caffeinated coffee consumption and risk of depression in women. They collected data on 50,739 women free of depression symptoms at the start of the study in the year 1996, and these women were followed through 2006. The researchers used questionnaires to collect data on caffeinated coffee consumption, asked each individual about physician- diagnosed depression, and also asked about the use of antidepressants. The table below shows the distribution of incidences of depression by amount of caffeinated coffee consumption. (Lucas et al. 2011)
| Clinical depression | 1 cup / week or fewer | 2-6 cups / week | 1 cups / day | 2-3 cups / day | 4 cups / day or more | Total |
|---|---|---|---|---|---|---|
| Yes | 670 | ___ | 905 | 564 | 95 | 2,607 |
| No | 11,545 | 6,244 | 16,329 | 11,726 | 2,288 | 48,132 |
| Total | 12,215 | 6,617 | 17,234 | 12,290 | 2,383 | 50,739 |
What type of test is appropriate for evaluating if there is an association between coffee intake and depression?
Write the hypotheses for the test you identified in part (a).
Calculate the overall proportion of women who do and do not suffer from depression.
Identify the expected count for the empty cell, and calculate the contribution of this cell to the test statistic.
The test statistic is \(\chi^2=20.93\). What is the p-value?
What is the conclusion of the hypothesis test?
One of the authors of this study was quoted on the New York Times as saying it was “too early to recommend that women load up on extra coffee” based on just this study. (O’Connor 2011) Do you agree with this statement? Explain your reasoning.
Dataset sources
lizard_habitat (openintro)
StatLens Exercises
Let StatLens do the arithmetic; spend your effort on the reasoning a calculator can’t do.
Frame the question. A campus survey crosses major (STEM / humanities / social science / business) with caffeine source (coffee / tea / energy drink / none) for 600 students.
- Identify the two categorical variables and the dimensions of the contingency table.
- Write the null and alternative hypotheses for a test of independence, in words.
- The test of independence and the test of homogeneity use the same \(\chi^2\) statistic, the same expected-count formula, and the same df. What is the conceptual difference between them, and why does it matter how the data were collected?
Choose the procedure. For each scenario, name the procedure — \(\chi^2\) test of independence (or homogeneity), \(\chi^2\) goodness-of-fit, two-proportion \(z\), or not a \(\chi^2\) problem.
- Is political party (3 levels) related to opinion on a policy (favor / oppose / undecided)?
- Is the proportion of “favor” responses different between Democrats and Republicans?
- Does the distribution of blood types (A/B/AB/O) in a sample of 500 match the population frequencies?
- Is the mean reaction time the same across three age groups?
- Is there an association between meal-plan choice (4 levels) and dorm (5 levels)?
Check conditions before you trust the test. Open the Chi-Square test tool with any two-categorical-variable dataset (e.g., bundled examples on relationships).
- What is the expected-count condition for the \(\chi^2\) independence test? Why are expected counts (not observed) the criterion?
- How are the expected counts in cell \((i, j)\) computed? Walk through the formula in words.
- Suppose the smallest expected count is 4. Should you trust the \(\chi^2\) approximation? Name two responses that are more defensible than just running the test anyway.
Run it and interpret it. Open the Chi-Square test tool with a two-categorical dataset.
- Report the \(\chi^2\) statistic, df, and p-value.
- State your decision at \(\alpha = 0.05\) and write a one-sentence conclusion in context.
- The tool reports the observed and expected counts side-by-side. Suppose \(H_0\) is rejected — how do you decide where the association is strongest? What does a large positive \(O - E\) in one cell mean substantively?
- A student concludes from a rejected \(H_0\): “Major causes a student to choose a certain caffeine source.” Why is this the wrong conclusion — and what is the right one?
Simulation as a sanity check. Open the Randomization \(\chi^2\) test on the same data.
- Run 5000 simulated \(\chi^2\) statistics. Compare its simulation p-value to the \(\chi^2\)-distribution p-value from Exercise 4. How close are they?
- Repeat with a smaller dataset (or one cell deliberately small). Are the two p-values still close? Which would you trust?
- In a \(2 \times 2\) table, the \(\chi^2\) test of independence gives the same p-value as a two-proportion \(z\)-test (squared). Why is this not a coincidence?
- Suppose you have a \(3 \times 3\) table and \(H_0\) is rejected. Why is “the variables are associated” all you can conclude from the test alone? What additional analyses would help pinpoint which groups differ?
Adolph, S. C. 1990. “Influence of Behavioral Thermoregulation on Microhabitat Use by Two Sceloporus Lizards.” Ecology 71: 315–27.
Asbury, D. A., and S. C. Adolph. 2007. “Behavioral Plasticity in an Ecological Generalist: Microhabitat Use by Western Fence Lizards.” Evolutionary Ecology Research 9: 801–15.
King, C., J. Suamani, N. Sanuku, Y.-C. Cheng, S. Satofan, B. Mancuso, C. W. Goss, et al. 2018. “A Trial of a Triple-Drug Treatment for Lymphatic Filariasis.” New England Journal of Medicine 379: 1801–10. https://doi.org/10.1056/NEJMoa1706854.
Lucas, M., F. Mirzaei, A. Pan, O. I. Okereke, W. C. Willett, E. J. O’Reilly, K. Koenen, and A. Ascherio. 2011. “Coffee, Caffeine, and Risk of Depression Among Women.” Archives of Internal Medicine 171 (17): 1571. https://doi.org/10.1001/archinternmed.2011.393.
National Sleep Foundation. 2012. http://www.openintro.org/redirect.php?go=textbook-trans_workers_sleep_2012.
O’Connor, A. 2011. “Coffee Drinking Linked to Less Depression in Women.” New York Times. http://www.openintro.org/redirect.php?go=textbook-coffee_depression_2011.
Pew Research Center. 2021. “How Americans’ Attitudes about Climate Change Differ by Generation, Party and Other Factors, Data Collected April 20 to 29, 2021.” https://www.openintro.org/go?id=textbook-pew-2021-climate-change.
Rao, M., L. Bar, Y. Yu, M. Srinivasan, A. Mukherjea, J. Li, S. Chung, S. Venkatraman, S. Dan, and L. Palaniappan. 2021. “Disaggregating Asian American Cigarette and Alternative Tobacco Product Use: Results from the National Health Interview Survey (NHIS) 2006–2018.” Journal of Racial and Ethnic Health Disparities. https://doi.org/10.1007/s40615-021-01024-5.