2 Data Collection and Study Design
Before digging into the details of working with data, we pause to think about how data come to be. If data are to be used to draw broad conclusions, then it is important to understand who or what the data represent. One important aspect is sampling — knowing how the observational units were selected from a larger group allows us to generalize back to the population from which the data were drawn. Additionally, by understanding the structure of the study, we can separate causal relationships from mere associations. A good question to ask before analyzing any dataset is: How were these observations collected? You will learn a lot about the data by understanding its source.
StatLens: Sampling Bias Lab. Convinced you could pick a “representative” sample by eye? Try the Sampling Bias Lab. You hand-pick “representative” words from the Gettysburg Address (the population), then the tool draws random samples of the same size. Both sets of sample means are plotted against the true population mean (\(\mu \approx 4.3\) letters). The point of the demo: human-chosen samples are systematically biased, and the bias does not shrink as \(n\) grows. Other sampling methods exist, and plenty of real studies use them — but random sampling is the one that lets sample statistics estimate population parameters honestly.
2.1 Populations and samples
The first step in conducting research is to identify the question to be investigated. A clearly stated research question helps identify what subjects or cases should be studied and what variables are important. It is also important to consider how data are collected so that they are reliable and help achieve the research goals.
Consider the following three research questions:
- What is the average mercury content in swordfish in the Atlantic Ocean?
- Over the last five years, what is the average time to complete a degree for UW–La Crosse undergrads?
- Does a new drug reduce the number of deaths in patients with severe heart disease?
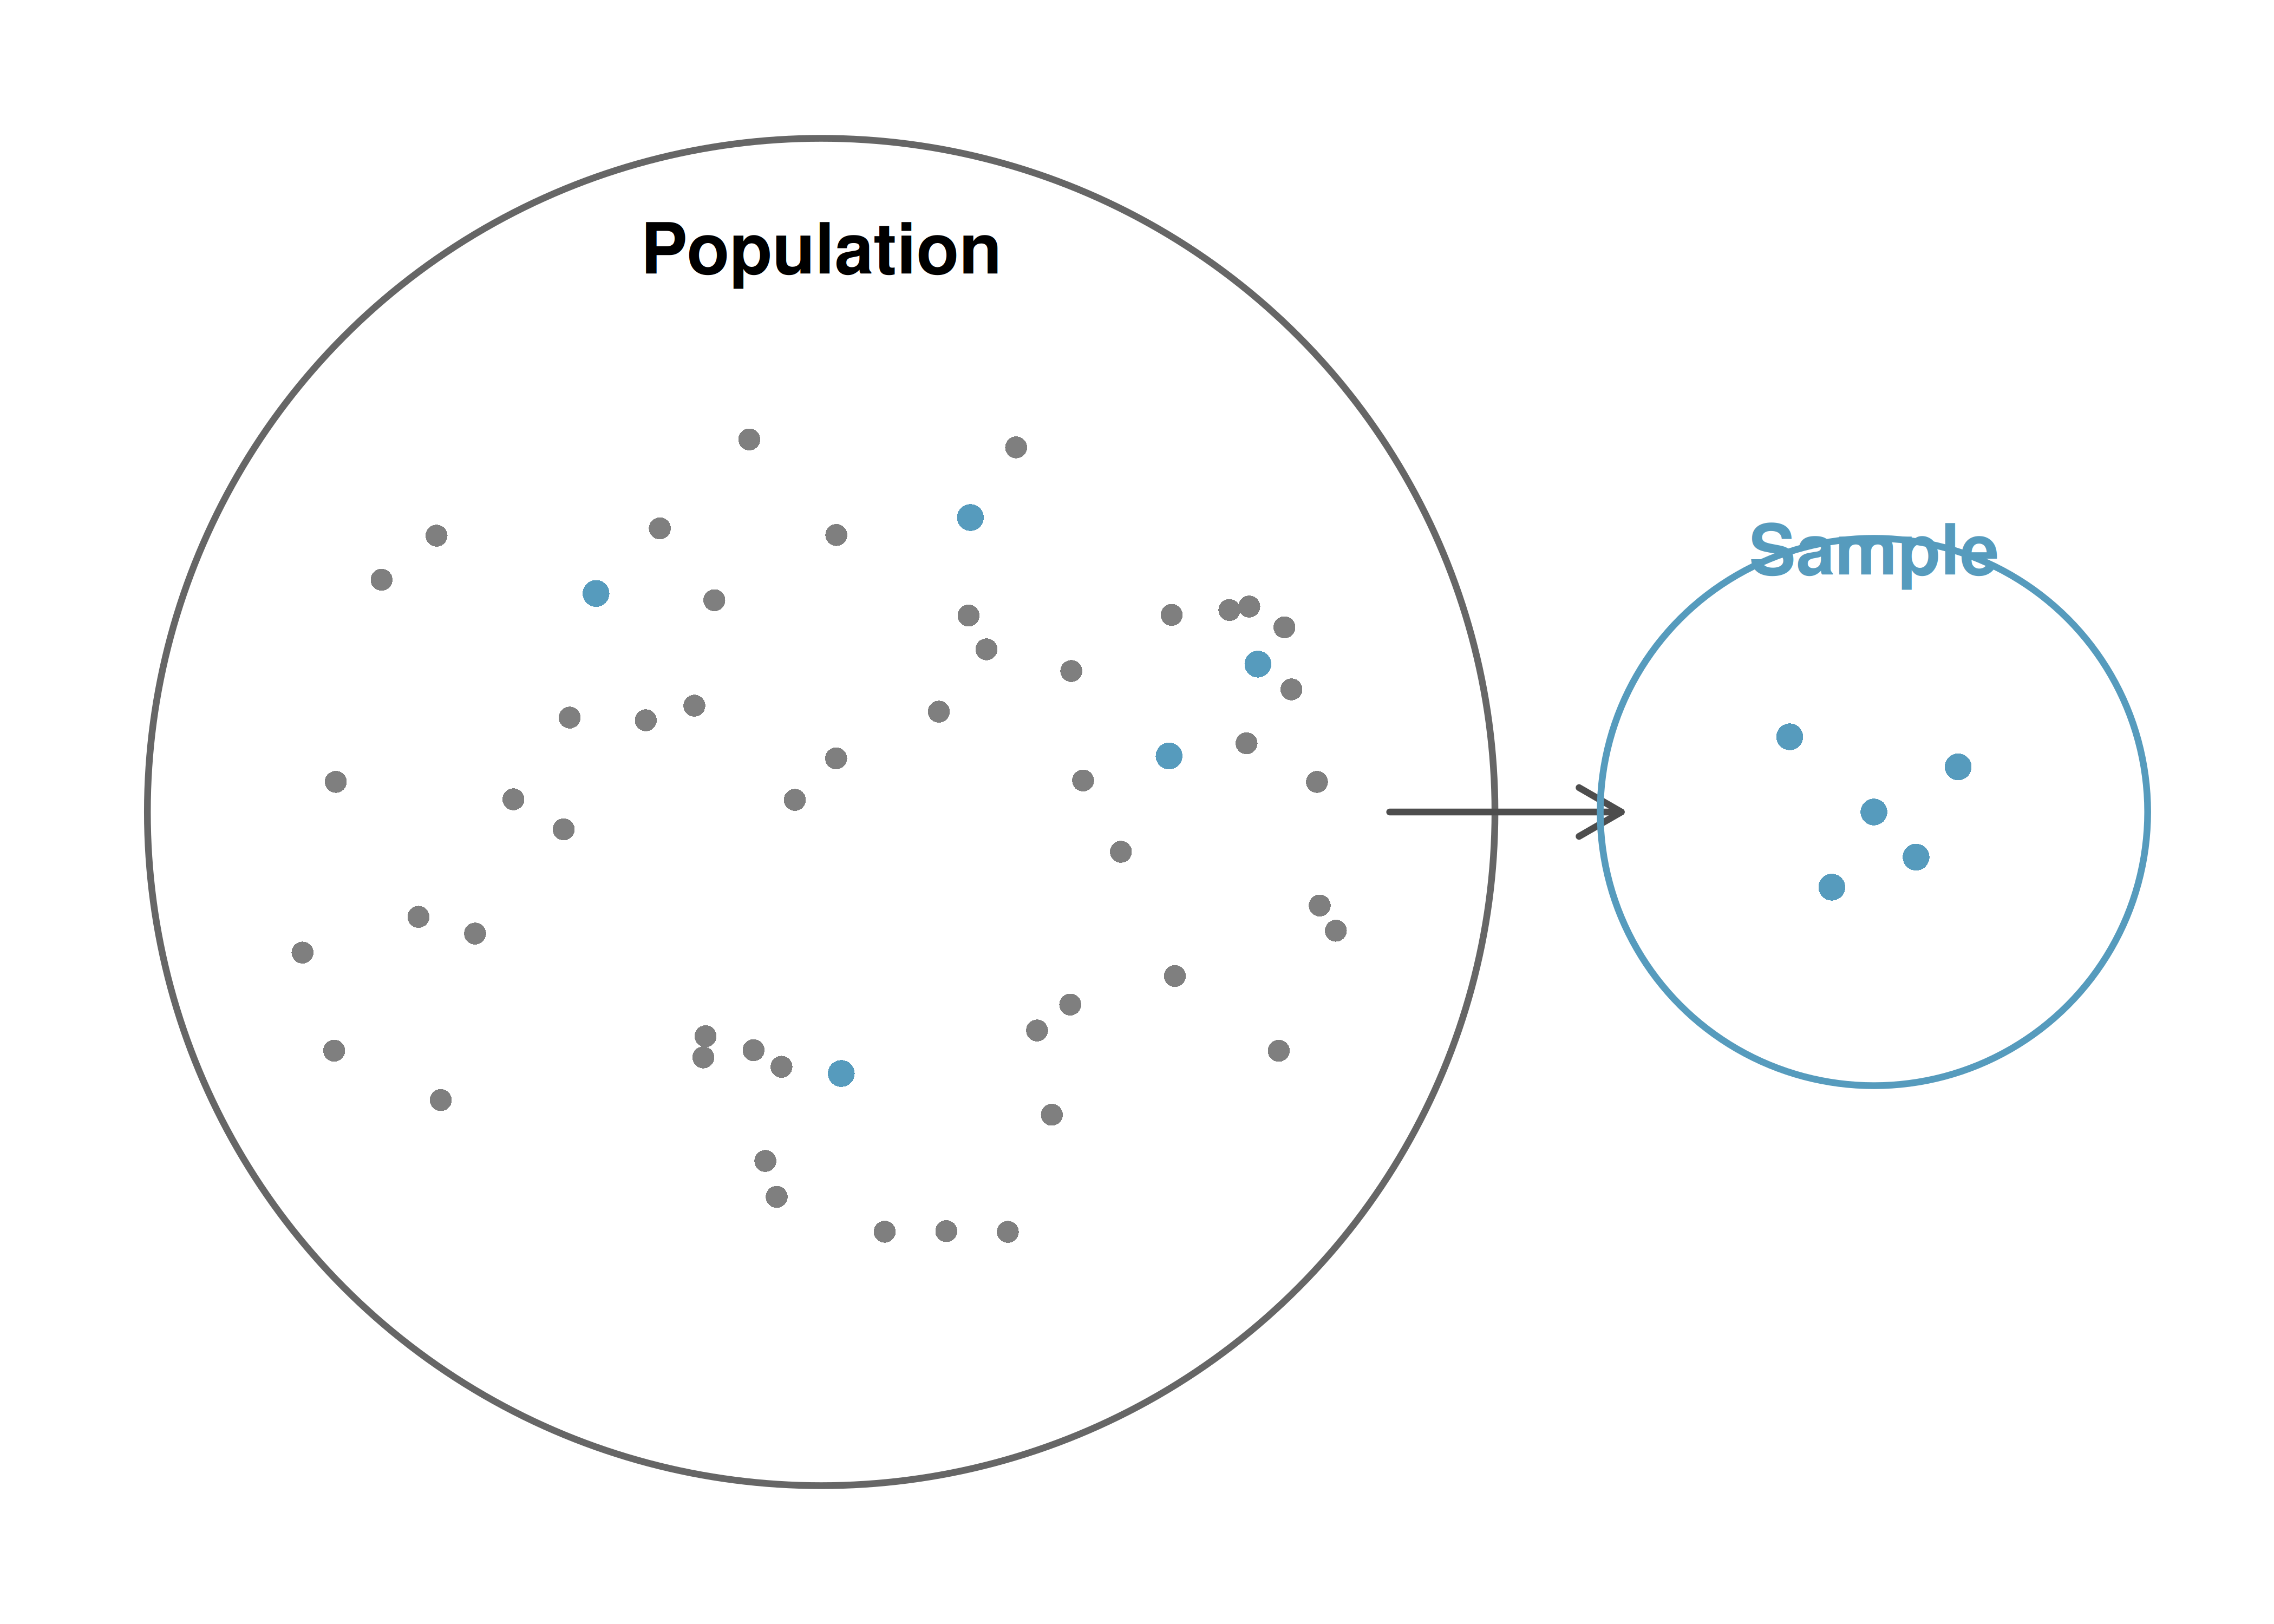
The population is the entire group of individuals or cases about which we want information. A sample is a subset of the population from which we actually collect data. A census is a study that attempts to collect data from every member of the population.
Each research question refers to a target population. In the first question, the target population is all swordfish in the Atlantic Ocean, and each fish represents a case. Oftentimes it is not feasible to collect data for every case in a population. A census is difficult because it may be too expensive, or it might be difficult or impossible to even identify every member of the population. Instead, we take a sample. Ideally, a sample is a manageable fraction of the population. For instance, 60 swordfish might be selected, and this sample data may be used to estimate the population average mercury content.
For the second and third research questions above, identify the target population and what represents an individual case.
Show answer
For the question about time to complete a degree, the population includes all UW–La Crosse undergraduates who graduated in the last five years (we can only compute an average for students who actually finished). Each graduate is an individual case. For the question about the heart disease drug, the population includes all people with severe heart disease, and each person represents a case.2.1.1 Parameters and statistics
In most statistical analyses, the research question boils down to determining a numerical summary — perhaps a quantity you already know (like the average) or one you will learn about in this course.
A numerical summary can be calculated on either the sample or the entire population. However, measuring every unit in the population is usually impossible. So we calculate the summary from a sample and use it to estimate the corresponding population value.
A population parameter is a numerical summary calculated from (or defined for) the entire population. A sample statistic is a numerical summary calculated from the sample data.
We use specific terms to distinguish between numbers calculated from a sample (sample statistics) and numbers that describe the entire population (population parameters). These terms will be used extensively in later chapters when we discuss making inferences about populations.
A poll of 1,000 likely voters finds that 54% plan to vote for Candidate A. Identify the population parameter and the sample statistic.
Show answer
The sample statistic is 54% — this is the proportion observed in the sample of 1,000 voters. The population parameter is the true proportion of all likely voters who plan to vote for Candidate A, which is unknown. The sample statistic (54%) is our best estimate of that unknown parameter.2.1.2 Anecdotal evidence
Consider the following possible responses to the three research questions from above:
- A man on the news got mercury poisoning from eating swordfish, so the average mercury concentration in swordfish must be dangerously high.
- I met two students who took more than 7 years to graduate from UW–La Crosse, so it must take longer to graduate here than at many other schools.
- My friend’s dad had a heart attack and died after they gave him a new heart disease drug, so the drug must not work.
Each conclusion is based on data. However, there are two problems. First, the data only represent one or two cases. Second, and more importantly, it is unclear whether these cases are actually representative of the population. Data collected in this haphazard fashion are called anecdotal evidence.
Be careful of anecdotal evidence. Such evidence may be true and verifiable, but it may only represent extraordinary cases and therefore not be a good representation of the population.
Anecdotal evidence typically consists of unusual cases that we recall based on their striking characteristics. For instance, we are more likely to remember the two people who took 7 years to graduate than the six others who graduated in four years. Instead of focusing on the most unusual cases, we should examine a sample of many cases that better represent the population.
2.2 Sampling from a population
We might try to estimate the time to graduation for UW–La Crosse undergraduates by collecting a sample of graduates. All graduates in the last five years represent the population, and graduates who are selected for review are collectively called the sample. In general, we always seek to randomly select a sample from a population. The most basic type of random selection is equivalent to how raffles are conducted. For example, we could write each graduate’s name on a raffle ticket and draw 10 tickets. The selected names would represent a random sample of 10 graduates.
Suppose we ask a student who happens to be majoring in nutrition to select several graduates for the study. Which students do you think they might pick? Do you think their sample would be representative of all graduates?
They might pick a disproportionate number of graduates from health-related fields. When selecting samples by hand, we run the risk of picking a biased sample, even if our bias is unintentional.
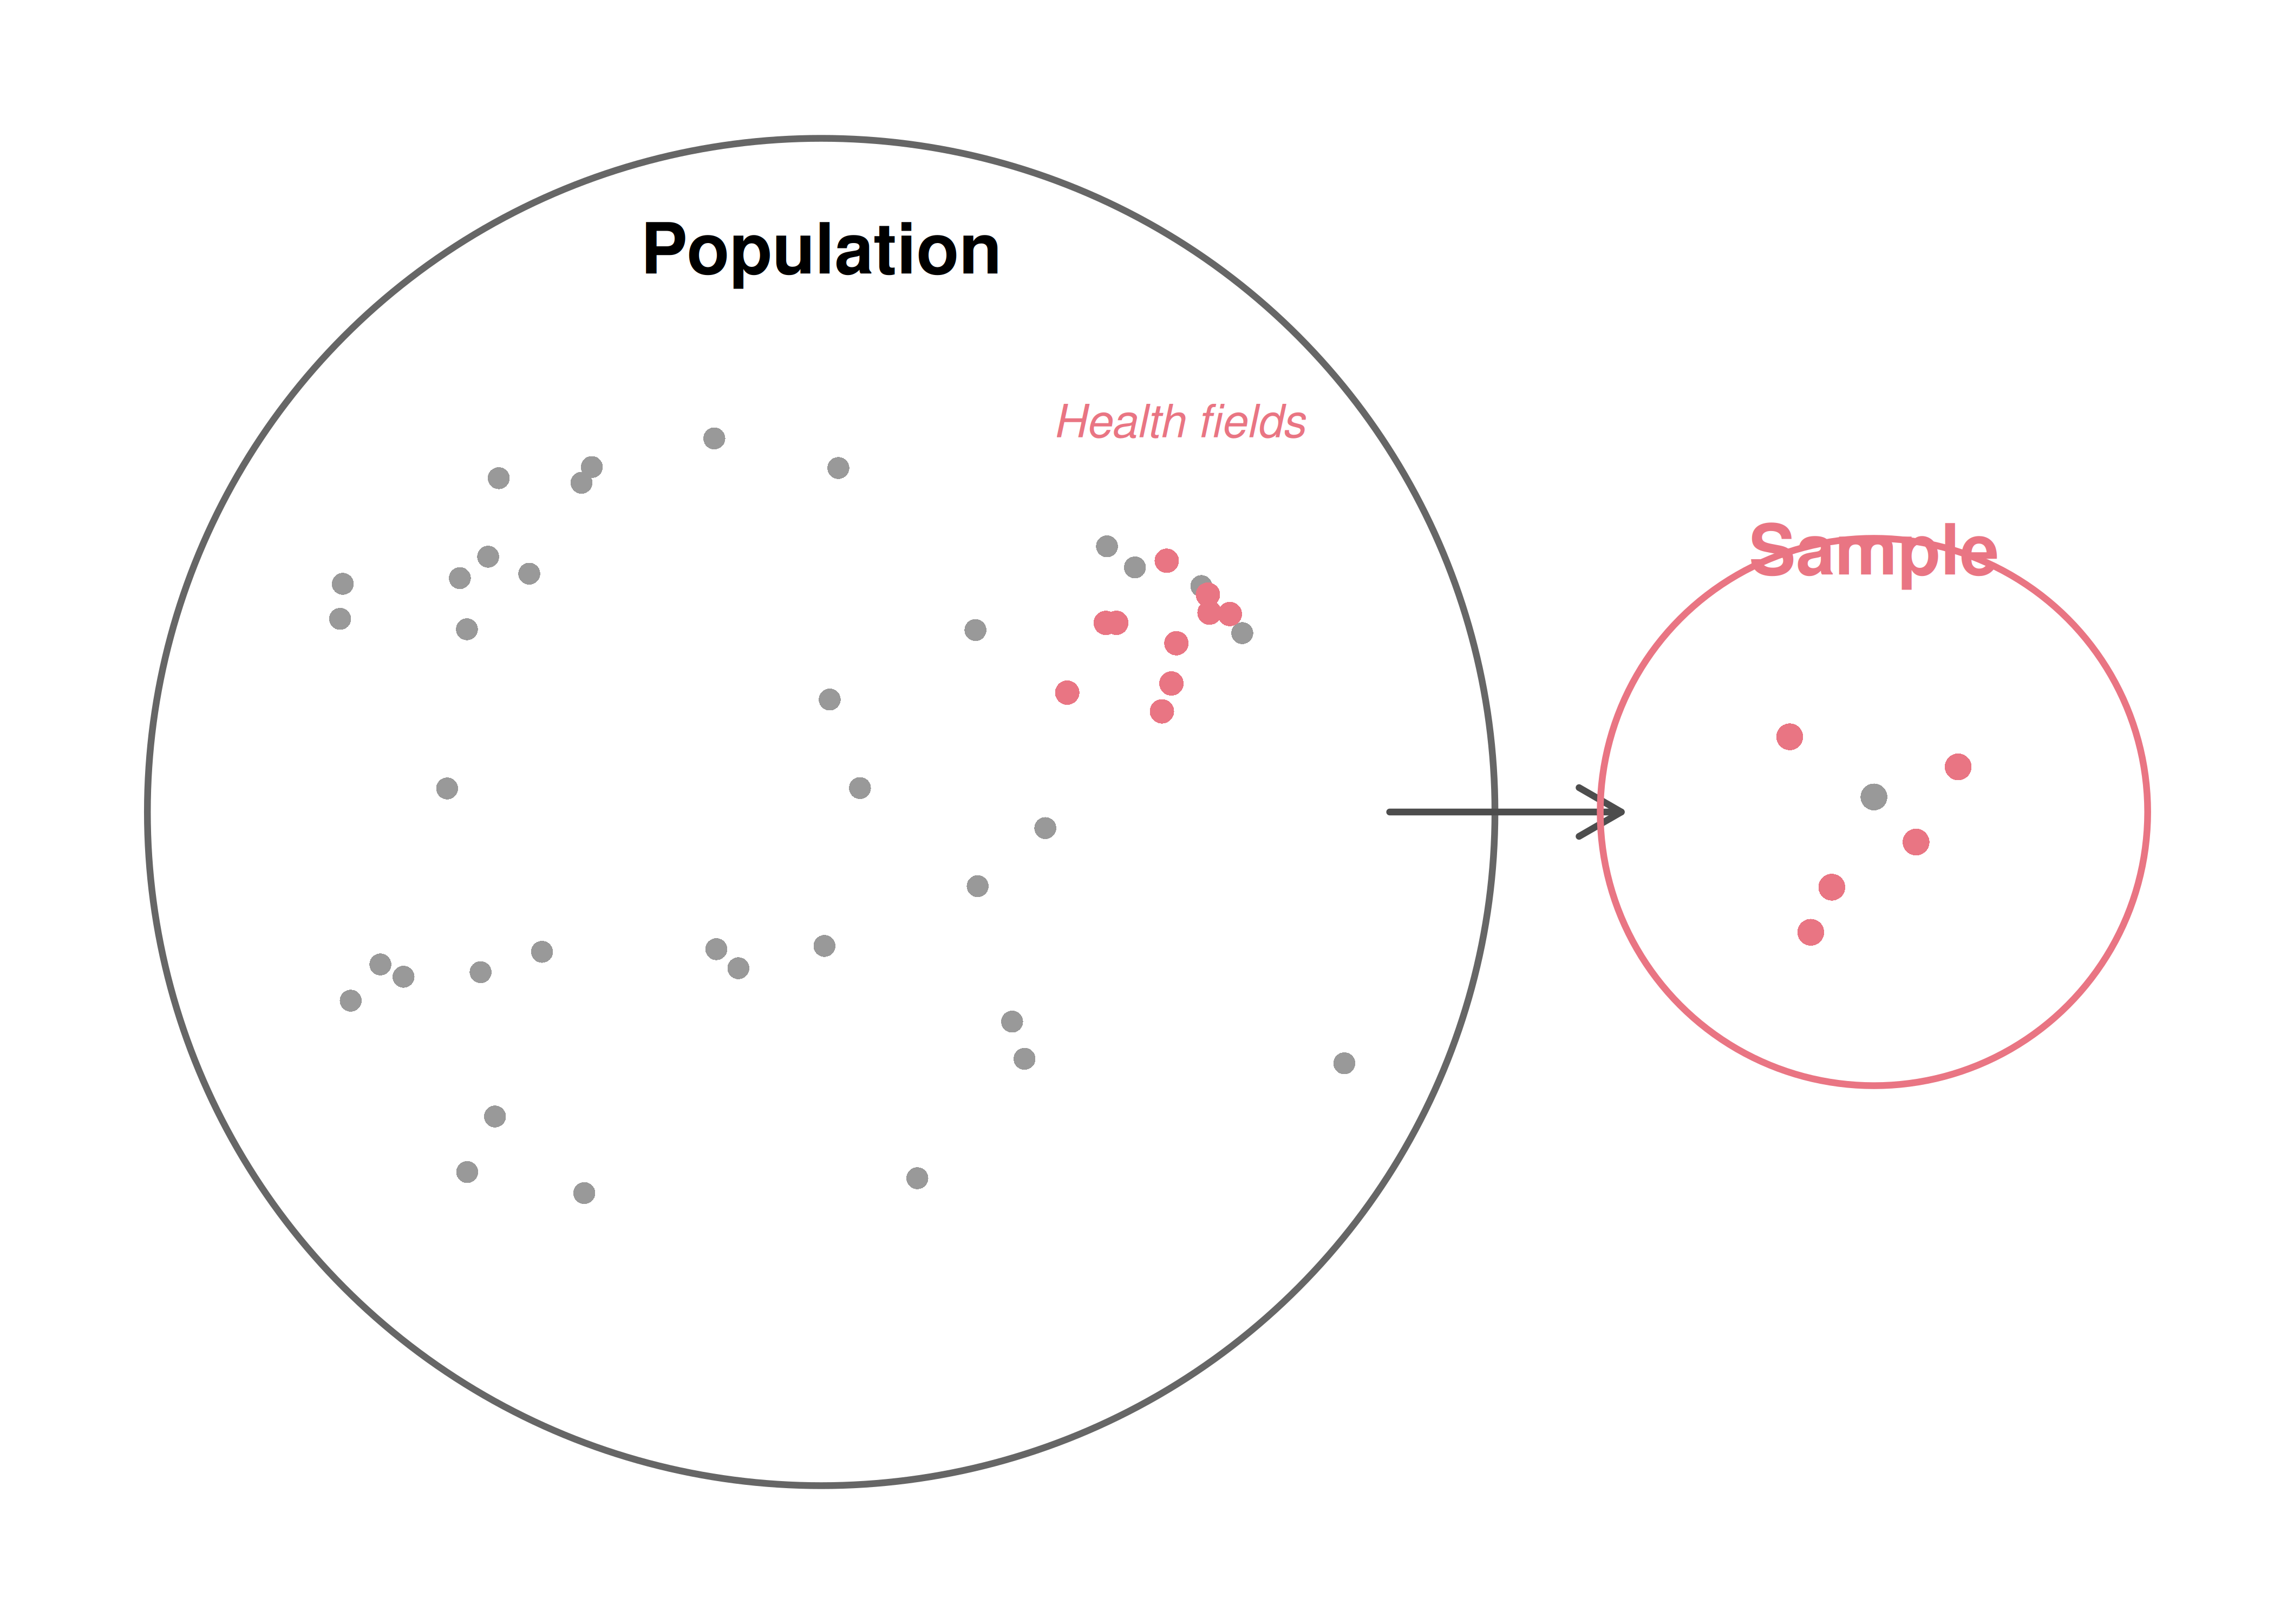
If someone is permitted to pick and choose exactly which individuals are included in the sample, it is entirely possible that the sample will overrepresent that person’s interests — even if the bias is unintentional. Sampling randomly helps address this problem.
A simple random sample (SRS) is a sample drawn so that each case in the population has an equal chance of being included, and the selection of any one case is independent of the selection of any other case. This is equivalent to drawing names out of a hat.
The act of taking a simple random sample helps minimize bias. However, bias can still creep in, and it helps to separate two quite different ways that happens. Some biases come from how the sample was chosen; others arise after the sample is chosen, from how people respond or how the response is measured.
Sampling bias arises from the way cases are selected: the selection mechanism systematically over- or under-represents part of the population. Non-sampling bias arises after selection — from who actually responds, from how questions are asked, or from how a measurement is taken. A perfectly drawn random sample can still be undone by non-sampling bias.
2.2.1 Sampling bias
One common form is a convenience sample, where individuals who are easily accessible are more likely to be included. For instance, if a political survey is conducted by stopping people on a single street corner, the results will not represent the broader city. It is often difficult to discern what sub-population a convenience sample actually represents.
A second form is voluntary response bias, where the sample consists of people who selected themselves into it. Online polls, call-in surveys, and product reviews all work this way, and the people motivated to take part are rarely a cross-section of everyone who could have.
We can easily access ratings for products, sellers, and companies on websites like Amazon. These ratings come only from people who go out of their way to provide a rating. If 50% of online reviews for a product are negative, do you think this means that 50% of buyers are dissatisfied with the product? Why or why not?
Show answer
Probably not. People tend to be more motivated to leave a review when they have a negative experience than when a product meets expectations. This creates a negative bias in product ratings — dissatisfied customers are overrepresented among reviewers. This is voluntary response bias — a sampling bias, because the people who end up in the sample selected themselves, and they differ systematically from the buyers who stayed silent.2.2.2 Non-sampling bias
Even a genuine random sample can mislead. Suppose people are selected at random for a survey — for example, by dialing random phone numbers — but many of them never answer. If only 30% of the people sampled actually respond, then it is unclear whether the results are representative of the entire population. This non-response bias can skew results, because the 30% who reply may differ systematically from the 70% who do not.
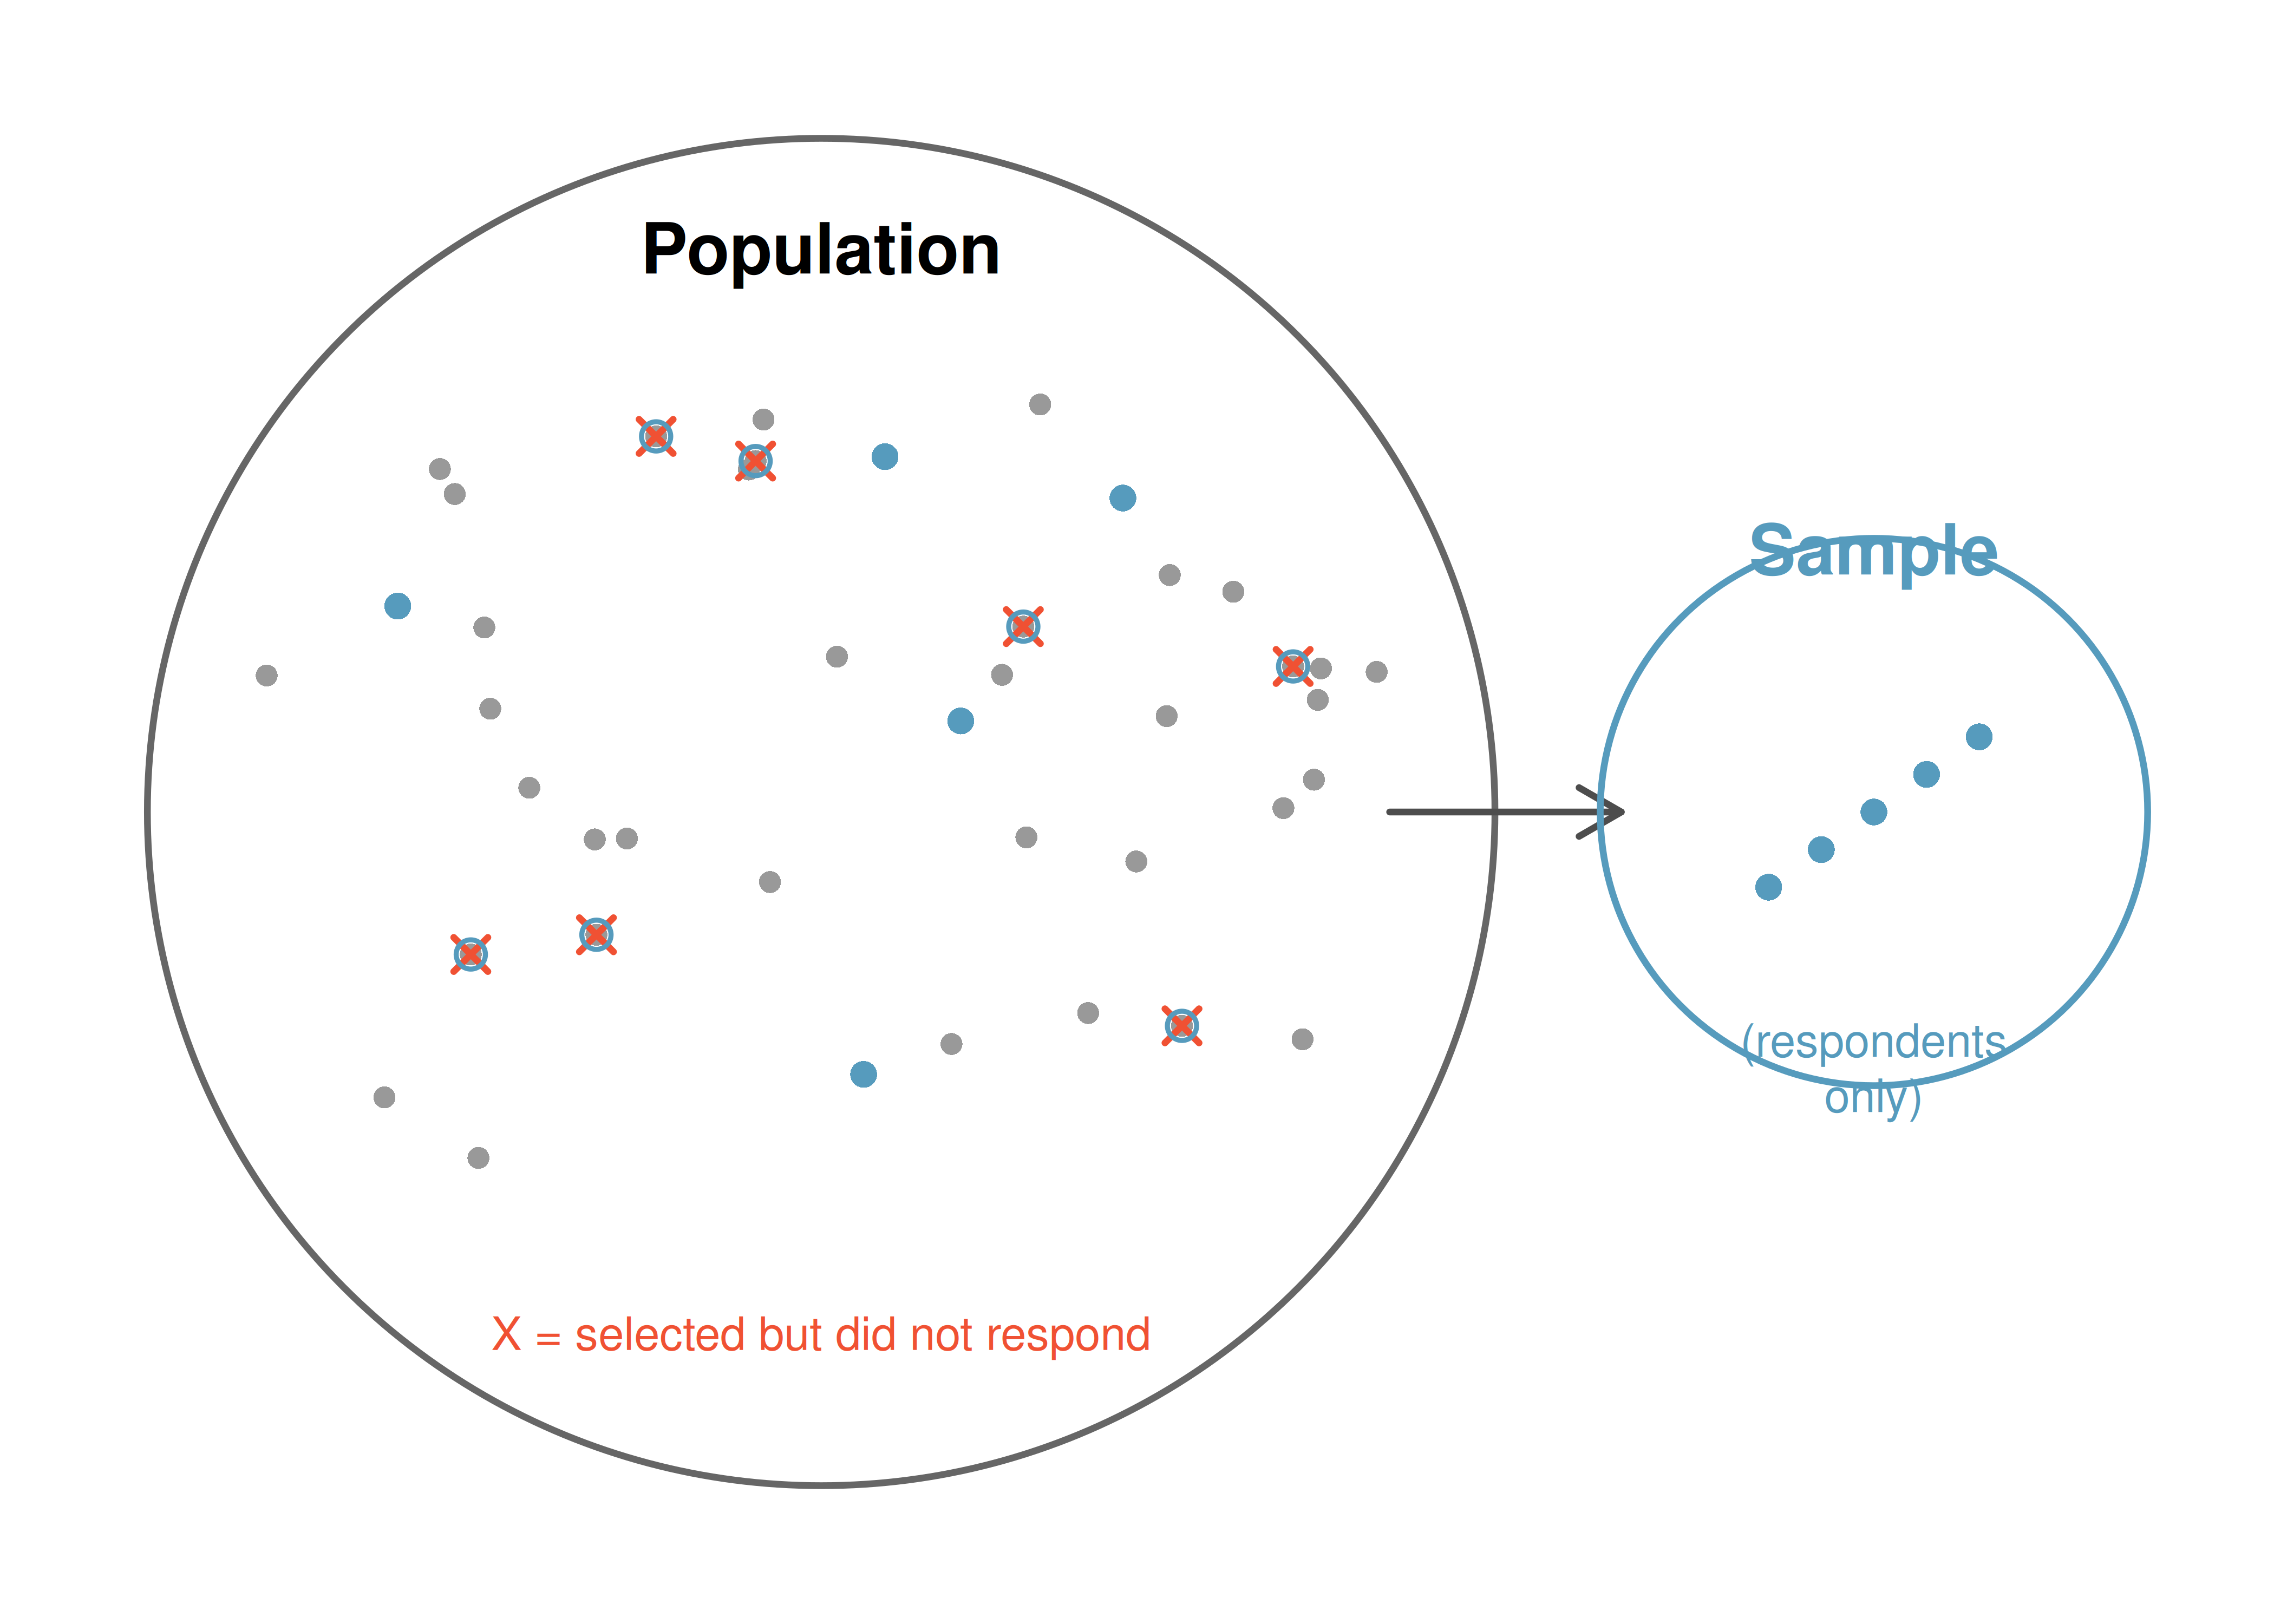
Non-response is not the only way this happens. Response bias occurs when the measurement itself distorts the answer — a leading question (“Don’t you agree that …?”), a sensitive topic people under-report, or an interviewer whose presence changes what respondents are willing to say. Neither problem is fixed by sampling more carefully; both are fixed by asking better and following up harder.
2.3 Random sampling methods
Almost all statistical methods are based on the notion of randomness. If data are not collected using a random process from a population, then the estimates and the errors associated with those estimates are not reliable. Here we consider four random sampling techniques: simple random sampling, stratified sampling, cluster sampling, and multistage sampling.
2.3.1 Simple random sampling
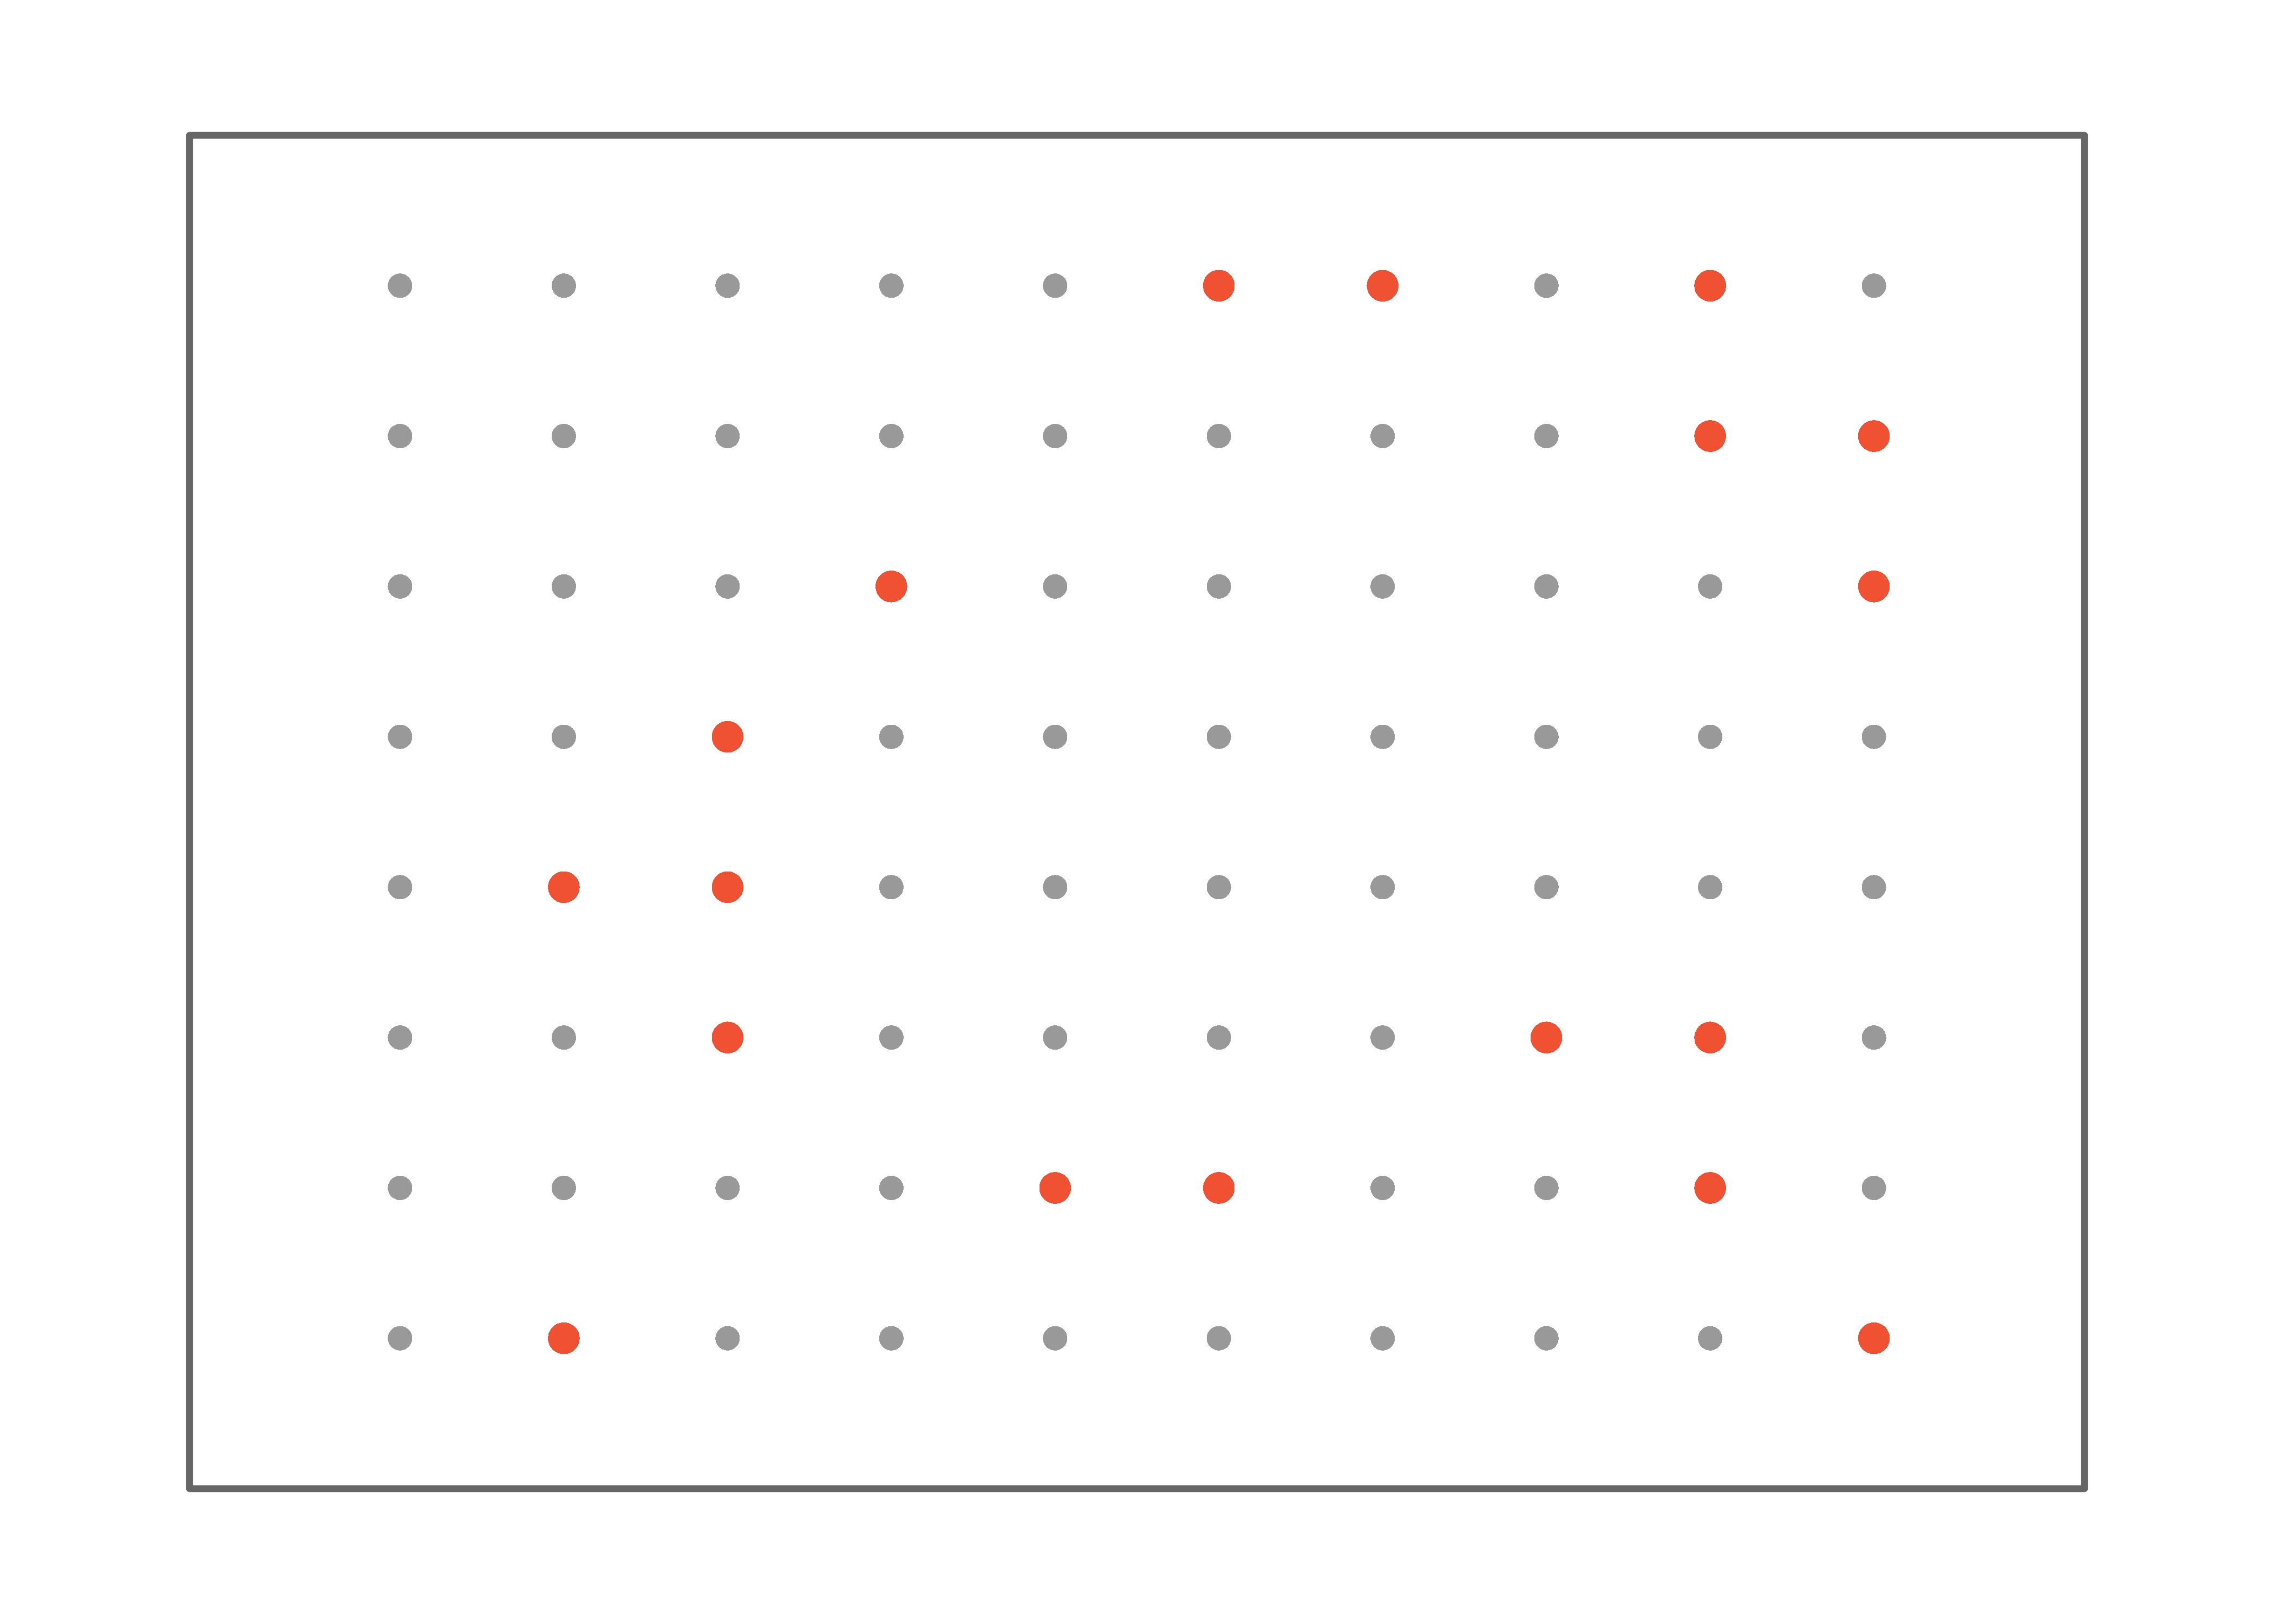
Simple random sampling is the most intuitive form of random sampling. Consider the salaries of Major League Baseball (MLB) players, where each player belongs to one of the league’s 30 teams. To take a simple random sample of 120 baseball players and their salaries, we could write the names of all players onto slips of paper, drop the slips into a bucket, mix them thoroughly, then draw out 120 slips. In general, a sample is called “simple random” if each case in the population has an equal chance of being included in the final sample and knowing that a particular case is included tells us nothing about which other cases are included. (This population is actually small — there are fewer than 1,000 MLB players — so a full census would be feasible here; we use it only because the setting is familiar.)
2.3.2 Stratified sampling
Stratified sampling is a divide-and-conquer strategy. The population is divided into groups called strata. The strata are chosen so that similar cases are grouped together, then a second sampling method (usually simple random sampling) is used within each stratum. In the baseball salary example, each of the 30 teams could represent a stratum, since some teams have much larger payrolls than others. We might randomly sample 4 players from each team to get our sample of 120.
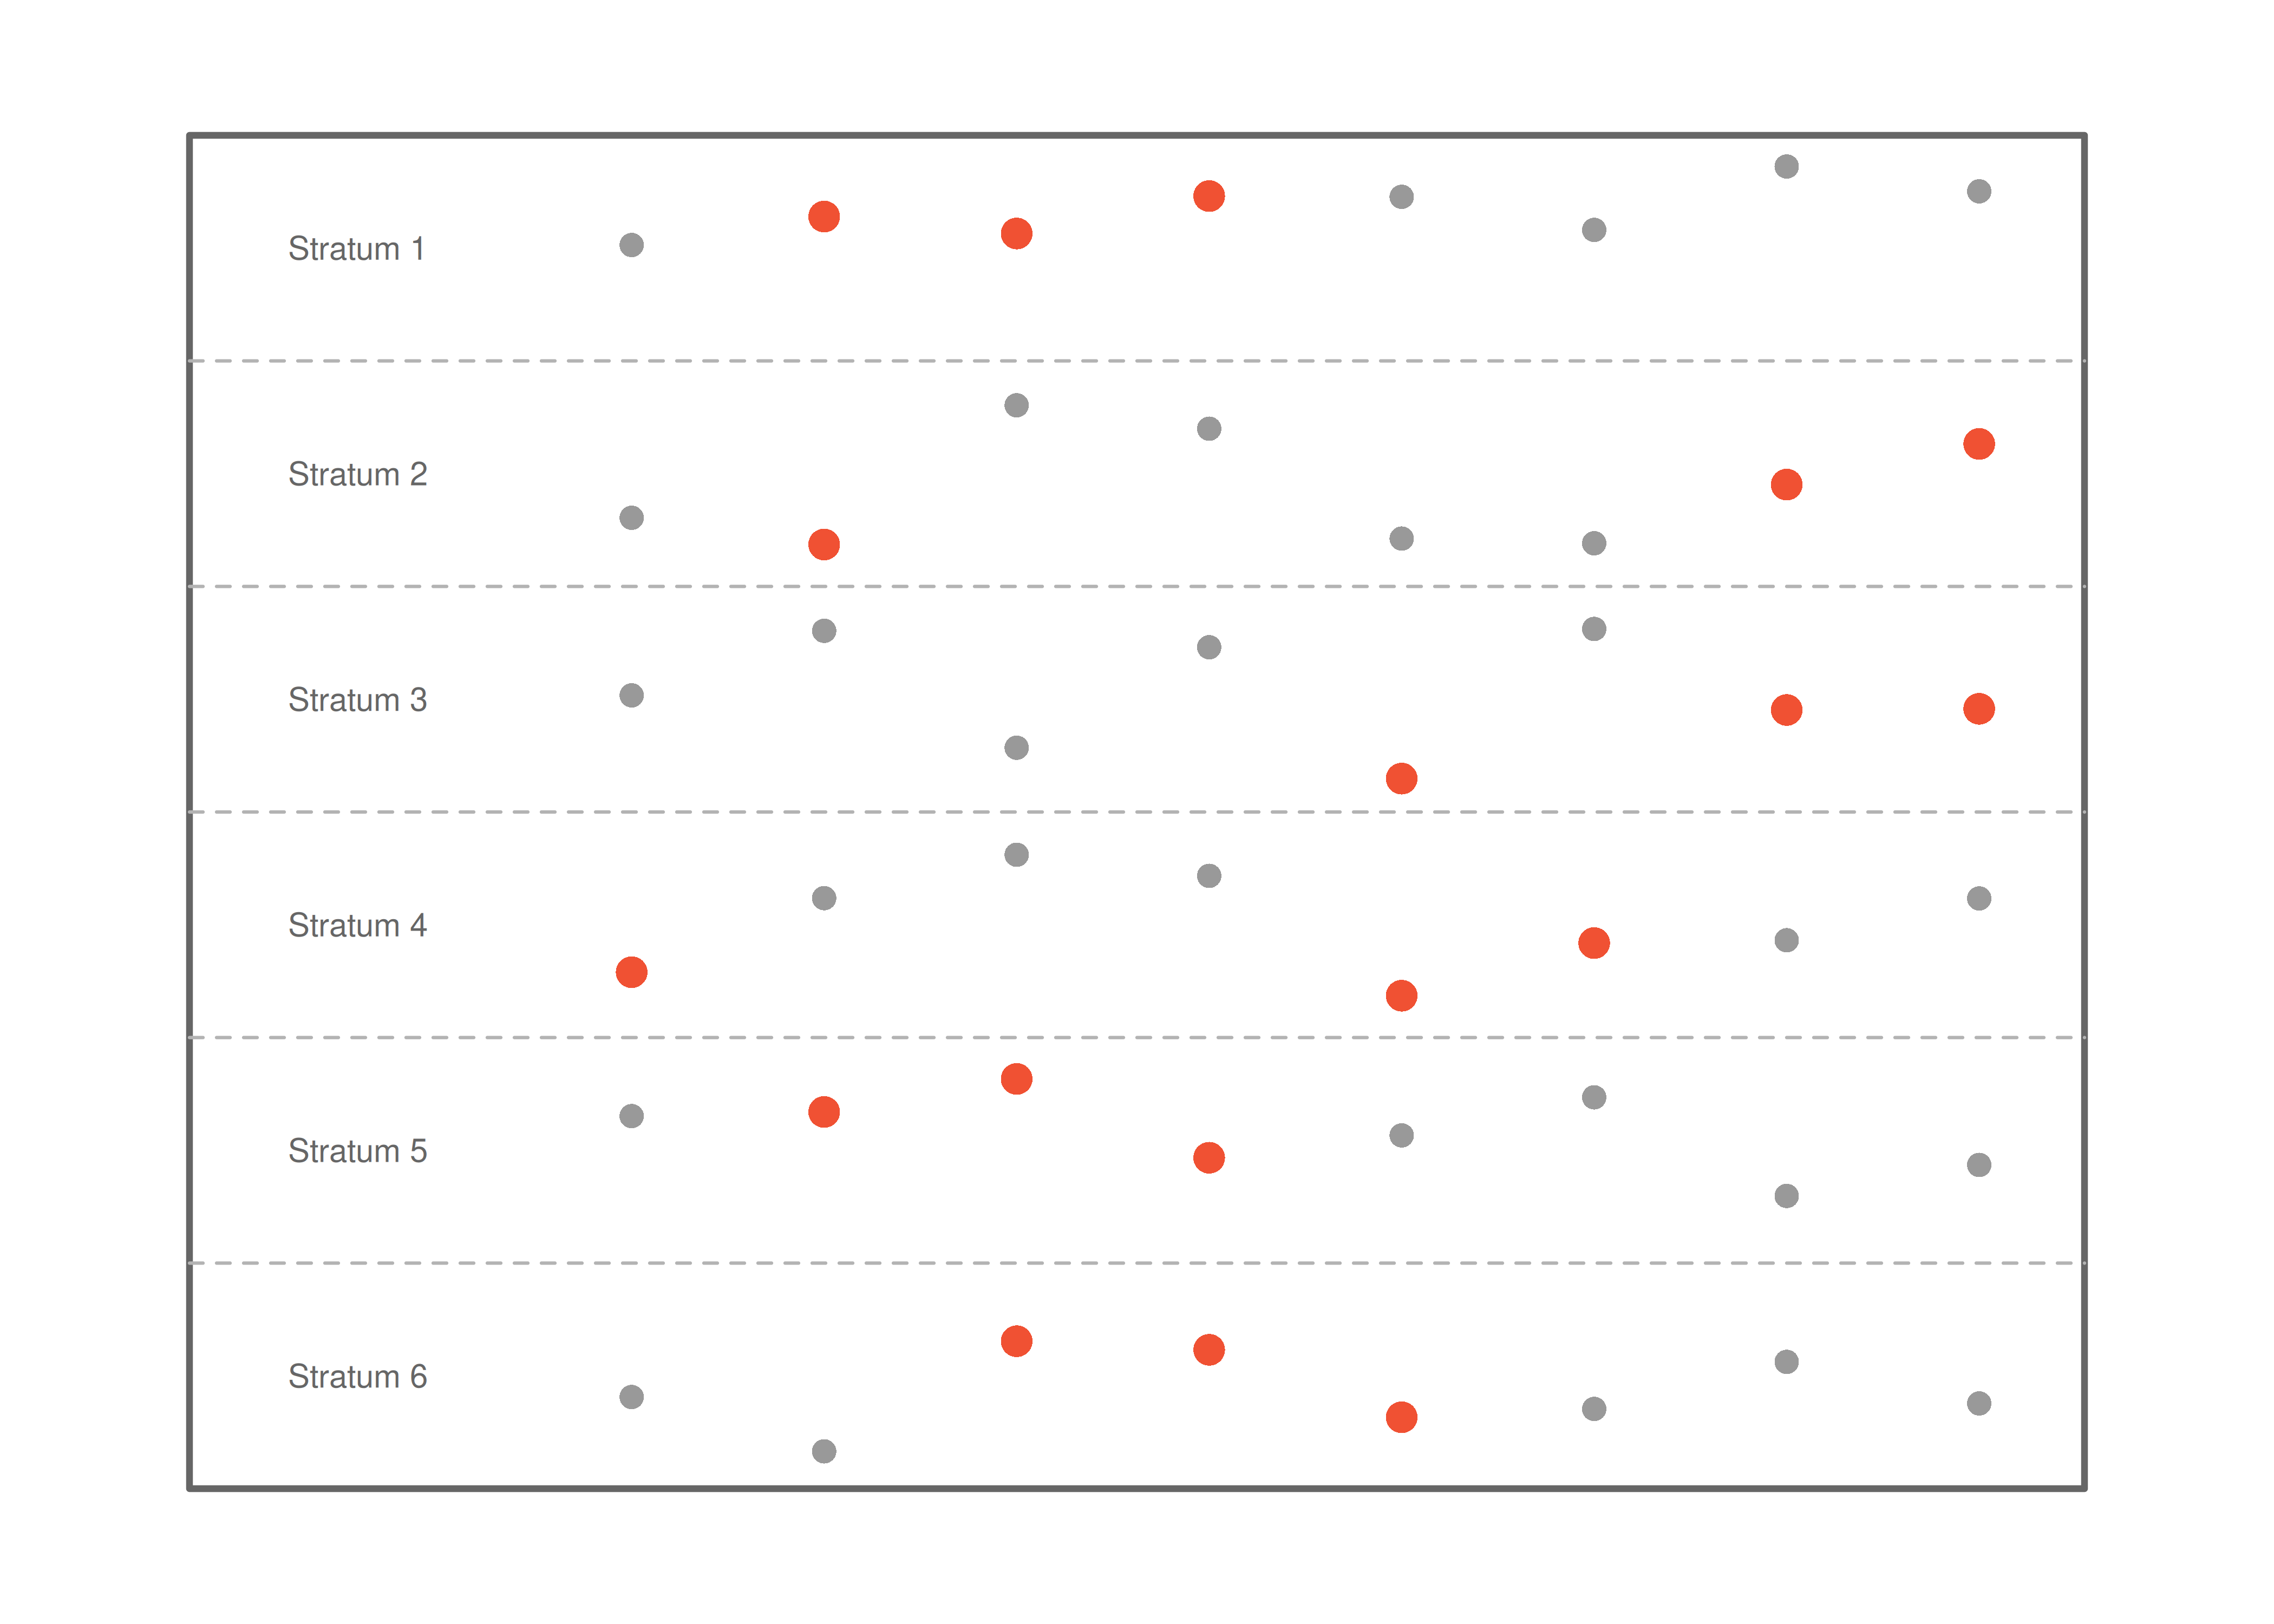
Stratified sampling is especially useful when cases within each stratum are very similar with respect to the outcome of interest.
Why is it beneficial for cases within each stratum to be very similar?
If cases within a stratum are similar, we can get a very stable (precise) estimate for each subgroup. When we combine these stratum-level estimates into a single estimate for the full population, the overall estimate will tend to be more precise because each individual component is itself more precise.
2.3.3 Cluster sampling
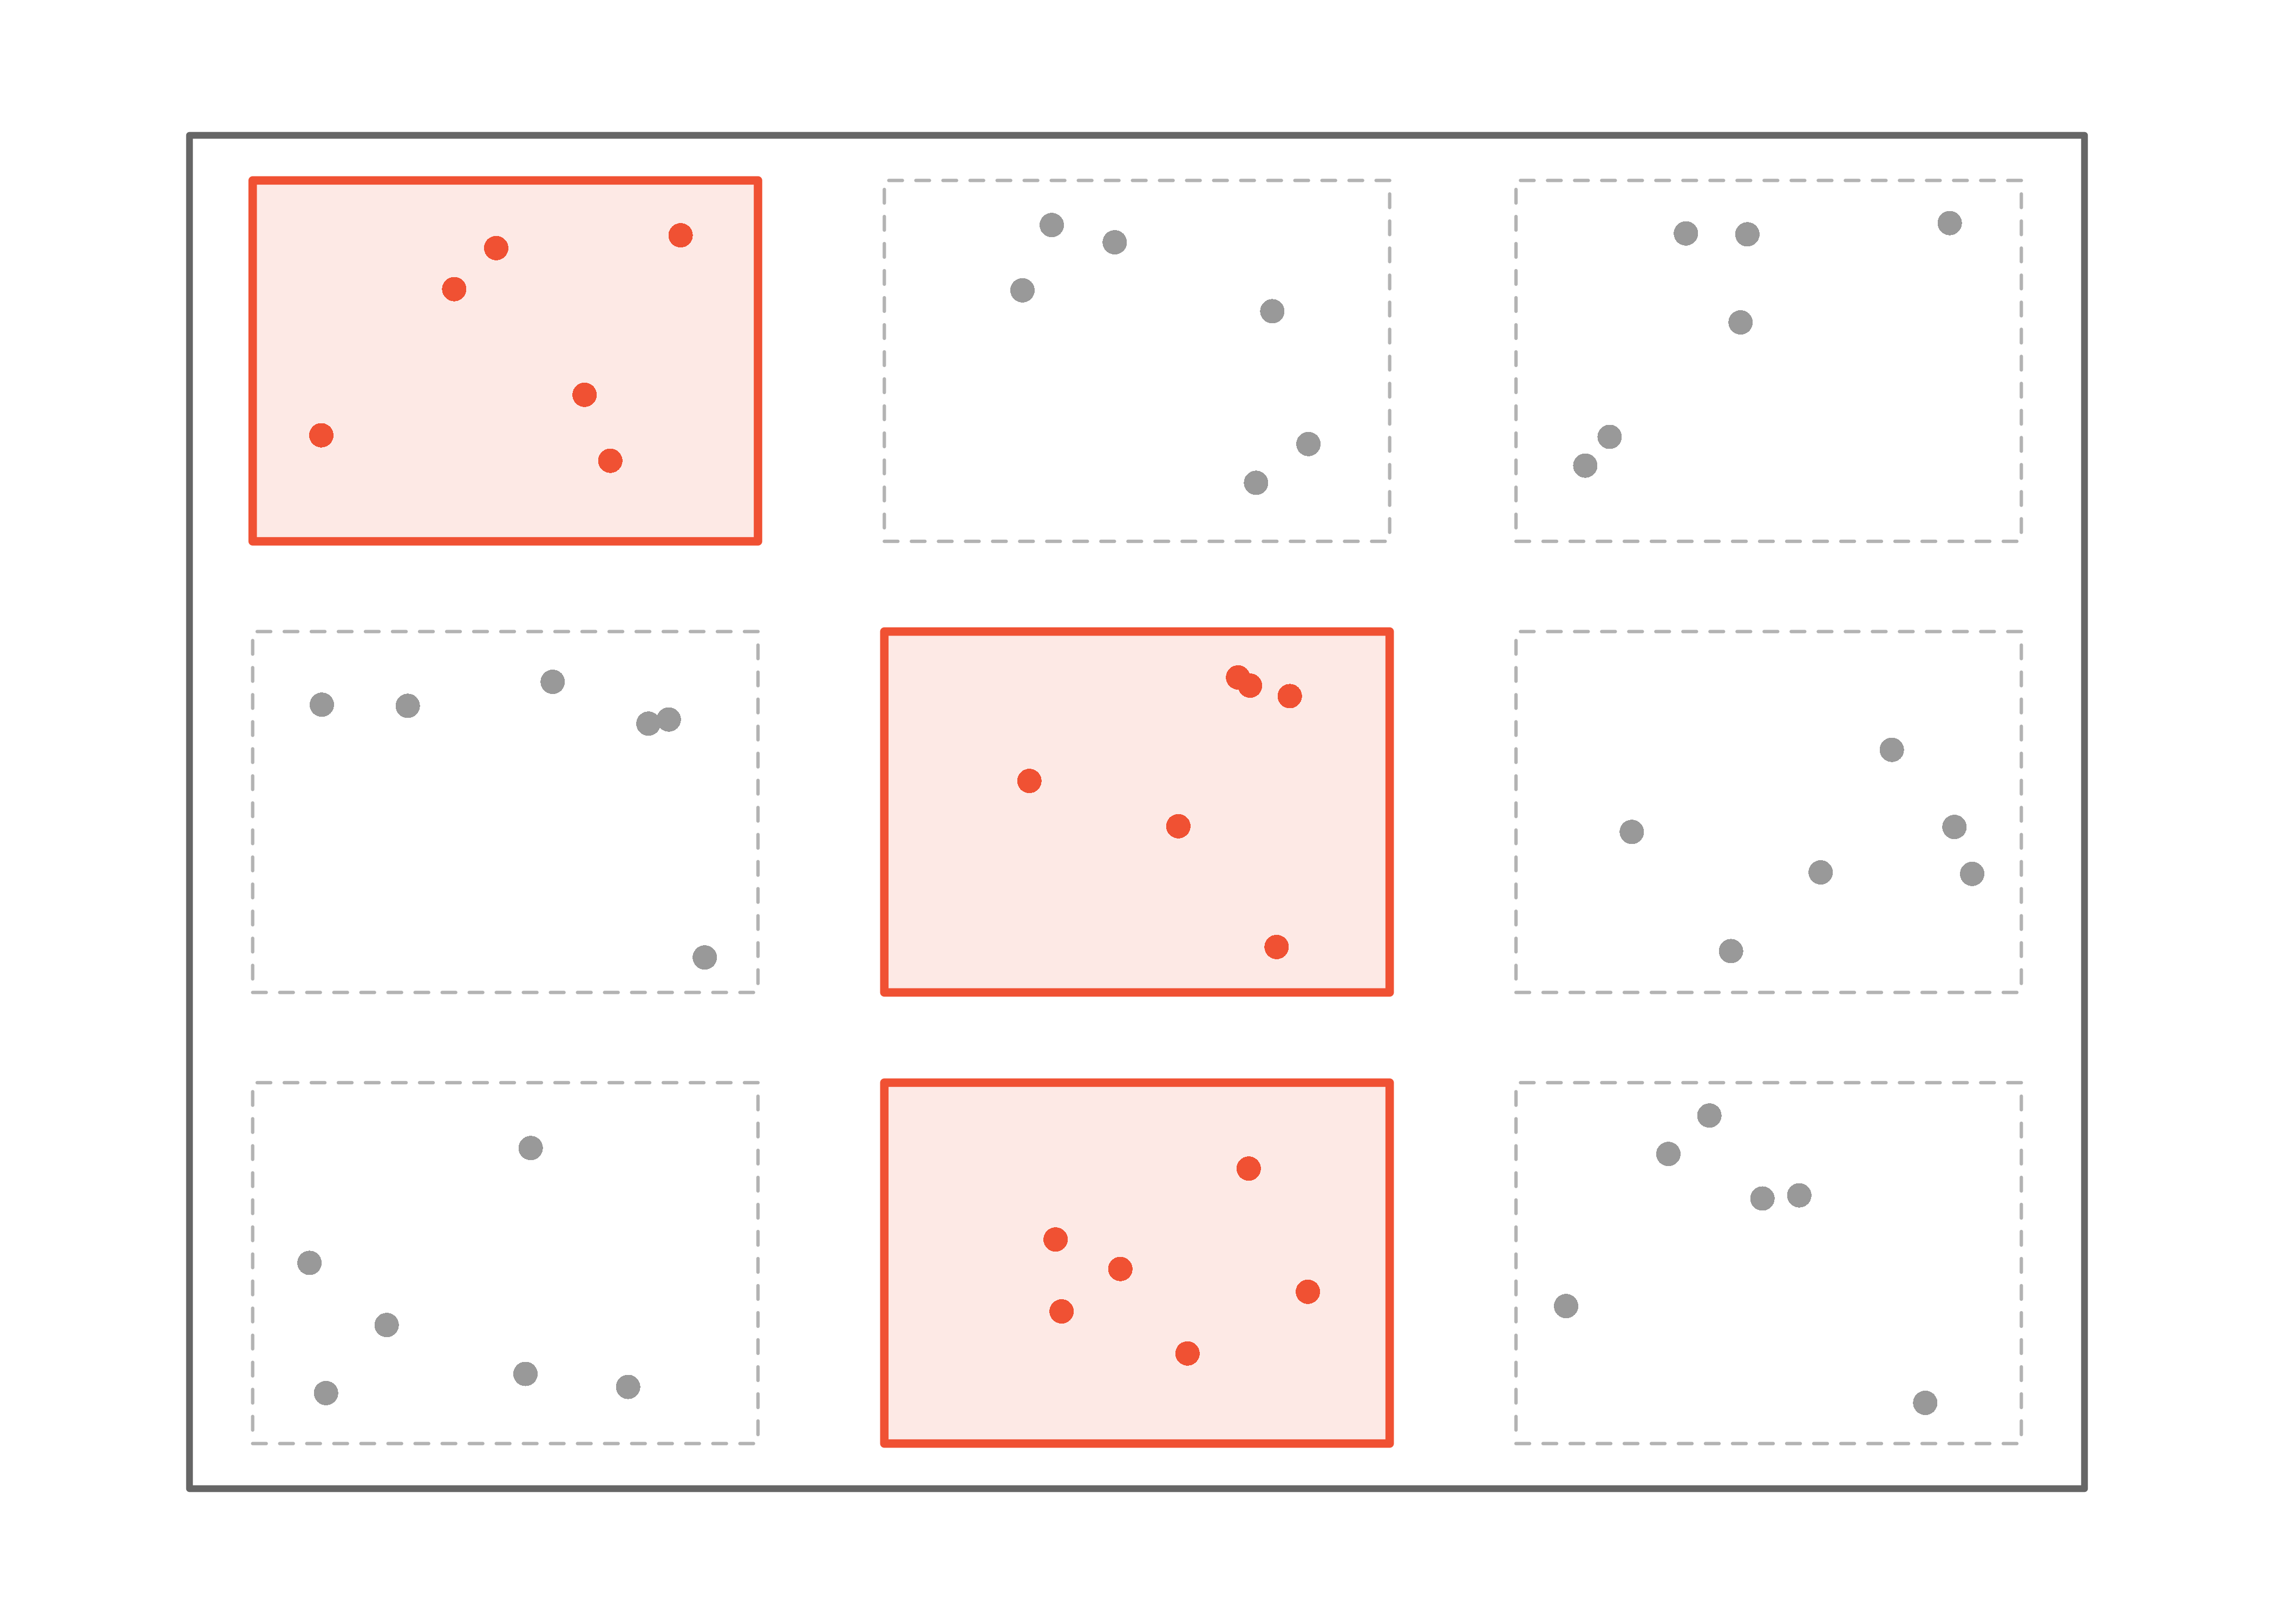
In a cluster sample, we break up the population into many groups called clusters, then randomly select a fixed number of clusters and include all observations from each selected cluster in the sample.
2.3.4 Multistage sampling
A multistage sample is like a cluster sample, but instead of keeping all observations in each selected cluster, we take a random sample within each selected cluster.
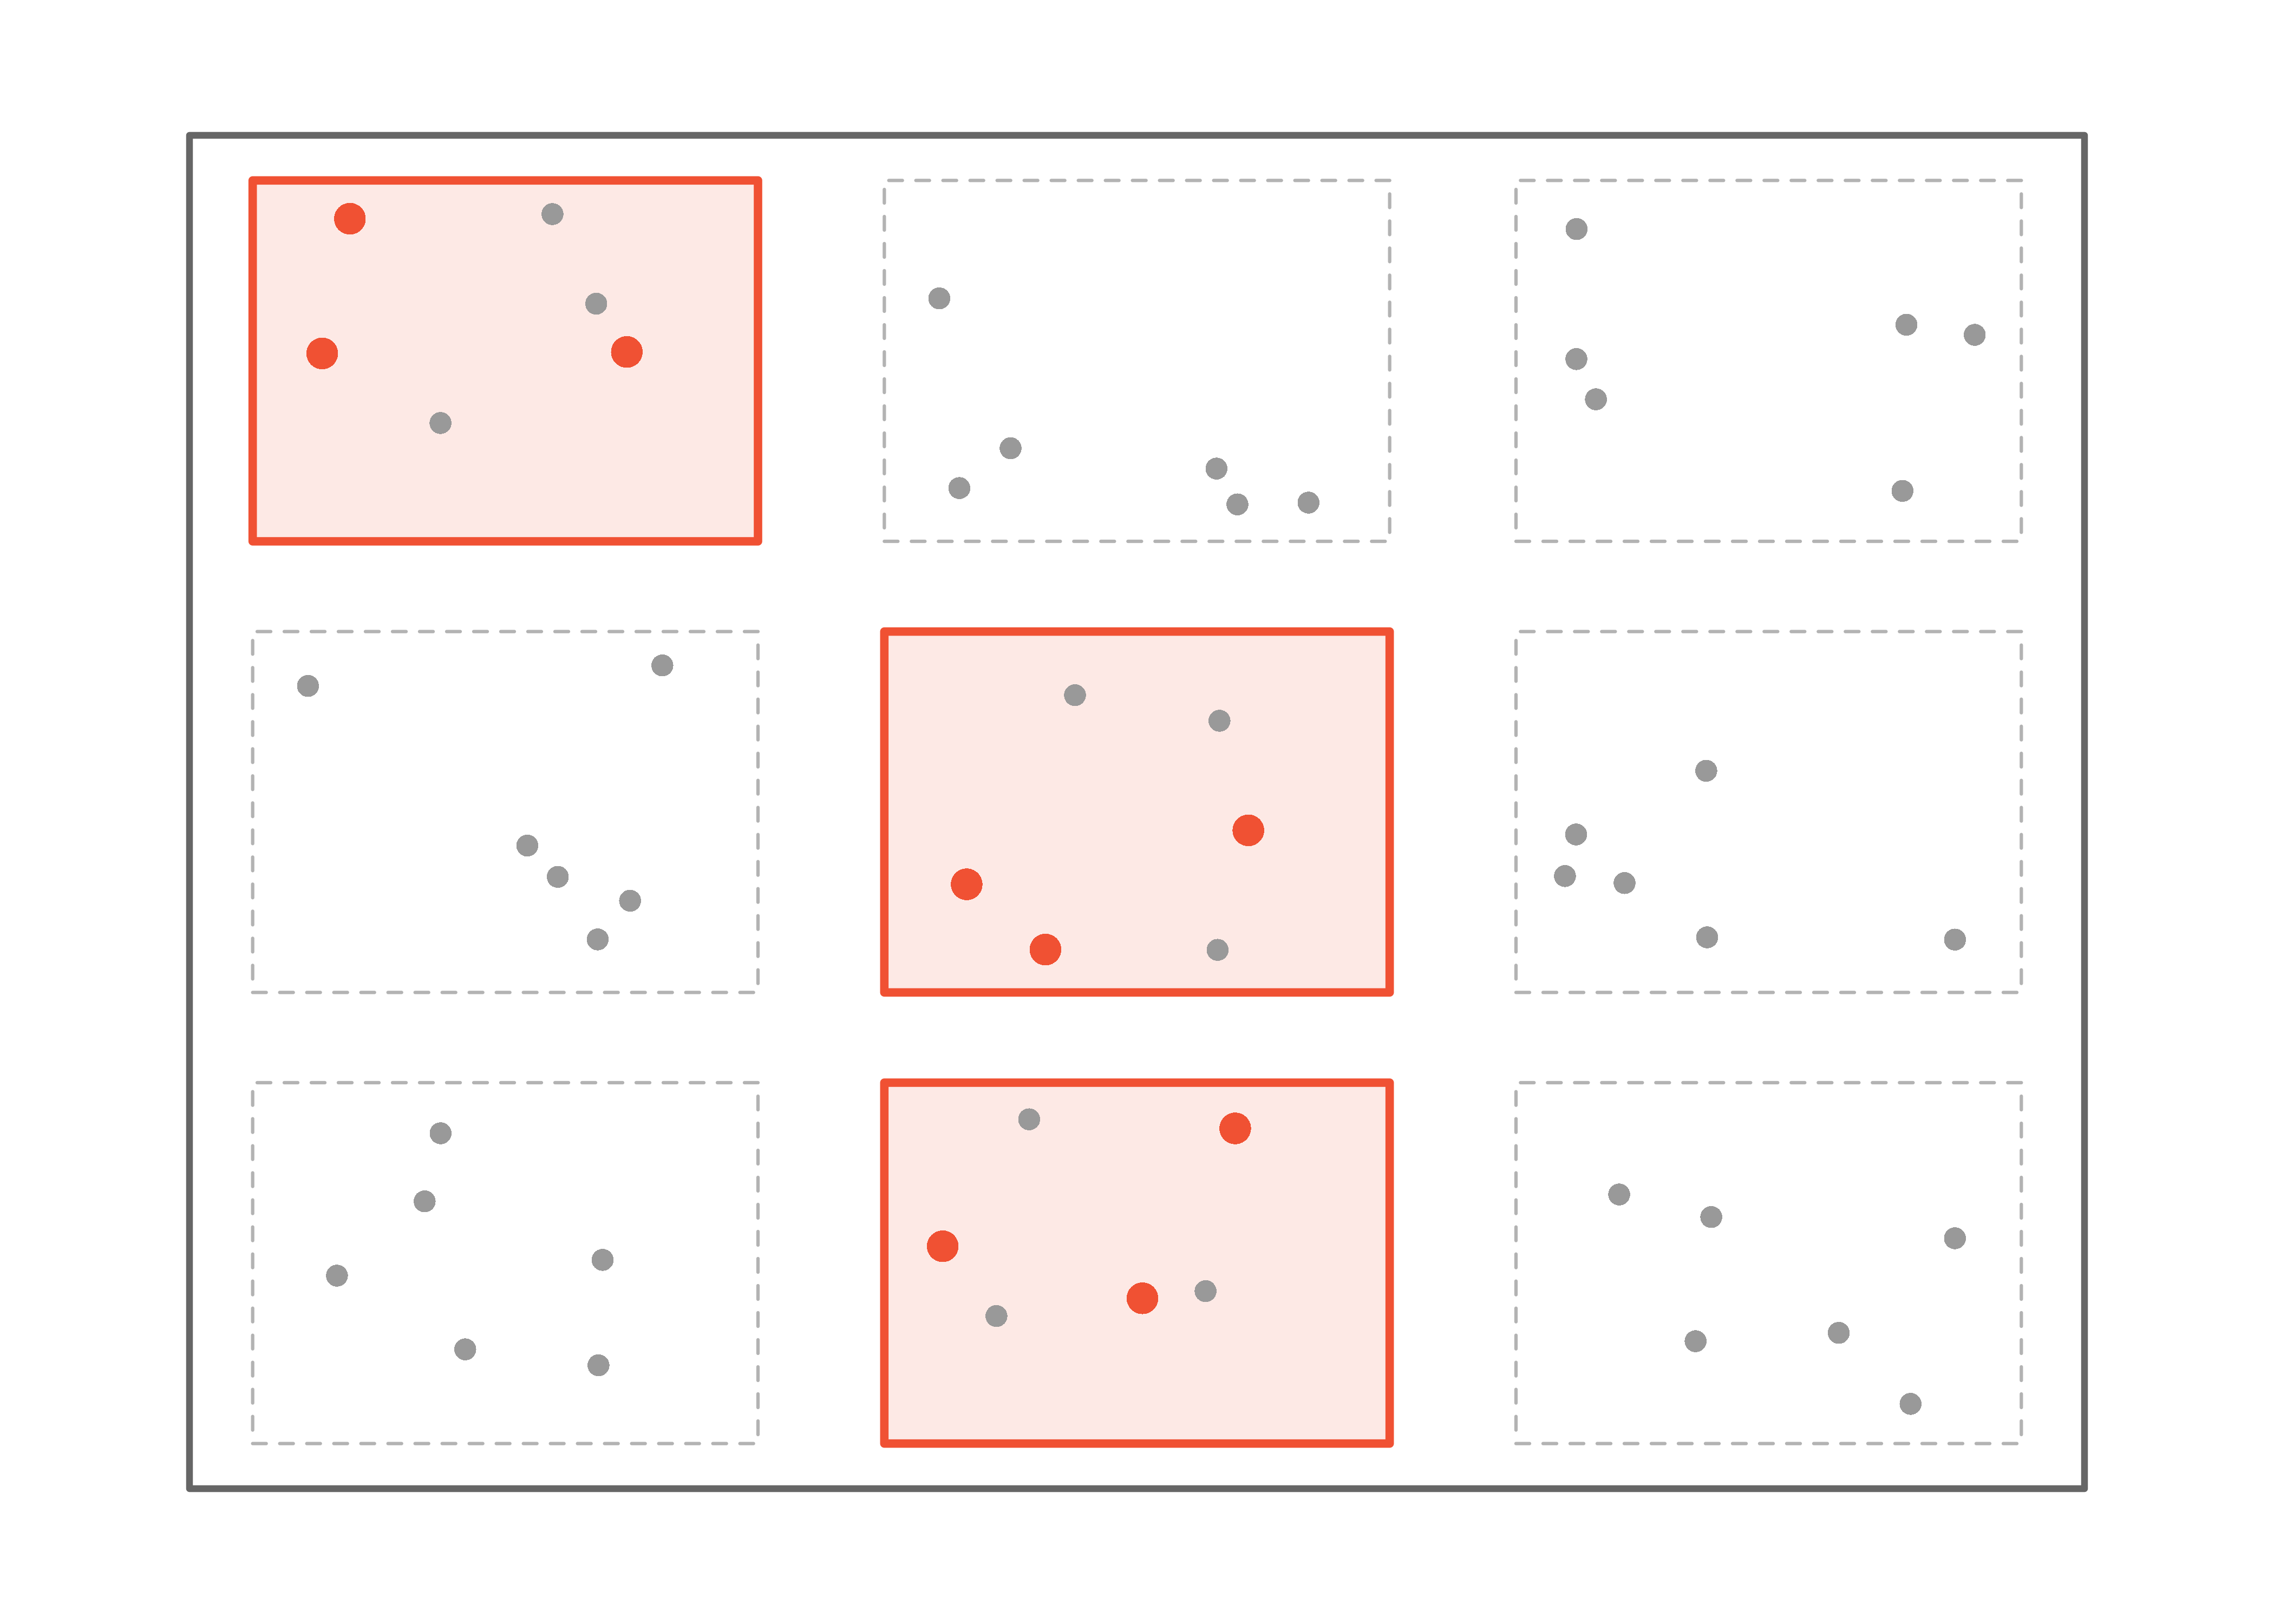
Cluster and multistage sampling can be more economical than other techniques. Unlike stratified sampling, these approaches work best when there is a lot of case-to-case variability within a cluster but the clusters themselves are fairly similar to one another. For example, if neighborhoods represent clusters, then cluster sampling works best when the residents within each neighborhood are diverse.
Suppose we want to estimate the malaria rate in a densely tropical portion of rural Indonesia. There are 30 villages in the region, each more or less like the next, but the distances between villages are substantial. We want to test 150 individuals for malaria. What sampling method should we use?
A simple random sample would likely draw individuals from all 30 villages, making data collection very expensive given the travel distances. Stratified sampling would be difficult because it is unclear how to group individuals into similar strata. However, cluster or multistage sampling are excellent choices. With multistage sampling, we could randomly select, say, 15 of the 30 villages, then randomly select 10 people from each village. This would substantially reduce data collection costs while still yielding reliable information.
2.3.5 Comparing the four methods
The table below summarizes the key features of each sampling method:
| Method | How it works | Best used when… |
|---|---|---|
| Simple random | Every case has an equal chance of selection | Population is relatively homogeneous and accessible |
| Stratified | Divide into similar groups (strata), then SRS within each | Known subgroups differ on the outcome of interest |
| Cluster | Randomly select entire groups (clusters) | Clusters are internally diverse but similar to each other; travel/cost is a concern |
| Multistage | Randomly select clusters, then SRS within each | Same as cluster, but clusters are large |
2.4 Experiments
An experiment is a study where the researchers actively assign treatments to cases. A treatment is a specific condition the researcher imposes on cases — one value of the explanatory variable (for example, a particular drug or dose). When this assignment uses randomization (e.g., a coin flip to decide which treatment a patient receives), it is called a randomized experiment. Randomized experiments are fundamentally important when trying to establish a causal connection between two variables.
2.4.1 Principles of experimental design
Well-designed experiments incorporate four key principles:
Controlling. Researchers assign treatments to cases and do their best to control any other differences between the groups. For example, when patients take a drug in pill form, some patients might take the pill with a sip of water while others drink a full glass. To control for the effect of water consumption, a doctor might instruct every patient to drink a 12-ounce glass of water with the pill.
Randomization. Researchers randomly assign subjects to treatment groups to account for variables that cannot be controlled. For example, some patients may be more susceptible to a disease than others due to their dietary habits. Randomly assigning patients to treatment or control groups helps even out such differences across groups.
Replication. The more cases researchers observe, the more accurately they can estimate the effect of the explanatory variable on the response. In a single study, we replicate by collecting a sufficiently large sample. At a minimum, we want multiple subjects per treatment group. Replication also refers to repeating an entire study to verify earlier findings. (The replication crisis refers to the ongoing problem in several scientific disciplines where past findings have failed to be replicated in new studies.)
Blocking. Researchers sometimes know or suspect that variables other than the treatment influence the response. They may first group individuals based on this variable into blocks and then randomize cases within each block to the treatment groups.1
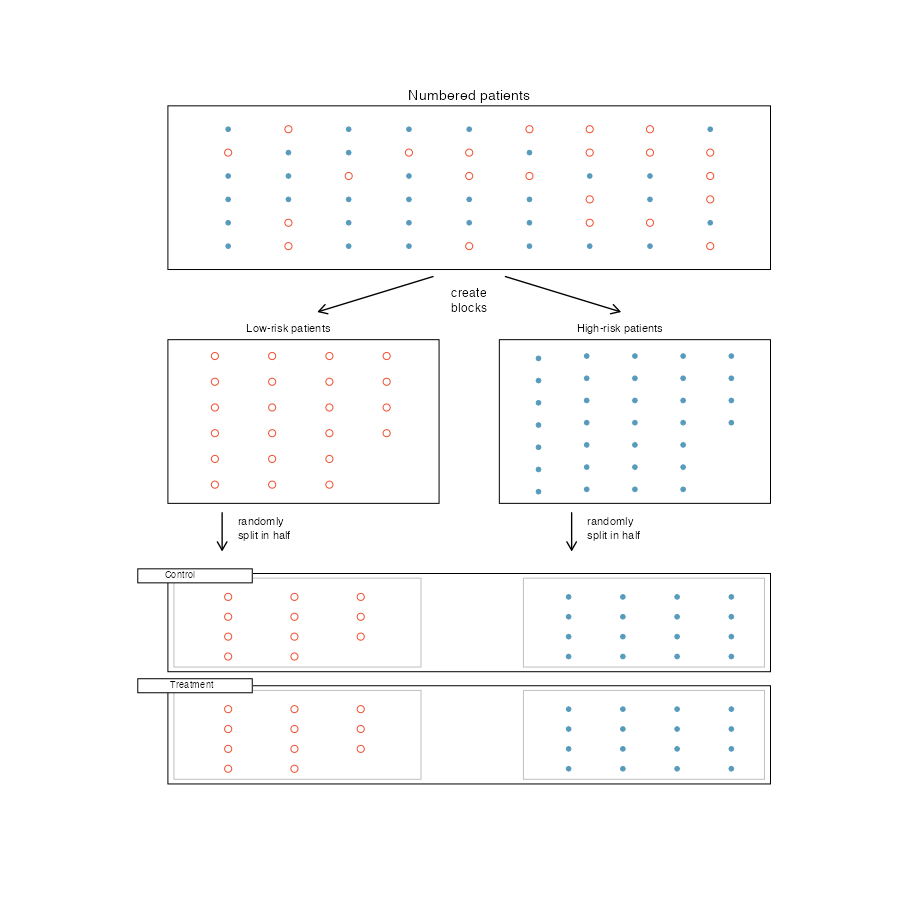
It is important to incorporate at least the first three principles into any study. Blocking is a slightly more advanced technique that adds precision when relevant grouping variables are known. Blocking is the experimental cousin of stratified sampling: both first group similar units together — strata when selecting a sample, blocks when assigning a treatment — so that a known source of variation is handled deliberately rather than left to chance.
Matched pairs are a common special case of blocking where each block has exactly two units. The most familiar version uses the same subject measured twice — a before/after design, or a crossover where each participant receives both treatments in random order. A different form pairs distinct subjects who match on a relevant variable (twins, littermates, students matched on baseline test score) and then randomizes the two treatments within each pair. A typical example: participants complete a mental-rotation test, get an hour of instruction, then take a parallel post-test — each person’s change score isolates the effect of instruction from their individual baseline ability. In both forms the pair acts as its own control, absorbing subject-to-subject variability that would otherwise make a real treatment effect harder to detect. (Later we will give that variability a name — the standard error — in the sampling variability chapter.) We revisit matched-pairs data — and the paired analysis it enables — in the confidence intervals for means chapter and the hypothesis tests for means chapter.
2.4.2 Reducing bias in human experiments
Randomized experiments are considered the gold standard for establishing cause-and-effect, but they do not automatically eliminate all bias. Human studies are a perfect example of where bias can unintentionally arise.
Consider a study where a new drug is tested to see if it reduces deaths in heart attack patients. Researchers designed a randomized experiment: study volunteers were randomly placed into two groups. The treatment group received the drug. The control group did not receive any drug treatment.
Put yourself in the place of a person in the study. If you are in the treatment group, you receive a promising new drug and may feel hopeful. A person in the control group receives nothing and might feel anxious. These emotional effects could influence health outcomes independently of the drug itself. This means there are actually two effects at play: the drug’s real effectiveness, and the emotional impact of knowing (or not knowing) that you are receiving treatment.
To prevent emotional effects from biasing the study, researchers want patients to be unaware of their group assignment — that is, the study should be blind. But if a patient in the control group receives nothing at all, they will know they are not getting treated. The solution is a placebo. An effective placebo is the key to making a study truly blind.
The patients are not the only ones who should be blinded. Doctors and researchers can also unintentionally bias a study. A doctor who knows a patient is receiving the real treatment might give that patient more attention or care. To guard against this, most modern studies use a double-blind setup.
A study is blind (or single-blind) if the patients do not know which treatment group they are in. A placebo is a fake treatment (such as a sugar pill) given to the control group so that patients cannot tell whether they are receiving the real treatment. The placebo effect is the phenomenon where patients show improvement simply because they believe they are receiving treatment. A study is double-blind if neither the patients nor the doctors and researchers interacting with them know who is receiving which treatment.
Think back to the stent study described in Section 1.1. Is it an experiment? Was the study blinded? Was it double-blinded?
Show answer
The researchers assigned patients to treatment groups, so it is an experiment. However, patients could distinguish what treatment they received because a stent is a surgical procedure. There is no simple equivalent of a “placebo stent” (though sham surgeries do exist), so the study was likely not fully blinded. If the study was not blind, it could not be double-blind either.For the stent study, could the researchers have employed a placebo? If so, what would it have looked like?
Show answer
In principle, researchers could use a sham surgery — the patient undergoes a surgical procedure but does not actually receive the stent. Sham surgeries do exist in medical research, but they raise serious ethical questions because they expose control-group patients to the risks of surgery without the potential benefit of the treatment.There are always multiple viewpoints on experiments and placebos, and rarely is it obvious which approach is ethically “correct.” Is it ethical to use a sham surgery that creates risk for the patient? On the other hand, if we do not use one, we might promote a costly treatment that has no real effect, diverting resources from treatments that actually work.
2.5 Observational studies
An observational study is a study where no treatment has been explicitly applied or withheld by the researchers. The researchers simply observe and record what happens naturally.
Making causal conclusions based on experiments is often reasonable because researchers can randomly assign treatments. However, making causal conclusions from observational data is much more dangerous and is generally not recommended. Observational studies are typically only sufficient to show associations or to form hypotheses that can later be tested with experiments.
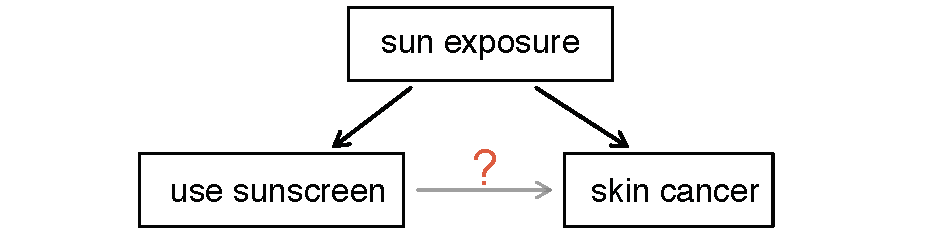
Suppose an observational study tracked sunscreen use and skin cancer, and found that people who used more sunscreen were more likely to have skin cancer. Does this mean sunscreen causes skin cancer?
No! Previous research tells us that sunscreen actually reduces skin cancer risk. The missing piece is sun exposure. People who spend a lot of time in the sun are more likely to use sunscreen and more likely to get skin cancer. Sun exposure is a confounding variable — it is associated with both sunscreen use and skin cancer, creating a misleading association between the two.
2.6 Confounding variables
A confounding variable is a variable that is associated with both the explanatory variable and the response variable. Because of this dual association, a confounding variable makes it impossible to determine whether the explanatory variable truly caused the observed response.
Confounding variables may or may not be measured as part of the study. Regardless, drawing cause-and-effect conclusions from observational studies is difficult because of the ever-present possibility of confounding.
Consider a classic example: ice cream sales and drowning rates both increase during summer months. If we looked only at the association between ice cream sales and drownings, we might (absurdly) conclude that ice cream causes drowning. The confounding variable is temperature (or season) — warm weather drives both increased ice cream consumption and increased swimming, which leads to more drowning incidents.
Suppose data show a negative association between homeownership rates and the percentage of housing units that are in multi-unit structures across U.S. counties. Is it reasonable to conclude that building more apartments causes homeownership rates to drop? Suggest a confounding variable.
Show answer
No, a causal conclusion is not warranted from observational data. A likely confounding variable is population density. Dense urban counties tend to have more multi-unit housing (apartments, condos) because of limited space, and they also tend to have lower homeownership rates because property values are higher. Population density is associated with both variables.2.6.1 Prospective and retrospective studies
Observational studies come in two forms:
A prospective study identifies individuals and collects information as events unfold going forward. For example, medical researchers might identify and follow a group of patients over many years to assess the influence of behavior on cancer risk. The famous Nurses’ Health Study, which started in 1976 and has collected data on over 275,000 nurses, is a prospective study.
A retrospective study collects data after events have already taken place — for example, by reviewing past medical records.
Some studies contain both prospective and retrospective elements. For instance, a medical study might gather information about participants’ histories (retrospective) and then follow them forward in time (prospective).
2.7 Random assignment and causation
The distinction between random sampling and random assignment is crucial. They serve different purposes and affect what conclusions we can draw.
- Random sampling (selecting subjects randomly from a population) allows us to generalize our findings to the broader population.
- Random assignment (randomly assigning subjects to treatment groups in an experiment) allows us to draw causal conclusions.
Random sampling and random assignment are independent concepts. A study can have one, both, or neither. The type of randomization determines the scope of conclusions we can draw.
A company wants to know whether a new keyboard layout increases typing speed. They recruit 40 volunteers from their office, randomly assign 20 to train on the new layout and 20 to continue with the standard layout, then measure typing speed after one month.
Can the company conclude that the new layout causes faster typing? Can they generalize the results to all office workers?
Because the study used random assignment to treatment groups, the company can make a causal conclusion: any observed difference in typing speed can be attributed to the keyboard layout rather than to pre-existing differences between the groups. However, the 40 volunteers were not randomly selected from all office workers — they are a convenience sample of volunteers from one company. Therefore, the results may not generalize to all office workers.
2.8 Scope of inference
The scope of inference — what conclusions we can draw from a study — depends on how data were collected. The following table summarizes the four possible scenarios:
| Random assignment (to treatments) | No random assignment | |
|---|---|---|
| Random sampling (from population) | Can generalize to the population and can draw causal conclusions | Can generalize to the population, but cannot draw causal conclusions |
| No random sampling | Cannot generalize to the population, but can draw causal conclusions (for subjects like those in the study) | Cannot generalize and cannot draw causal conclusions |
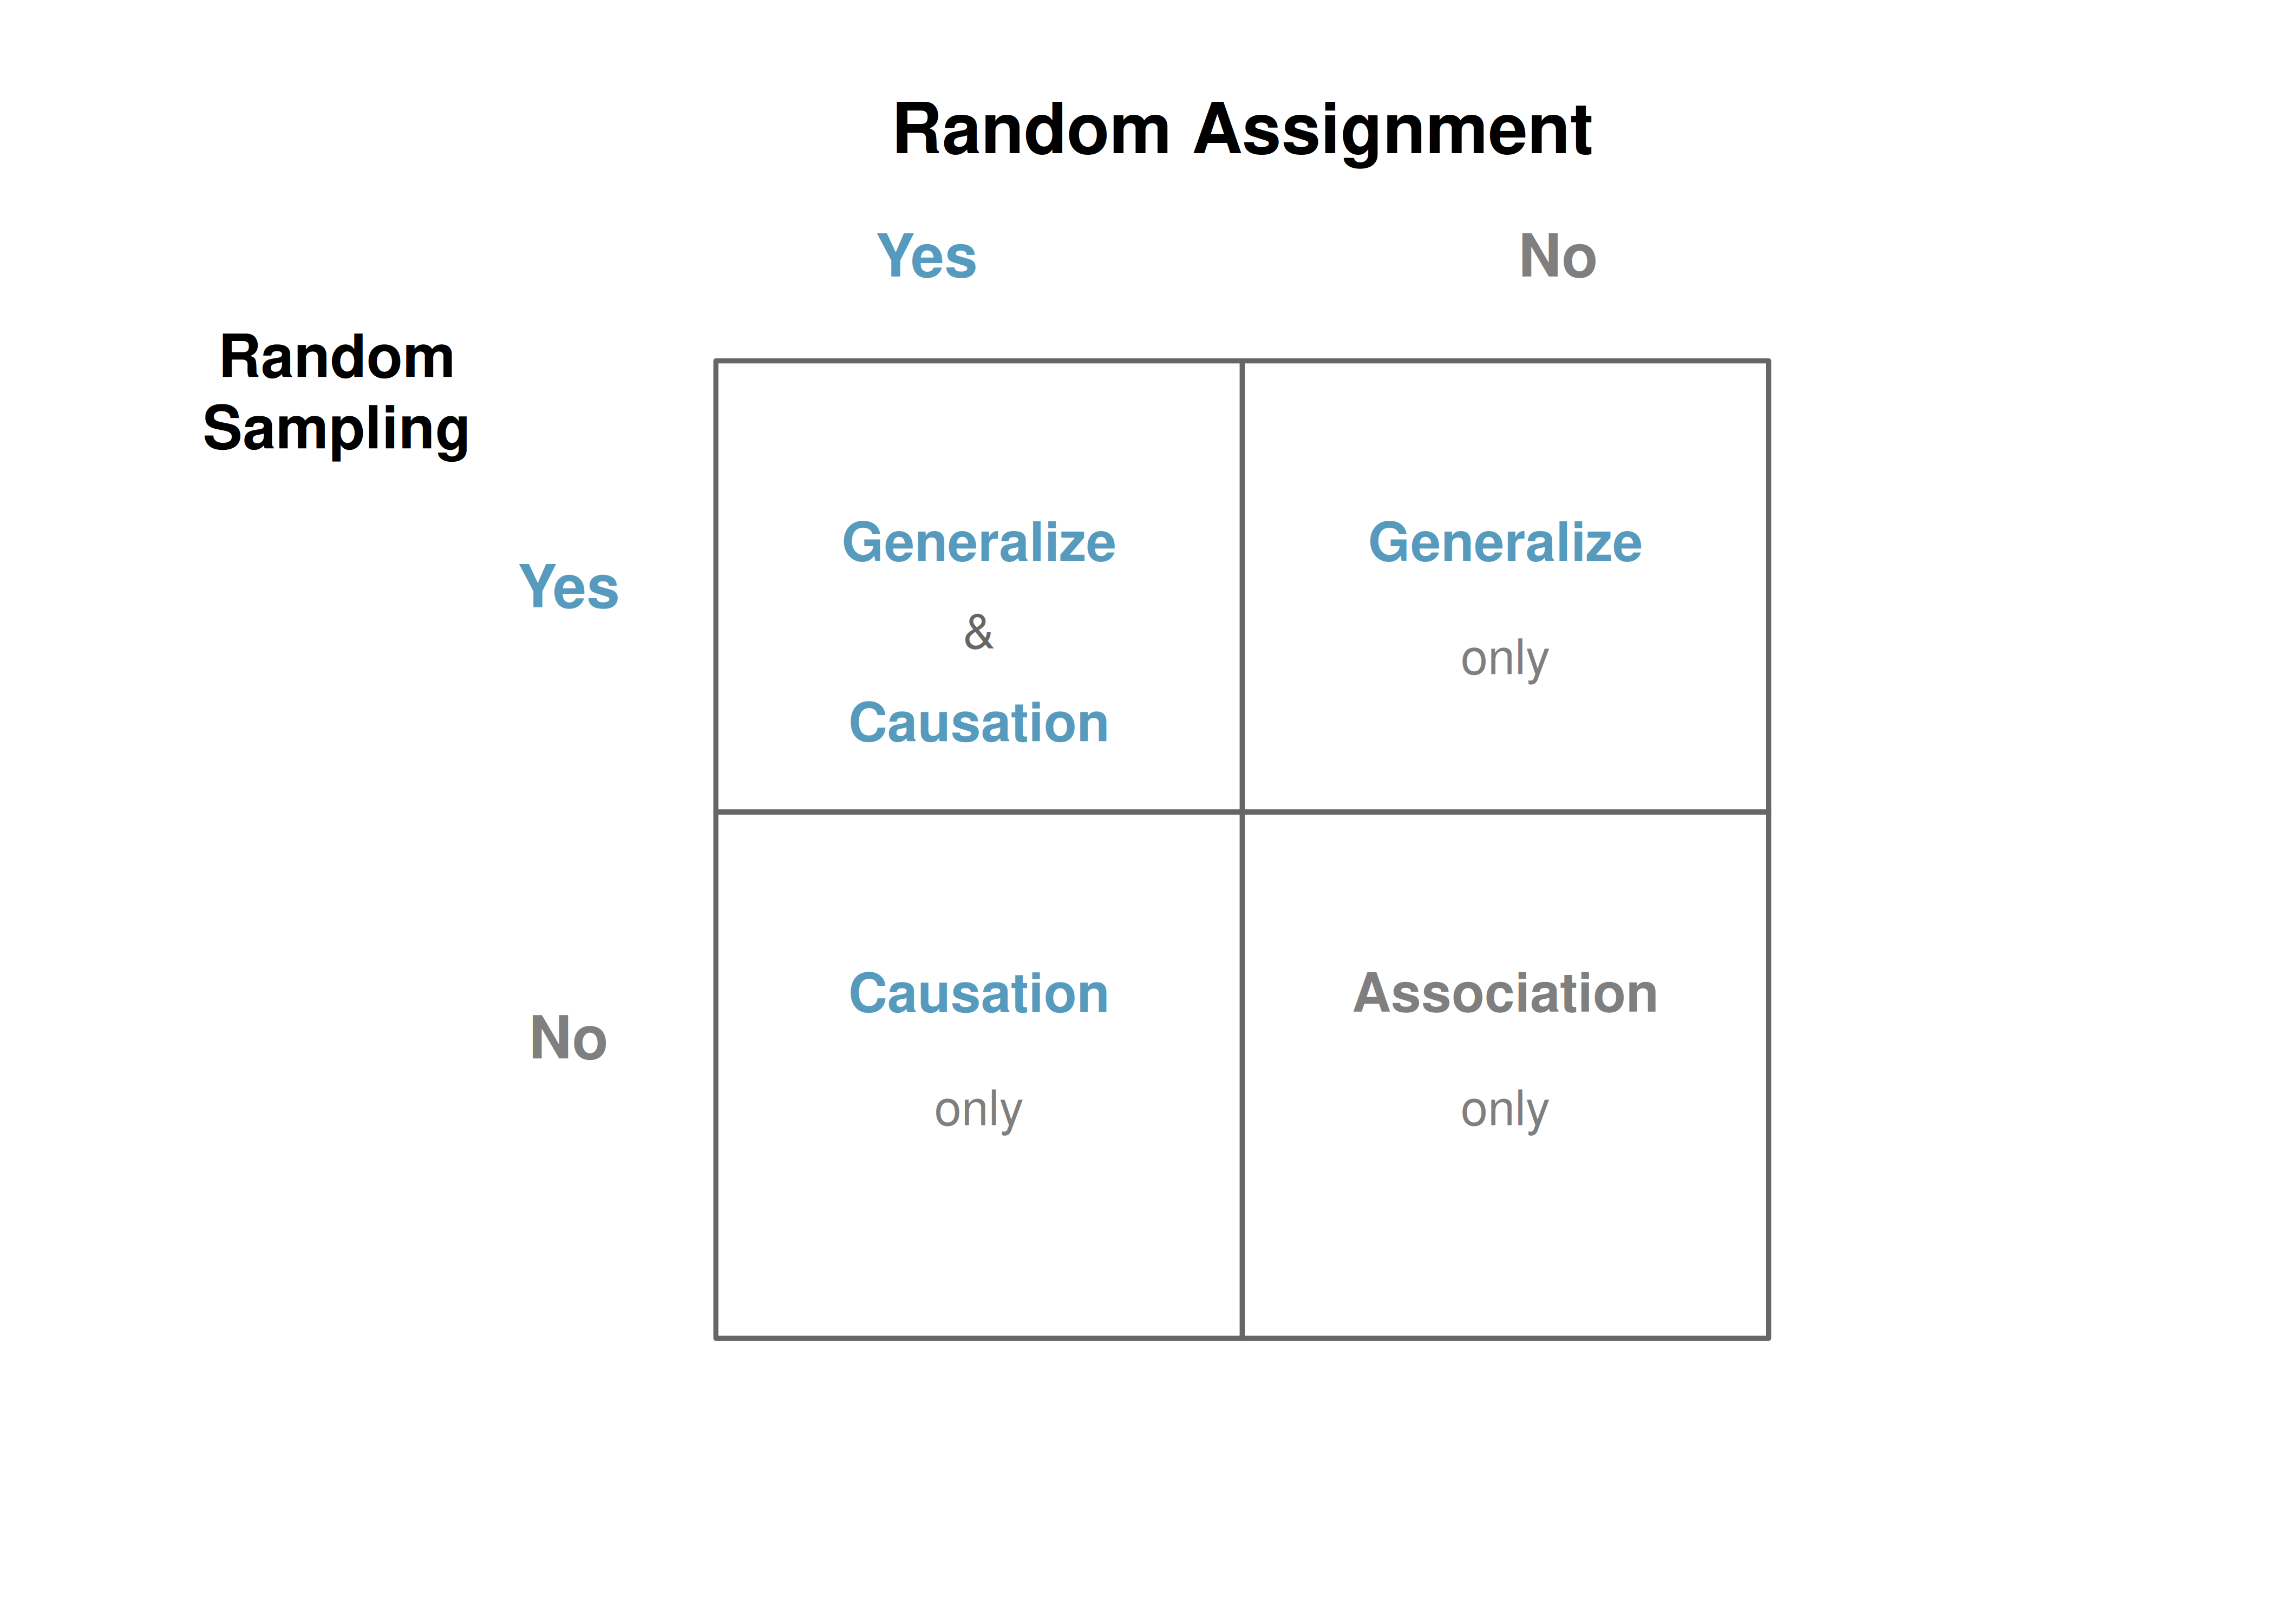
Very few studies achieve both random sampling and random assignment. In practice, experiments typically use volunteers (not random samples from the population), so they fall in the bottom-left cell: they can establish causation, but the results may not generalize beyond the type of people who volunteered. Observational studies based on random samples (top-right cell) can generalize to the population but cannot establish cause-and-effect.
A researcher randomly selects 500 adults from a city’s voter rolls and surveys them about exercise habits and depression symptoms. She finds that people who exercise more report fewer depression symptoms. What conclusions can she draw?
Show answer
Because the researcher used random sampling (from the voter rolls), she can generalize her findings to the city’s adult voter population. However, because she did not randomly assign people to exercise or not exercise (this is an observational study), she cannot conclude that exercise causes fewer depression symptoms. There may be confounding variables — for example, people with fewer depression symptoms may be more motivated to exercise in the first place.A pharmaceutical company recruits 200 volunteers with chronic pain and randomly assigns half to receive a new pain medication and half to receive a placebo. The group receiving the medication reports substantially less pain. What is the scope of inference?
Show answer
Because the study used random assignment, the company can conclude that the medication caused the reduction in pain (a causal conclusion). However, because the participants were volunteers rather than a random sample of all chronic pain patients, the results may not generalize to the entire population of chronic pain sufferers — only to people similar to those who volunteered.2.9 Chapter review
2.9.1 Summary
In this chapter, we explored how data are collected and why the method of collection matters for the conclusions we can draw.
Key concepts:
- The population is the entire group of interest; a sample is a subset from which we collect data. A census collects data on every member of the population but is usually impractical.
- Anecdotal evidence — conclusions drawn from one or a few non-representative cases — is unreliable.
- Random sampling methods include simple random sampling, stratified sampling, cluster sampling, and multistage sampling. All four use randomization — they differ in how the population is organized before the random draw. Each has advantages depending on the population’s structure and practical constraints.
- Bias comes in two kinds. Sampling bias comes from how cases are selected — convenience samples and voluntary response. Non-sampling bias arises after selection — non-response and response bias. A perfect random sample is no protection against the second kind.
- In an experiment, researchers actively assign treatments to subjects. In an observational study, researchers simply observe without intervening.
- Random assignment to treatment groups is the key to establishing causation.
- Confounding variables are associated with both the explanatory and response variables and can create misleading associations.
- Blinding (single and double) and placebos help reduce bias in human experiments.
- The scope of inference depends on whether the study used random sampling (which enables generalization) and random assignment (which enables causal conclusions).
2.9.2 Key terms
| Term | Definition |
|---|---|
| Population | The entire group of individuals about which we want information |
| Sample | A subset of the population from which we collect data |
| Census | An attempt to collect data from every member of the population |
| Population parameter | A numerical summary of the entire population |
| Sample statistic | A numerical summary calculated from sample data |
| Anecdotal evidence | Data collected in a haphazard fashion, often representing unusual cases |
| Simple random sample (SRS) | A sample where every case has an equal chance of selection, independently |
| Stratified sampling | Dividing the population into strata, then taking an SRS within each |
| Cluster sampling | Randomly selecting entire clusters and including all cases within them |
| Multistage sampling | Randomly selecting clusters, then taking an SRS within each selected cluster |
| Bias | Systematic favoritism in data collection that makes a sample unrepresentative |
| Sampling bias | Bias arising from how cases are selected into the sample |
| Convenience sample | A sample where easily accessible individuals are overrepresented |
| Voluntary response bias | Bias arising when people select themselves into the sample |
| Non-sampling bias | Bias arising after selection, from response or measurement |
| Non-response bias | Bias introduced when sampled individuals do not respond |
| Response bias | Bias introduced when the measurement itself distorts the answer |
| Experiment | A study where the researchers assign treatments to subjects |
| Randomized experiment | An experiment where treatments are assigned using randomization |
| Observational study | A study where researchers observe without assigning treatments |
| Confounding variable | A variable associated with both the explanatory and response variables |
| Treatment | A specific condition assigned to subjects; a value of the explanatory variable chosen by the researcher |
| Treatment group | The group receiving the experimental treatment |
| Control group | The group not receiving the treatment (or receiving a placebo) |
| Placebo | A fake treatment given to the control group |
| Placebo effect | Improvement in patients who believe they are receiving treatment |
| Blind (single-blind) | Subjects do not know their treatment assignment |
| Double-blind | Neither subjects nor researchers know the treatment assignments |
| Blocking | Grouping subjects by a known variable before random assignment |
| Prospective study | An observational study that follows subjects forward in time |
| Retrospective study | An observational study that looks back at past data |
| Scope of inference | The extent to which study results can be generalized and/or support causal claims |
2.10 Exercises
Answers to odd-numbered exercises are provided in the Exercise Solutions appendix at the back of the book.
- Parameters and statistics. Identify which value represents the sample mean and which value represents the claimed population mean.
American households spent an average of about $52 in 2007 on Halloween merchandise such as costumes, decorations and candy. To see if this number had changed, researchers conducted a new survey in 2008 before industry numbers were reported. The survey included 1,500 households and found that average Halloween spending was $58 per household.
The average GPA of students in 2001 at a private university was 3.37. A survey on a sample of 203 students from this university yielded an average GPA of 3.59 a decade later.
- Sleeping in college. A recent article in a college newspaper stated that college students get an average of 5.5 hrs of sleep each night. A student who was skeptical about this value decided to conduct a survey by randomly sampling 25 students. On average, the sampled students slept 6.25 hours per night. Identify which value represents the sample mean and which value represents the claimed population mean.
- Air pollution and birth outcomes, scope of inference. Researchers collected data to examine the relationship between air pollutants and preterm births in Southern California. During the study air pollution levels were measured by air quality monitoring stations. Length of gestation data were collected on 143,196 births between the years 1989 and 1993, and air pollution exposure during gestation was calculated for each birth. (Ritz et al. 2000)
Identify the population of interest and the sample in this study.
Comment on whether the results of the study can be generalized to the population, and if the findings of the study can be used to establish causal relationships.
- Cheaters, scope of inference. Researchers studying the relationship between honesty, age and self-control conducted an experiment on 160 children between the ages of 5 and 15. The researchers asked each child to toss a fair coin in private and to record the outcome (white or black) on a paper sheet, and said they would only reward children who report white. Half the students were explicitly told not to cheat and the others were not given any explicit instructions. Differences were observed in the cheating rates in the instruction and no instruction groups, as well as some differences across children’s characteristics within each group. (Bucciol and Piovesan 2011)
Identify the population of interest and the sample in this study.
Comment on whether the results of the study can be generalized to the population, and if the findings of the study can be used to establish causal relationships.
- Gamification and statistics, scope of inference. Researchers investigating the effects of gamification (application of game-design elements and game principles in non-game contexts) on learning statistics randomly assigned 365 college students in a statistics course to one of four groups; one of these groups had no reading exercises and no gamification, one group had reading but no gamification, one group had gamification but no reading, and a final group had gamification and reading. Students in all groups also attended lectures. The study found that gamification had a positive impact on student learning compared to traditional teaching methods involving reading exercises. (Legaki et al. 2020)
Identify the population of interest and the sample in this study.
Comment on whether the results of the study can be generalized to the population, and if the findings of the study can be used to establish causal relationships.
- Stealers, scope of inference. In a study of the relationship between socio-economic class and unethical behavior, 129 University of California undergraduates at Berkeley were asked to identify themselves as having low or high social-class by comparing themselves to others with the most (least) money, most (least) education, and most (least) respected jobs. They were also presented with a jar of individually wrapped candies and informed that the candies were for children in a nearby laboratory, but that they could take some if they wanted. After completing some unrelated tasks, participants reported the number of candies they had taken. It was found that those who were identified as upper-class took more candy than others. (Piff et al. 2012)
Identify the population of interest and the sample in this study.
Comment on whether the results of the study can be generalized to the population, and if the findings of the study can be used to establish causal relationships.
- Relaxing after work. The General Social Survey asked the question, “After an average work day, about how many hours do you have to relax or pursue activities that you enjoy?” to a random sample of 1,155 Americans. The average relaxing time was found to be 1.65 hours. Determine which of the following is an observation, a variable, a sample statistic, or a population parameter.
An American in the sample.
Number of hours spent relaxing after an average work day.
1.65.
Average number of hours all Americans spend relaxing after an average work day.
- Cats on YouTube. Suppose you want to estimate the percentage of videos on YouTube that are cat videos. It is impossible for you to watch all videos on YouTube so you use a random video picker to select 1000 videos for you. You find that 2% of these videos are cat videos. Determine which of the following is an observation, a variable, a sample statistic, or a population parameter.
Percentage of all videos on YouTube that are cat videos.
2%.
A video in your sample.
whether a video is a cat video.
- Course satisfaction across sections. A large college class has 160 students. All 160 students attend the lectures together, but the students are divided into 4 groups, each of 40 students, for lab sections administered by different teaching assistants. The professor wants to conduct a survey about how satisfied the students are with the course, and he believes that the lab section a student is in might affect the student’s overall satisfaction with the course.
What type of study is this?
Suggest a sampling strategy for carrying out this study.
- Housing proposal across dorms. On a large college campus first-year students and sophomores live in dorms located on the eastern part of the campus and juniors and seniors live in dorms located on the western part of the campus. Suppose you want to collect student opinions on a new housing structure the college administration is proposing and you want to make sure your survey equally represents opinions from students from all years.
What type of study is this?
Suggest a sampling strategy for carrying out this study.
- Internet use and life expectancy. The following scatterplot was created as part of a study evaluating the relationship between estimated life expectancy at birth (as of 2014) and percentage of internet users (as of 2009) in 208 countries for which such data were available.
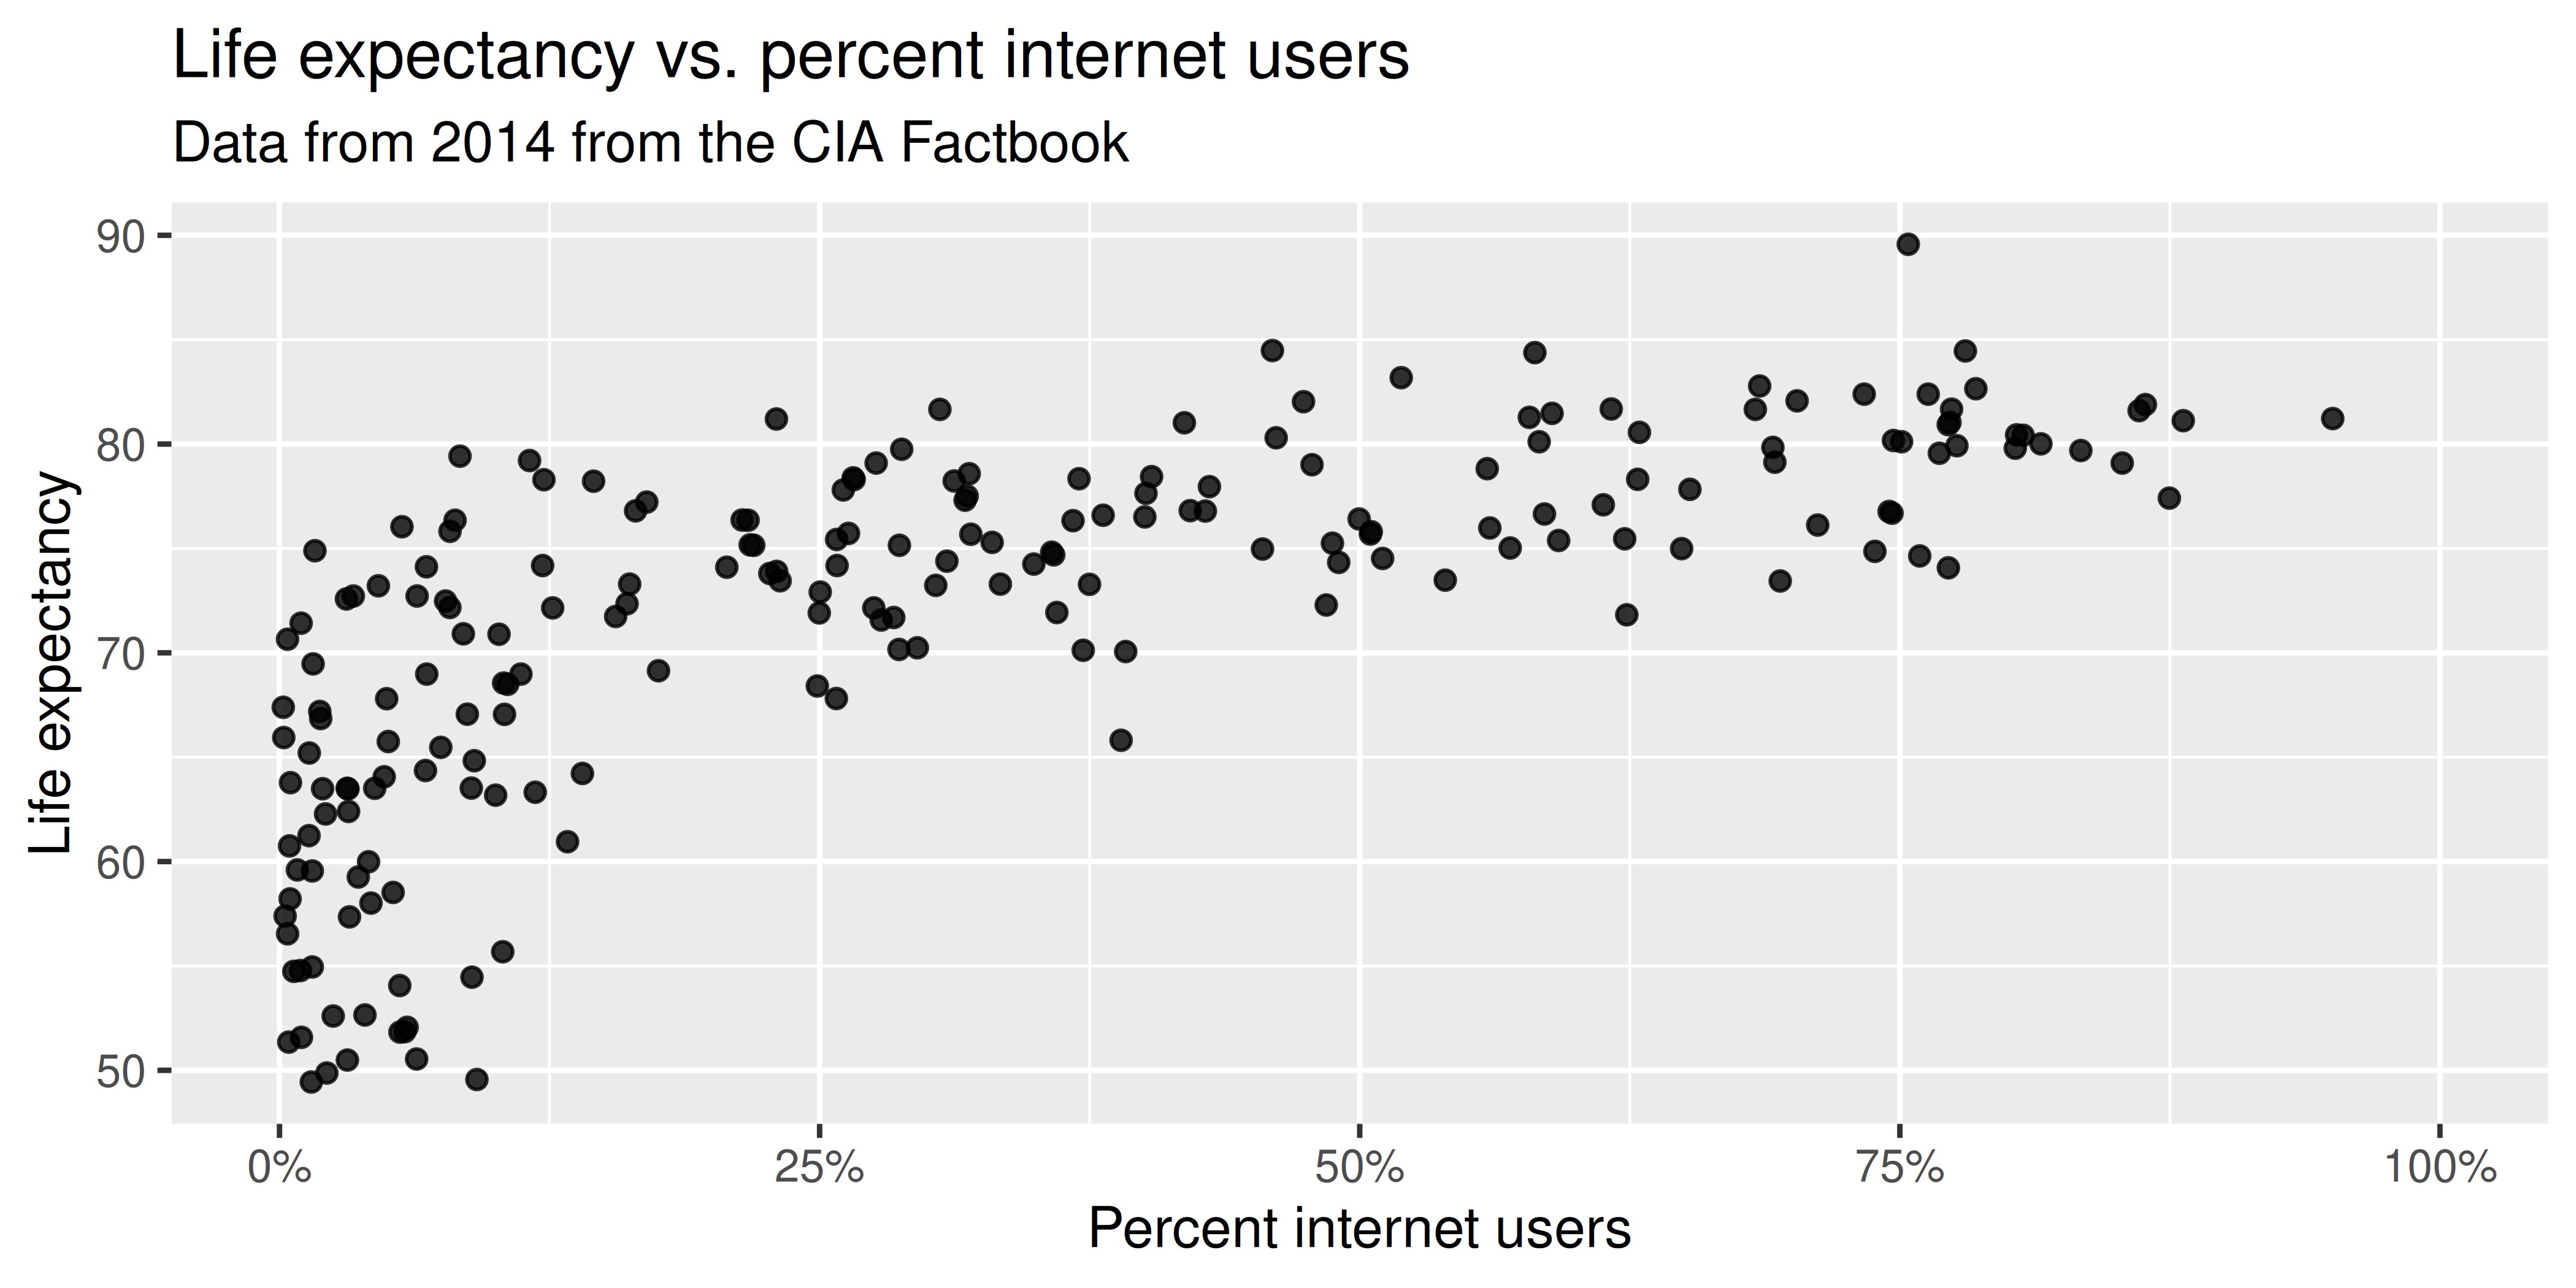
Describe the relationship between life expectancy and percentage of internet users.
What type of study is this?
State a possible confounding variable that might explain this relationship and describe its potential effect.
- Stressed out. A study that surveyed a random sample of otherwise healthy high school students found that they are more likely to get muscle cramps when they are stressed. The study also noted that students drink more coffee and sleep less when they are stressed.
What type of study is this?
Can this study be used to conclude a causal relationship between increased stress and muscle cramps?
State possible confounding variables that might explain the observed relationship between increased stress and muscle cramps.
- Evaluate sampling methods. A university wants to determine what fraction of its undergraduate student body support a new $25 annual fee to improve the student union. For each proposed method below, indicate whether the method is reasonable or not.
Survey a simple random sample of 500 students.
Stratify students by their field of study, then sample 10% of students from each stratum.
Cluster students by their ages (e.g., 18 years old in one cluster, 19 years old in one cluster, etc.), then randomly sample three clusters and survey all students in those clusters.
- Random digit dialing. The Gallup Poll uses a procedure called random digit dialing, which creates phone numbers based on a list of all area codes in America in conjunction with the associated number of residential households in each area code. Give a possible reason the Gallup Poll chooses to use random digit dialing instead of picking phone numbers from the phone book.
- Haters are gonna hate, study confirms. A study published in the Journal of Personality and Social Psychology asked a group of 200 randomly sampled participants recruited online using Amazon’s Mechanical Turk to evaluate how they felt about various subjects, such as camping, health care, architecture, taxidermy, crossword puzzles, and Japan in order to measure their attitude towards mostly independent stimuli. Then, they presented the participants with information about a new product: a microwave oven. This microwave oven does not exist, but the participants didn’t know this, and were given three positive and three negative fake reviews. People who reacted positively to the subjects on the dispositional attitude measurement also tended to react positively to the microwave oven, and those who reacted negatively tended to react negatively to it. Researchers concluded that “some people tend to like things, whereas others tend to dislike things, and a more thorough understanding of this tendency will lead to a more thorough understanding of the psychology of attitudes.” (Hepler and Albarracı́n 2013)
What are the cases?
What is (are) the response variable(s) in this study?
What is (are) the explanatory variable(s) in this study?
Does the study employ random sampling? Explain your reasoning.
Is this an observational study or an experiment? Explain your reasoning.
Can we establish a causal link between the explanatory and response variables?
Can the results of the study be generalized to the population at large?
- Reading the paper. Below are excerpts from two articles published in the NY Times:
- An excerpt from an article titled Risks: Smokers Found More Prone to Dementia is below. Based on this study, can we conclude that smoking causes dementia later in life? Explain your reasoning. (Rabin 2010)
“Researchers analyzed data from 23,123 health plan members who participated in a voluntary exam and health behavior survey from 1978 to 1985, when they were 50-60 years old. 23 years later, about 25% of the group had dementia, including 1,136 with Alzheimer’s disease and 416 with vascular dementia. After adjusting for other factors, the researchers concluded that pack-a-day smokers were 37% more likely than nonsmokers to develop dementia, and the risks went up with increased smoking; 44% for one to two packs a day; and twice the risk for more than two packs.”
- An excerpt from an article titled The School Bully Is Sleepy is below. A friend of yours who read the article says, “The study shows that sleep disorders lead to bullying in school children.” Is this statement justified? If not, how best can you describe the conclusion that can be drawn from this study? (Parker-Pope 2011)
“The University of Michigan study, collected survey data from parents on each child’s sleep habits and asked both parents and teachers to assess behavioral concerns. About a third of the students studied were identified by parents or teachers as having problems with disruptive behavior or bullying. The researchers found that children who had behavioral issues and those who were identified as bullies were twice as likely to have shown symptoms of sleep disorders.”
- Sampling strategies. A statistics student who is curious about the relationship between the amount of time students spend on social networking sites and their performance at school decides to conduct a survey. Various research strategies for collecting data are described below. In each, name the sampling method proposed and any bias you might expect.
They randomly sample 40 students from the study’s population, give them the survey, ask them to fill it out, and bring it back the next day.
They give out the survey only to their friends, making sure each one of them fills it out.
They post a link to an online survey on Facebook and ask their friends to fill it out.
They randomly sample 5 classes and asks a random sample of students from those classes to fill out the survey.
- Family size. Suppose we want to estimate household size, where a “household” is defined as people living together in the same dwelling, and sharing living accommodations. If we select students at random at an elementary school and ask them what their family size is, will this be a good measure of household size? Or will our average be biased? If so, will it overestimate or underestimate the true value?
- Light and exam performance. A study is designed to test the effect of light level on exam performance of students. The researcher believes that light levels might have different effects on people who wear glasses and people who don’t, so they want to make sure both groups of people are equally represented in each treatment. The treatments are fluorescent overhead lighting, yellow overhead lighting, no overhead lighting (only desk lamps).
What is the response variable?
What is the explanatory variable? What are its levels?
What is the blocking variable? What are its levels?
- Vitamin supplements. To assess the effectiveness of taking large doses of vitamin C in reducing the duration of the common cold, researchers recruited 400 healthy volunteers from staff and students at a university. A quarter of the patients were assigned a placebo, and the rest were evenly divided between 1g Vitamin C, 3g Vitamin C, or 3g Vitamin C plus additives to be taken at onset of a cold for the following two days. All tablets had identical appearance and packaging. The nurses who handed the prescribed pills to the patients knew which patient received which treatment, but the researchers assessing the patients when they were sick did not. No statistically discernible differences were observed in any measure of cold duration or severity between the four groups, and the placebo group had the shortest duration of symptoms. (Audera et al. 2001)
Was this an experiment or an observational study? Why?
What are the explanatory and response variables in this study?
Were the patients blinded to their treatment?
Was this study double-blind?
Participants are ultimately able to choose whether to use the pills prescribed to them. We might expect that not all of them will adhere and take their pills. Does this introduce a confounding variable to the study? Explain your reasoning.
- Light, noise, and exam performance. A study is designed to test the effect of light level and noise level on exam performance of students. The researcher believes that light and noise levels might have different effects on people who wear glasses and people who don’t, so they want to make sure both groups of people are equally represented in each treatment. The light treatments considered are fluorescent overhead lighting, yellow overhead lighting, no overhead lighting (only desk lamps). The noise treatments considered are no noise, construction noise, and human chatter noise.
What type of study is this?
How many factors are considered in this study? Identify them, and describe their levels.
What is the role of the wearing glasses variable in this study?
- Music and learning. You would like to conduct an experiment in class to see if students learn better if they study without any music, with music that has no lyrics (instrumental), or with music that has lyrics. Briefly outline a design for this study.
- Soda preference. You would like to conduct an experiment in class to see if your classmates prefer the taste of regular Coke or Diet Coke. Briefly outline a design for this study.
- Exercise and mental health. A researcher is interested in the effects of exercise on mental health and they propose the following study: use stratified random sampling to ensure representative proportions of 18-30, 31-40 and 41- 55 year-olds from the population. Next, randomly assign half the subjects from each age group to exercise twice a week, and instruct the rest not to exercise. Conduct a mental health exam at the beginning and at the end of the study, and compare the results.
What type of study is this?
What are the treatment and control groups in this study?
Does this study make use of blocking? If so, what is the blocking variable?
Does this study make use of blinding?
Comment on whether the results of the study can be used to establish a causal relationship between exercise and mental health, and indicate whether the conclusions can be generalized to the population at large.
Suppose you are given the task of determining if this proposed study should get funding. Would you have any reservations about the study proposal?
- Chia seeds and weight loss. Chia Pets – those terra-cotta figurines that sprout fuzzy green hair – made the chia plant a household name. But chia has since gained a reputation as a diet supplement. In one 2009 study, 38 men and 38 women were recruited and and divided each randomly into two groups: treatment or control. One group was given 25 grams of chia seeds twice a day, and the other was given a placebo. The subjects volunteered to be a part of the study. After 12 weeks, the scientists found no statistically discernible difference between the groups in appetite or weight loss. (Nieman et al. 2009)
What type of study is this?
What are the experimental and control treatments in this study?
Has blocking been used in this study? If so, what is the blocking variable?
Has blinding been used in this study?
Comment on whether we can make a causal statement, and indicate whether we can generalize the conclusion to the population at large.
- City council survey. A city council has requested a household survey be conducted in a suburban area of their city. The area is broken into many distinct and unique neighborhoods, some including large homes, some with only apartments, and others a diverse mixture of housing structures. For each part below, identify the sampling methods described, and describe the statistical pros and cons of the method in the city’s context.
Randomly sample 200 households from the city.
Divide the city into 20 neighborhoods, and then sample 10 households from each neighborhood.
Divide the city into 20 neighborhoods, randomly sample 3 neighborhoods, and then sample all households from those 3 neighborhoods.
Divide the city into 20 neighborhoods, randomly sample 8 neighborhoods, and then randomly sample 50 households from those neighborhoods.
Sample the 200 households closest to the city council offices.
- Flawed reasoning. Identify the flaw(s) in reasoning in the following scenarios. Explain what the individuals in the study should have done differently if they wanted to make such strong conclusions.
Students at an elementary school are given a questionnaire that they are asked to return after their parents have completed it. One of the questions asked is, “Do you find that your work schedule makes it difficult for you to spend time with your kids after school?” Of the parents who replied, 85% said “no”. Based on these results, the school officials conclude that a great majority of the parents have no difficulty spending time with their kids after school.
A survey is conducted on a simple random sample of 1,000 women who recently gave birth, asking them about whether they smoked during pregnancy. A follow-up survey asking if the children have respiratory problems is conducted 3 years later. However, only 567 of these women are reached at the same address. The researcher reports that these 567 women are representative of all mothers.
An orthopedist administers a questionnaire to 30 of his patients who do not have any joint problems and finds that 20 of them regularly go running. He concludes that running decreases the risk of joint problems.
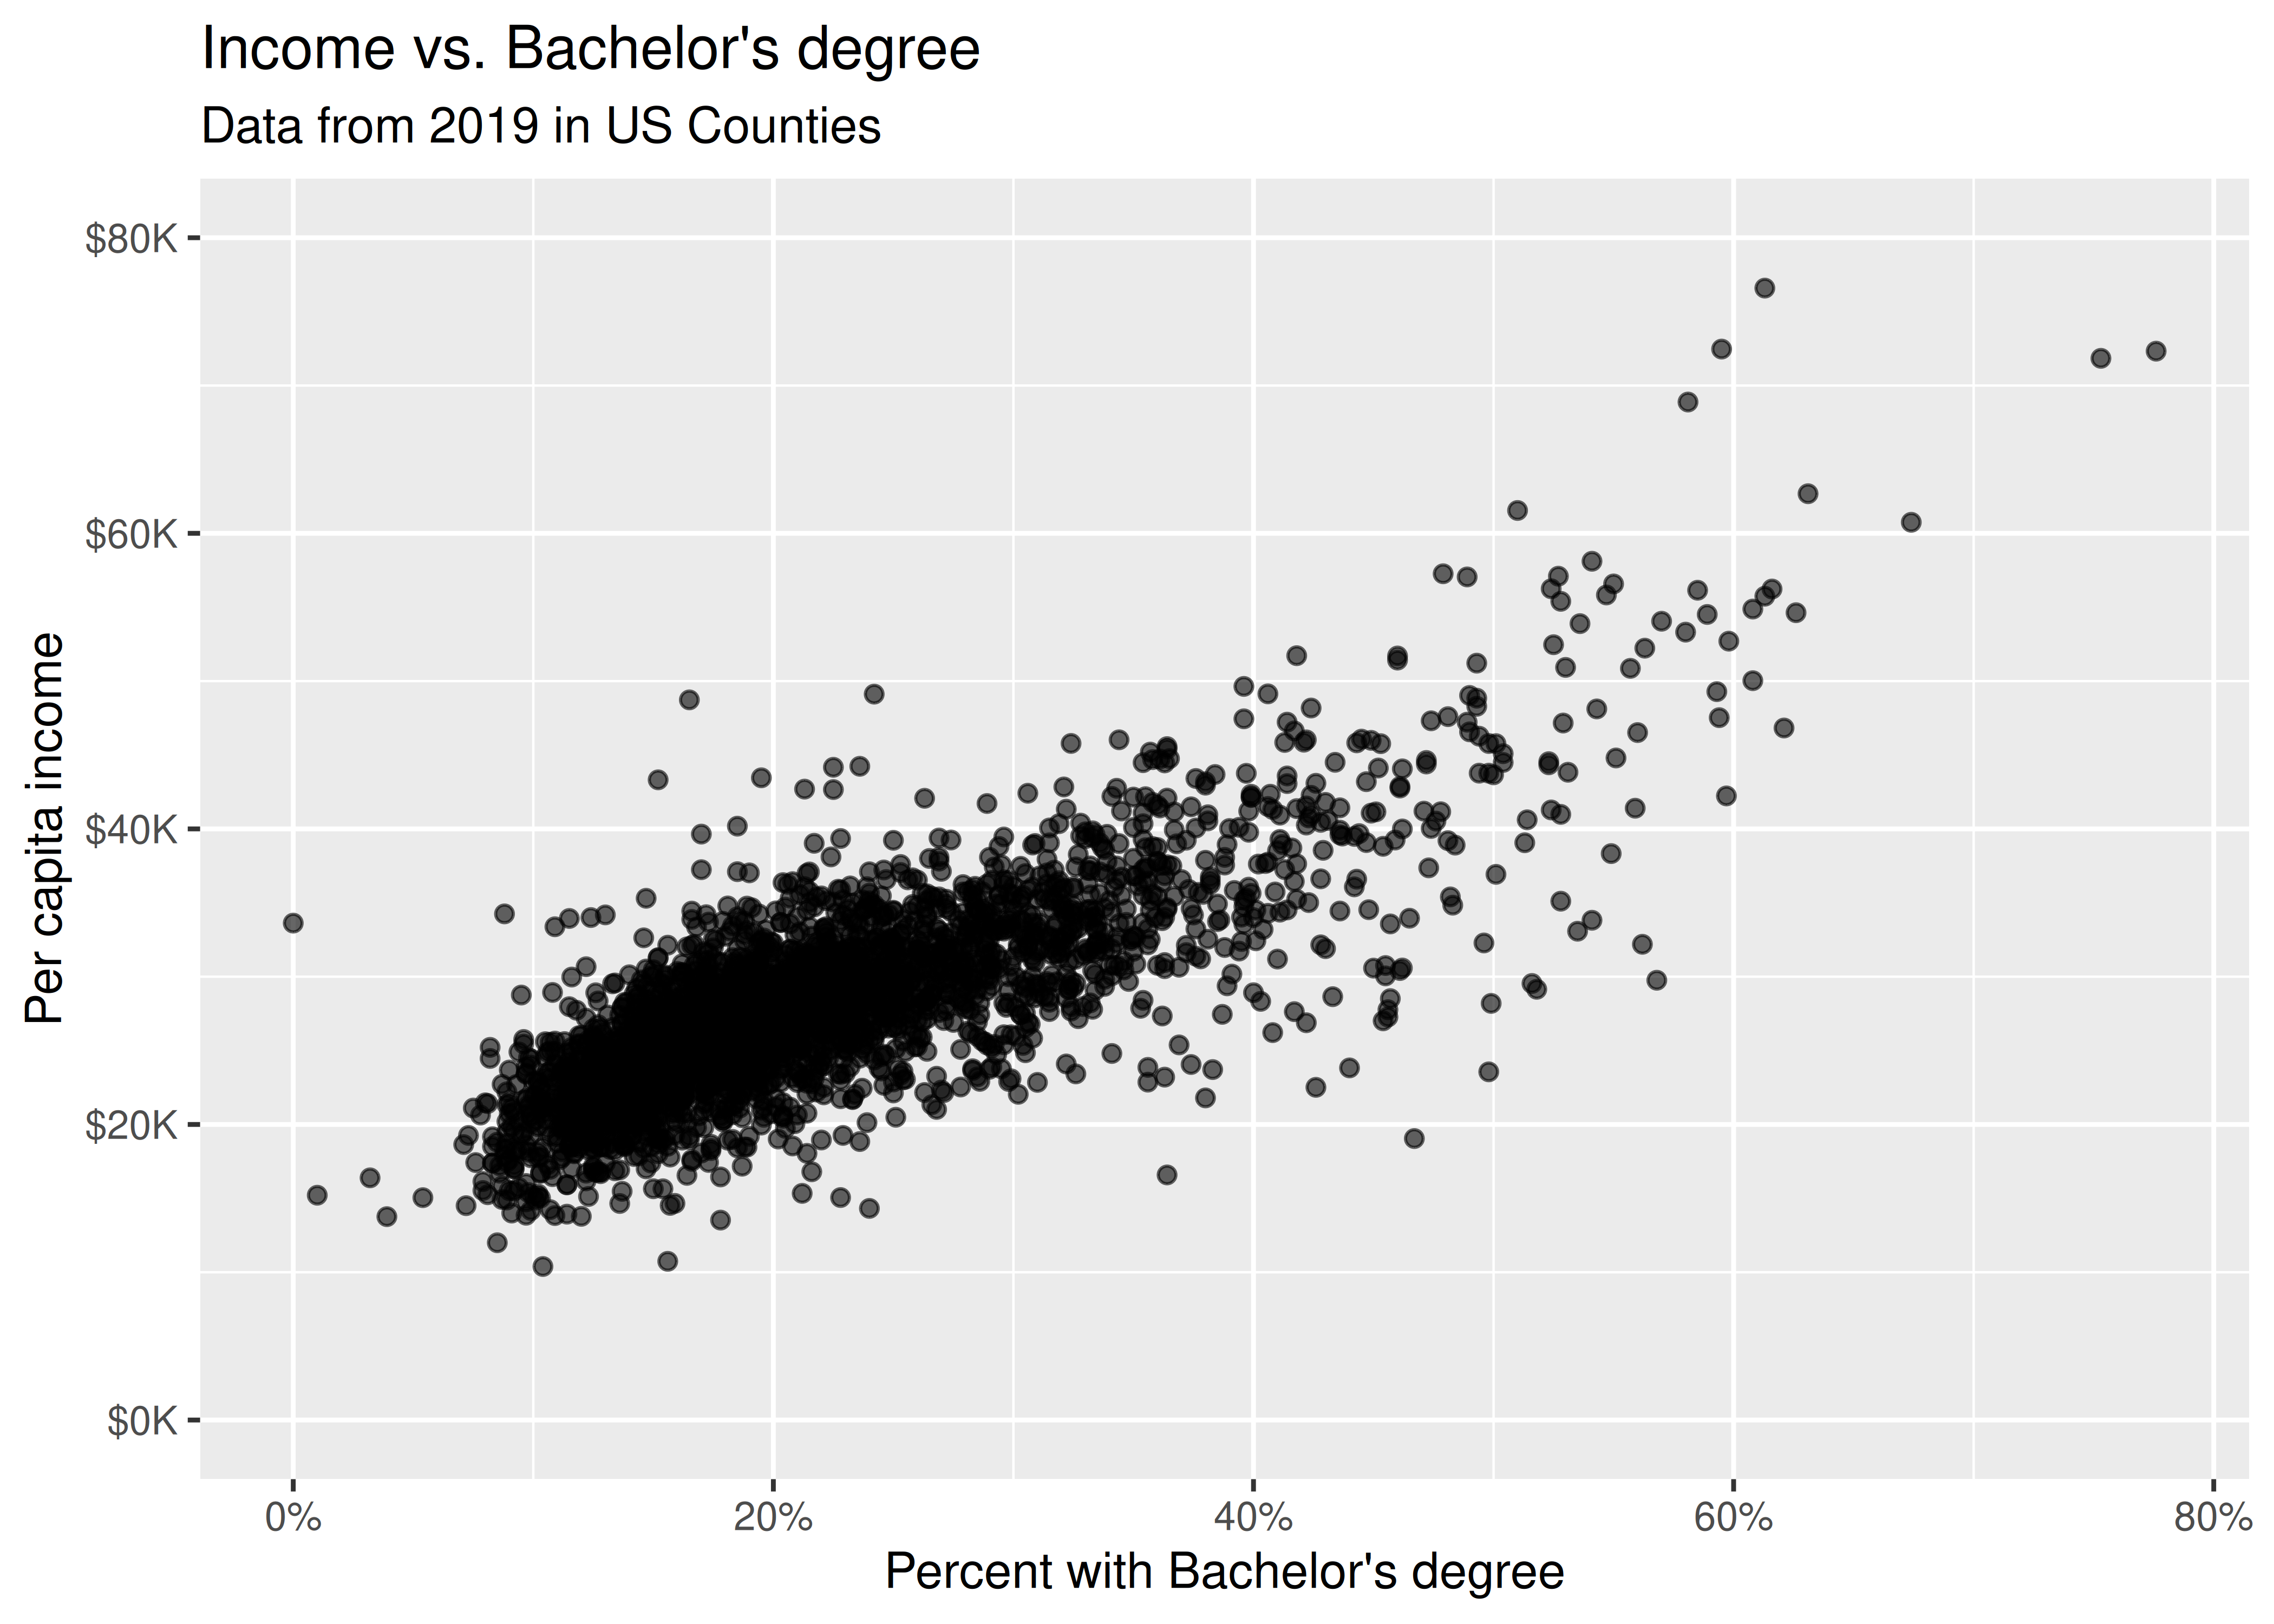
- Income and education in US counties. The scatterplot below shows the relationship between per capita income (in thousands of dollars) and percent of population with a bachelor’s degree in 3,142 counties in the US in 2019.
What are the explanatory and response variables?
Describe the relationship between the two variables. Make sure to discuss unusual observations, if any.
Can we conclude that having a bachelor’s degree increases one’s income?
- Eat well, feel better. In a public health study on the effects of consumption of fruits and vegetables on psychological well-being in young adults, participants were randomly assigned to three groups: (1) diet-as-usual, (2) an ecological momentary intervention involving text message reminders to increase their fruits and vegetable consumption plus a voucher to purchase them, or (3) a fruit and vegetable intervention in which participants were given two additional daily servings of fresh fruits and vegetables to consume on top of their normal diet. Participants were asked to take a nightly survey on their smartphones. Participants were student volunteers at the University of Otago, New Zealand. At the end of the 14-day study, only participants in the third group showed improvements to their psychological well-being across the 14-days relative to the other groups. (Conner et al. 2017)
What type of study is this?
Identify the explanatory and response variables.
Comment on whether the results of the study can be generalized to the population.
Comment on whether the results of the study can be used to establish causal relationships.
A newspaper article reporting on the study states, “The results of this study provide proof that giving young adults fresh fruits and vegetables to eat can have psychological benefits, even over a brief period of time.” How would you suggest revising this statement so that it can be supported by the study?
- Screens, teens, and psychological well-being. In a study of three nationally representative large-scale datasets from Ireland, the United States, and the United Kingdom (n = 17,247), teenagers between the ages of 12 to 15 were asked to keep a diary of their screen time and answer questions about how they felt or acted. The answers to these questions were then used to compute a psychological well-being score. Additional data were collected and included in the analysis, such as each child’s sex and age, and on the mother’s education, ethnicity, psychological distress, and employment. The study concluded that there is little clear-cut evidence that screen time decreases adolescent well-being. (Orben and Baukney-Przybylski 2018)
What type of study is this?
Identify the explanatory variables.
Identify the response variable.
Comment on whether the results of the study can be generalized to the population, and why.
Comment on whether the results of the study can be used to establish causal relationships.
Audera, C., R. V. Patulny, Sander B. H, and R. M. Douglas. 2001. “Mega-Dose Vitamin c in Treatment of the Common Cold: A Randomised Controlled Trial.” Medical Journal of Australia 175 (7): 359–62. http://www.openintro.org/redirect.php?go=textbook-vitamin_C_cold_treatment_2001.
Bucciol, Alessandro, and Marco Piovesan. 2011. “Luck or Cheating? A Field Experiment on Honesty with Children.” Journal of Economic Psychology 32 (1): 73–78. https://doi.org/10.1016/j.joep.2010.12.001.
Conner, T. S., K. L. Brookie, A. C. Carr, L. A. Mainvil, and M. CM. Vissers. 2017. “Let Them Eat Fruit! The Effect of Fruit and Vegetable Consumption on Psychological Well-Being in Young Adults: A Randomized Controlled Trial.” PloS One 12 (2). https://doi.org/10.1371/journal.pone.0171206.
Hepler, J., and D. Albarracı́n. 2013. “Attitudes Without Objects: Evidence for a Dispositional Attitude, Its Measurement, and Its Consequences.” Journal of Personality and Social Psychology 104 (6): 1060. https://doi.org/10.1037/a0032282.
Legaki, Nikoletta-Zampeta, Nannan Xi, Juho Hamari, Kostas Karpouzis, and Vassilios Assimakopoulos. 2020. “The Effect of Challenge-Based Gamification on Learning: An Experiment in the Context of Statistics Education.” International Journal of Human-Computer Studies 144. https://doi.org/10.1016/j.ijhcs.2020.102496.
Nieman, D. C., E. J. Cayea, M. D. Austin, D. A. Henson, S. R. McAnulty, and F. Jin. 2009. “Chia Seed Does Not Promote Weight Loss or Alter Disease Risk Factors in Overweight Adults.” Nutrition Research 29 (6): 414–18. https://doi.org/10.1016/j.nutres.2009.05.011.
Orben, A., and A. K. Baukney-Przybylski. 2018. “Screens, Teens and Psychological Well-Being: Evidence from Three Time-Use Diary Studies.” Psychological Science. https://doi.org/10.1177/0956797619830329.
Parker-Pope, T. 2011. “The School Bully Is Sleepy.” New York Times. http://www.openintro.org/redirect.php?go=textbook-school_bully_sleepy_2011.
Piff, P. K., D. M. Stancato, S. Côté, R. Mendoza-Denton, and D. Keltner. 2012. “Higher Social Class Predicts Increased Unethical Behavior.” Proceedings of the National Academy of Sciences. https://doi.org/10.1073/pnas.1118373109.
Rabin, R. C. 2010. “Risks: Smokers Found More Prone to Dementia.” New York Times. http://www.openintro.org/redirect.php?go=textbook-nytimes_smoking_dementia.
Ritz, B., F. Yu, G. Chapa, and S. Fruin. 2000. “Effect of Air Pollution on Preterm Birth Among Children Born in Southern California Between 1989 and 1993.” Epidemiology 11 (5): 502–11. http://www.jstor.org/stable/3703990.
Why blocking? The term comes from agricultural experiments, where researchers literally divided a field into relatively homogeneous blocks of plots and randomized treatments within each block. It is a useful coincidence that the procedure also “blocks out” some nuisance variation, but that does not appear to be the historical origin of the word. (Suggested by Todd Will.) For instance, in studying the effect of a drug on heart attacks, researchers might first split patients into low-risk and high-risk blocks, then randomly assign half the patients from each block to the treatment and half to the control group.↩︎